
SeaweedFS is a scalable distributed file system optimized for exabyte small files, supports FUSE, S3 API, Hadoop, k8s, replication, Cloud Drive, S3 gateway.
San Francisco
Joined March 2020
- Tweets357
- Following433
- Followers966
- Likes91






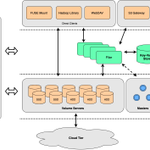
One table. Multiple query engines.
SeaweedFS Table Buckets expose standard Iceberg REST + S3, so the query engine is your choice.
Comparing:
* Trino for distributed SQL + writes
* DuckDB for embedded analytics
seaweedfs.com/blog/databow-t…
#SeaweedFS #ApacheIceberg #DuckDB #Trino
SeaweedFS retweeted

celld + alchemy + seaweedfs (s3)
using this heavy on local machines for alll sorts of crazy shit but particularly love pi-durable workflows it's unlocked github.com/joelhooks/alchemy…

SeaweedFS retweeted

For S3, I created a cheap VM with github.com/seaweedfs/seaweed… and use that for testing and development (orbs and local) in places where mocking/faking doesn't fit.

SeaweedFS retweeted

In PostgreSQL, a 1,000,000-row table starts at 152 MB in the heap. After the pgEdge ColdFront archiver runs, 958,056 of those rows sit as Parquet files in object storage and the hot heap is down to 6624 kB. The table name and the SQL stay the same.
ColdFront is open source (PostgreSQL License) data tiering for PostgreSQL 16, 17, and 18. It moves older partitions to Apache Iceberg on S3 and keeps that data queryable and writable.
In the new walkthrough, an UPDATE on an archived row lands directly in object storage, with no rehydration and no restore job. A lake-native table stores 0 bytes in Postgres and takes plain INSERT, UPDATE, and DELETE. Concurrent writers across two Postgres nodes with 0 conflicts, 0 Lakekeeper 409s, and 12 Iceberg snapshots for 12 writes.
There's no narration and every step is explained on screen, so pause anywhere to read the SQL. The demos run on a local Docker stack with SeaweedFS standing in for a cloud bucket.
Watch the walkthrough: 🎬 hubs.ly/Q04z8QhR0
ColdFront on GitHub: 🔗 hubs.ly/Q04z8QkL0
#postgres #postgresql #apacheiceberg #opensource #dataengineering #database #datalake #parquet #s3 #docker #pgedge #coldfront

SeaweedFS retweeted

It's time, we are switching our copy everywhere, and updating our tests, and recommendation for on prem s3 to @SeaweedFS, @Minio is history.
We are starting today with the tests in the repo.
github.com/Basekick-Labs/arc

Move from MinIO to SeaweedFS? It is just very simple and "works beautifully".
github.com/seaweedfs/seaweed…


SeaweedFS retweeted

It's, using celld and SeaweedFS for storage.
And it's a live multiplayer reaction game: a light flashes at the same instant for everyone on the page, timed by a Durable Object's own alarm. First click wins.
SeaweedFS Table Buckets can tier each part independently, automatically based on data temperature.
⚡ Metadata → replicated SSD
📦 Parquet data → HDD
🧊 Cold data → erasure coding / cloud
⚡ Parquet footers → cached back on SSD
seaweedfs.com/blog/volume-ti…
Why choose between Iceberg and Lance? You can analyze with Iceberg, and serve with Lance point lookups and vector search, with DuckDB joins them together.
SeaweedFS can host both table formats on the same object store, with built-in catalogs for each.
seaweedfs.com/blog/iceberg-l…
SeaweedFS retweeted

~@SeaweedFS has been absolutely vital to my development work on arkfile.net.
Self-hosting assumes the use of `local-seaweedfs` backend by default.
You can set up two buckets & replicate from primary to secondary as well. See: github.com/arkfile/Arkfile
SeaweedFS retweeted

This issue explains how @ApacheOpenDAL helps improve the overall community, alongside @SeaweedFS 😋
github.com/seaweedfs/seaweed…

SeaweedFS + Cloud
⚡ reads at local-disk latency
☁️ writes synced back to Cloud
With SeaweedFS, cloud S3 can remain the durable source of truth while SeaweedFS provides a nearby cache.
WALGit is a great example of this.
seaweedfs.com/blog/walgit-se…
SeaweedFS Table Buckets now support Lance 🚀
Use LanceDB directly on SeaweedFS for vector search, with data + indexes stored in S3.
Iceberg for analytics.
Lance for vectors.
One storage layer.
seaweedfs.com/blog/lancedb-t…
Git on S3 is hot. Running it on SeaweedFS for faster operations and no storage or access fees would be perfect.
xitter.cf/i/trending/20917221439…
SeaweedFS retweeted

for everyone glazing s3 right now, please go watch this talk from fmr Docker CTO during @CloudNativeFdn last yr titled “Object Storage is All You Need”
this is what got me objectstore-pilled back in 2024
youtu.be/ei0wwTy6_G4?si=72M7…
SeaweedFS has been available in Unraid Community Apps 🚀
Turn your Unraid server into an S3-compatible object store in just a few clicks - great for backups, self-hosted apps, homelabs, and MinIO migrations.
ca.unraid.net/apps/seaweedfs…
#SeaweedFS #Unraid #S3 #SelfHosted #Homelab

SeaweedFS retweeted

Somebody shared a design idea(forgot who), Isometric Map of codebase. Tried with seaweedfs codebase. Looks pleasing to the eyes. I think if I continue to iterate over it for more, can be made useful for understanding high level codebase and then drilling down. Need more visualization for drill down. What do you think?
Artifact link in the comment.

ClickHouse + SeaweedFS Table Buckets = an interoperable Iceberg lakehouse. 🧊
ClickHouse reads & writes. SeaweedFS fixes non-compliant Iceberg commits on the fly, so DuckDB, Spark, Trino & PyIceberg can read them too.
seaweedfs.com/blog/clickhous…
@ClickHouseDB @ApacheSpark @trinodb
SeaweedFS 4.41 added FUSE mount on windows:
github.com/seaweedfs/seaweed…
Welcome to check it out (and report bugs)!
