
Research Scientist @ Apple | CMU ML ~ code agents are cool
Joined August 2024
- Tweets10
- Following44
- Followers13
- Likes61
Ryan Shar ✈️ COLM retweeted

LLMs are much less capable judges for code than we might expect.
Super excited that our paper on LLM judges for code has been accepted to COLM! In it, we discuss this weakness and provide a pipeline for understanding and diagnosing issues with LLM code preferences.
This was led by two wonderful students @RyanShar01 and @AdityaM129. It was an absolute pleasure mentoring them on this project.

Ryan Shar ✈️ COLM retweeted
I will be presenting EDIT-Bench as an Oral at ICLR on Friday 4/23! Session 4D starts at 3:15 and the talk is at 3:39.
We will also be at poster session 3 in the morning.
See you all there!

Ryan Shar ✈️ COLM retweeted
New preprint alert 🚨
Can LLM agents develop video games?
We release GameDevBench, the first benchmark evaluating agentic game development in a game engine, Godot.
We also present two simple multimodal feedback mechanisms that lead to immediate performance gains.
/🧵
Ryan Shar ✈️ COLM retweeted
Tired of evaluating LLMs on made-up problems that look nothing like real tasks?
Introducing EDIT-Bench, a code editing benchmark built from in-the-wild user interactions in VSCode.
Real-world edits are challenging: 𝗼𝗻𝗹𝘆 𝟭/𝟰𝟬 𝗺𝗼𝗱𝗲𝗹𝘀 𝘀𝗰𝗼𝗿𝗲 > 𝟲𝟬% 𝗽𝗮𝘀𝘀@𝟭.

Ryan Shar ✈️ COLM retweeted

I’m excited to share new work from Datadog AI Research! We just released Toto, a new SOTA (by a wide margin!) time series foundation model, and BOOM, the largest benchmark of observability metrics. Both are available under the Apache 2.0 license. 🧵

Ryan Shar ✈️ COLM retweeted

Blog post on @CopilotArena out now!

blog.ml.cmu.edu/2025/04/09/c…
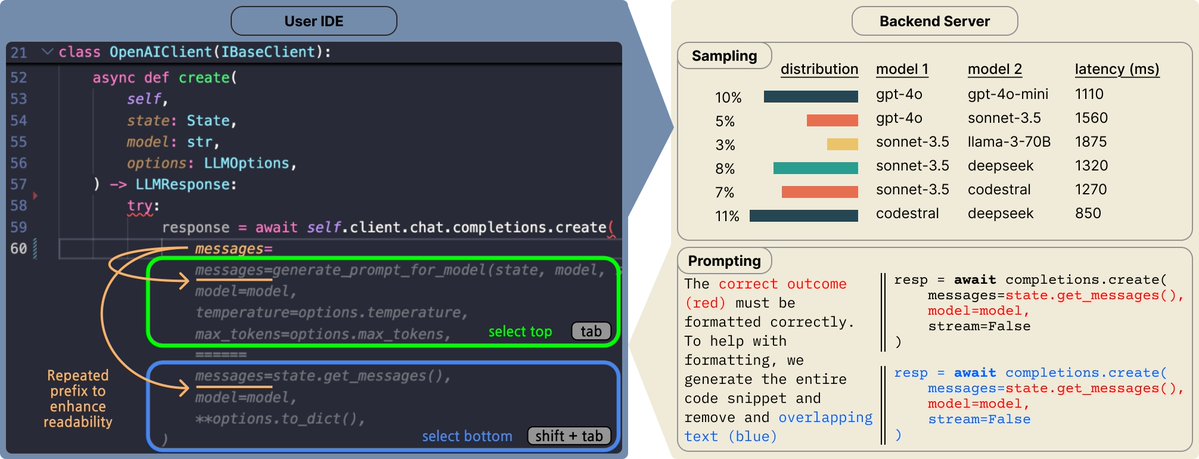
How do real-world developer preferences compare to existing evaluations? A CMU and UC Berkeley team led by @iamwaynechi and @valeriechen_ created @CopilotArena to collect user preferences on in-the-wild workflows. This blogpost overviews the design and deployment of Copilot Arena + new insights into developer code preferences.
Ryan Shar ✈️ COLM retweeted
What do developers 𝘳𝘦𝘢𝘭𝘭𝘺 think of AI coding assistants?
In October, we launched @CopilotArena to collect user preferences on real dev workflows. After months of live service, we’re here to share our findings in our recent preprint.
Here's what we have learned /🧵


Introducing Copilot Arena - Interactive coding evaluation in the wild.
Our extension lets you test top models for free, right in VSCode. Let's vote and build the Copilot leaderboard!
Download here:
marketplace.visualstudio.com…
Led by @iamwaynechi and @valeriechen_ at CMU. 1/🧵
Ryan Shar ✈️ COLM retweeted

When benchmarks talk, do LLMs listen?
Our new paper shows that evaluating that code LLMs with interactive feedback significantly affects model performance compared to standard static benchmarks!
Work w/ @RyanShar01, @jacob_pfau, @atalwalkar, @hhexiy, and @valeriechen_!
[1/6]

Ryan Shar ✈️ COLM retweeted

🧵 on surprising revelations from our study of specialized foundation models (FMs beyond vision/text): after evaluating dozens of scientific & time series FMs we found that most weren’t even competitive with simple supervised models, some with as little as 513 parameters.
1/n

Ryan Shar ✈️ COLM retweeted

Which model is best for coding? @CopilotArena leaderboard is out!
Our code completions leaderboard contains data collected over the last month, with >100K completions served and >10K votes!
Let’s discuss our findings so far🧵
