

I like computers and cats. ちょっと日本語上手。にゃー Ko-fi: https://xitter.cf/t.co/X2dKfIm2kf
San Diego, California, USA
Joined January 2015
- Tweets14.1K
- Following504
- Followers1.7K
- Likes18K







Pinned Tweet
I write posts and try to do them daily or at least weekly. Check out my site (tristanxr.com/) for my latest posts. I often write about topics like ARM, RISC-V, NixOS, and things I am interested in or involved in.
Got an Artix 7 board from Alinx, PCIe is like 80% working in a test bitstream with openXC7. Hoping to get Glacier to be usable under Linux with this.
Claude added a dedicates port from an SDRAM controller to the scanout module. It then wonders why PnR is becoming difficult to solve. I tell it its because of that long bus between the SDRAM to the scanout. It pushes back but checks, it realizes I am right. I tell it to go from wishbone to AXI4 and use the different channels to help with access. It does that and timing increases beyond the pre-second SDRAM read port.
LLM's need to be trained more on hardware design, they don't understand timing. I do think it's somewhat because they don't imagine things. I definitely visualize the congestion and can rationally think about it. But at least Claude wants to be evidence driven and doesn't believe things unless it checks. But it wants to check absolutely everything.
It's funny when Claude uses flip flops for buffering instead of BRAM and wonders why routing struggles.
Claude: This change is adds an extra 270 cycles of latency.
*Runs PnR, Fmax up by 40%*
Claude: I was wrong, this is faster.
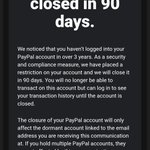
Why is PayPal closing my account that I use actively and have logged into over the past 3 years? I literally last used it just a few hours ago. I've had this account for years.


Glacier is coming online. I can only issue 1 command to the GPU until it dies. However, progress is being made. Once things are fixed, going to try rendering a test pattern.


Chock now has a comparison with Claude Code and Codex.
chock.ws/comparison/


Tristan Ross 😺❄️ retweeted

Did you know we have a newsletter? Be sure to subscribe to it using the link bellow. We've been working hard and want to keep you informed on the amazing work we've been up to.
news.lilithsemi.com/subscrip…


Managing to run GLM-5.3 Flash Heretic at 4 t/s on an Ampere Altra box without using the GPU. Hoping to push it to 8 - 12 t/s soon. This is using @LilithSemi's Vulcan codegen library. Once the inference engine is optimized enough on CPU alone, will be working on getting fast GPU inference on an RTX 5070 (12GB).
AI is at the point you can have it design its own harness and inference engine and work with it to optimize. You can feed it papers that show different quantizations, caching methodologies, and have it self optimize.
ai& is the best open weight model provider out there that you can trust. I've been using GLM-5.3 from them and it's been excellent.
Chock has first class support for ai& and was tested with models ai& hosts. I'm looking forward to seeing them grow and expand their capabilities.

8 people joining ai& this week!
@aiand_
- ai& inference is growing like crazy. We continue to punch above our size in terms of performance and Day 0 releases
- JapanFold is helping people in Japan and around the world discover new medicines
- Closed our biggest deal to date

