

MiniPlay is a gamified cognition miniapp on @MiniPay. Enhance speed, logic, memory, focus, & social, through fun mini-games. built by @zenoVision_ | $SKILLX
MiniPay
Joined January 2025
- Tweets139
- Following60
- Followers387
- Likes251




Most game tokens pay for activity.
We built the opposite. 🧠
40M+ games. ~350K players. 🎮
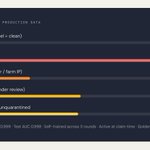
FairPlay’s ML models separate humans from farms at claim time.
$SKILLX is how that integrity becomes an economy, not a faucet. 🫡


This isn’t just for games.
Grants. Airdrops. Waitlists. Any system paying humans.
FairPlay started as MiniPlay defense. It’s becoming human-verification infrastructure.
Skill > Volume. Always.
miniplay.studio/fairplay 🕹️

The model rediscovered the golden rule on its own:
'has paid' beat every other clean signal by 2×.
We didn’t tell it money mattered. The data did.
Gen 4 closes the loop: detectors flag → mods review → labels retrain the model.
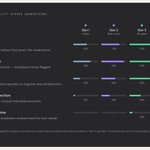
“Compounds over time”: 0% → 0% → 12% → 91%
The longer it runs, the harder it gets to farm.
Gen 4 numbers:
• KS separation: 0.982
• Claim-gate precision: 98.4%
• Recall: 92.8%
• AUC climbed 0.975 → 0.9944 across generations
Near-perfect human vs bot separation.

The training ground:
• ~40M games played
• 310K+ accounts scored continuously
• Stablecoin rewards → organised attacks, sharp labels
Stakes make the data honest.
MiniPlay retweeted

Games that make @MiniPay real fun:
🎨 @Modeto by @GigaHierz
🕹️ ArcadeX by @AadarshArmil
📝 Nerdos by @camilosaka
⚡ @MiniPlayStudio by @Mbarrbosa
✅ @MiniQuizxyz
🧱 @PlayBlokaz by @TweetleHQ

Take a look at what we launched recently at miniplay.studio/fairplay 👀 after the v2 with better gameplay and engagement

MiniPlay retweeted

Zeno.Vision isn’t an agency.
It isn’t a consultancy. It isn’t an investment fund. It’s a venture creation studio.
We build products from first principles around one long-term thesis:
Help AI understand and interact with the physical world.

The model self-trains.
AUC went 0.975 → 0.9944 across generations without rewriting the feature set.
Near-perfect separation.
Engagement beats identity.
Gen 1–3: 4 separate detectors, each calling quarantine directly. No coordination. Race conditions. False-positive risk at every path.
Gen 4: detectors stamp a dirty flag only. One unified verdict engine reads the recomputed score and applies all policy gates exactly once.
One write path. Auditable. Reversible.
The score distribution is almost bimodal.
Confirmed clean users cluster hard below 0.3. Confirmed bots cluster hard above 0.85. The gap between 0.35–0.80 is nearly empty.
That KS gap of 0.982 means the model is essentially never confused about which population it's looking at.
Gen 4 of MiniPlay's anti-sybil/bot model has been training on ~40M games played.
KS separation: 0.982.
Claim-gate precision: 98.4%.
Recall: 92.8%.
310K+ accounts scored continuously.
Here's a bit more of its progress 🧵


MiniPlay retweeted

Training my brain on @MiniPlayStudio and hit level 2! Join with code CTWJFJUM for bonus XP. miniplay.studio #playonminipay #miniplay

The detection stack — four layers, self-improving, built on real production data from one of the hardest bot environments out there — is becoming its own thing.
If you're building something that needs to know it's talking to a human, we're working on making this available. More soon.
This isn't a gaming problem.
Grants. Airdrops. Waitlists. Content monetisation. Any system distributing value to humans faces the same non-human inception — bots, sybil farms, AI-generated personas competing against real people.
We just happened to have one of the sharpest training grounds on the planet.
Gen 4 is the loop closing on itself.
10K+ accounts flagged by ML but not by any rule → moderator queue → every review writes a new labelled example into the next retrain.
"Compounds over time" score across generations: 0% → 0% → 12% → 91%.
The longer it runs, the harder it gets to beat.
Four generations in 6+ months:
Gen 1 → behavioural rules (velocity, IP clusters, rank-jump)
Gen 2 → live risk scoring + structural fingerprints
Gen 3 → ML claim gate, 281K users scored, AUC 0.971
Gen 4 → self-improving moderator label loop
Each one built directly from live attacks. No simulated threat models.