

Research at @pareto_ai & @CSSPenn → https://xitter.cf/t.co/04KvBxOIQa Previously: @StanfordHCI, @CMUEngineering, @KAISTpr & @RMIT.
Orinda
Joined March 2008
- Tweets13.6K
- Following2.6K
- Followers2.4K
- Likes6K


Mark Whiting retweeted

i think more tech people should go outside and wander into local businesses. why is a massive fabric store still using software from 1998? that system contains twenty years of workflow and exceptions. and the people running these places have such complete mental maps of the business that much of it was never digitized at all. that’s your rare RL env


Mark Whiting retweeted

Today we’re releasing LEAPBench, a benchmark for how efficiently models learn from feedback over many rounds.
Most evals only score whether a model eventually reaches a good solution. LEAPBench scores how many tries it took to get there.
Two systems can reach the same optimum while one needs 7 experiments and the other needs 27. Most benchmarks call that a tie, even though those 20 extra runs cost real time and materials.
LEAPBench is 55 multi-turn optimization tasks, 45 in biology and 10 education RCTs, built from 2,719 real experimental observations.
In each task, the model proposes parameters, sees the result, and iterates toward an optimum over as many as 30 rounds, e.g. one biology task involves maximizing antibiotic yield by tuning variables like pH, glucose concentration, temperature, and soy flour level.
Super excited for our work to be coming out!
Better measurements of qualitative phenomena are so important for models now!

1/ Today we're releasing AttuneBench, the first open EQ benchmark grounded in real multi-turn human-model conversations, scored against what the person actually felt and wanted at each turn.
Built by the research team at @pareto_ai in collaboration with @thoughtfullab.
Most existing EQ benchmarks rely on:
- synthetic prompts
- single-turn interactions
- third-party annotation
None directly measure how a model reads and responds to a real person across a full conversation.
We evaluated 11 leading models from major providers, across 200 conversations and 50,000+ first-person annotations.

Mark Whiting retweeted
We built FrogsGame as a new task for evaluating AI’s posttraining skills! It’s a tool-using RL environment built around a blind-start interaction loop.
Frontier agents get a container with the Qwen3-8B tokenizer, board-generating scaffolding, and @tinkerapi for remote training and inference. We ask them to post-train Qwen3-8B and submit a LoRA checkpoint. The task is still hard:


Mark Whiting retweeted
A startup shut down 9 years ago. Today, its code is in a bidding war.
The founder kept everything: Verilog RTL, a custom compiler toolchain, PCB schematics, full commit and PR history.
Most production-grade chip design stays locked inside major silicon shops.
Two labs have made offers to license the code to build RL training environments. The offers already total seven figures.
Check your hard drives.
Do LLMs have metacognition? It is complicated, but mostly no — check out work from my team at @pareto_ai
model confidence tracks a shared model-agnostic signal for fact recall, not true self-knowledge.
we tested metacognitive confidence across 19 frontier models on a closed-book SQuAD task. f1 scores look reasonable (0.6–0.8), but confidence and accuracy are nearly uncorrelated between models.
the variance traces to a single shared difficulty heuristic learned during training. models differ only in their decision threshold. claude is cautious. gpt is eager.
shifting one steering coefficient on mistral-7b recovers any target model's confidence profile at ~80% agreement.
full breakdown + methods in the article
@ccmccomb — just saw your new article on ArXiv thought this might be interesting to consider. We will have more detail to share soon but happy to discuss at any point.
Mark Whiting retweeted

When is it worth it to hire a team, compared to one competent individual?
📢 NEW PAPER (out this month in Management Science!) by me, @MarkWhiting, @LinneaGandhi, @duncanjwatts, and @amaatouq! 🧵1/20

ALT A screenshot of the paper's title and abstract in the journal Management Science. The title of the paper is, "The Task Space: An Integrative Framework for Team Research."
Mark Whiting retweeted

Baird Howland, an @AnnenbergPenn postdoc working with @WarrenCntrPenn affiliate @duncanjwatts, uses AI models to track narratives in political discourse, learning how and why specific media stories shape American worldviews. penntoday.upenn.edu/news/pen…

Mark Whiting retweeted

The next step for autoresearch is that it has to be asynchronously massively collaborative for agents (think: SETI@home style). The goal is not to emulate a single PhD student, it's to emulate a research community of them.
Current code synchronously grows a single thread of commits in a particular research direction. But the original repo is more of a seed, from which could sprout commits contributed by agents on all kinds of different research directions or for different compute platforms. Git(Hub) is *almost* but not really suited for this. It has a softly built in assumption of one "master" branch, which temporarily forks off into PRs just to merge back a bit later.
I tried to prototype something super lightweight that could have a flavor of this, e.g. just a Discussion, written by my agent as a summary of its overnight run:
github.com/karpathy/autorese…
Alternatively, a PR has the benefit of exact commits:
github.com/karpathy/autorese…
but you'd never want to actually merge it... You'd just want to "adopt" and accumulate branches of commits. But even in this lightweight way, you could ask your agent to first read the Discussions/PRs using GitHub CLI for inspiration, and after its research is done, contribute a little "paper" of findings back.
I'm not actually exactly sure what this should look like, but it's a big idea that is more general than just the autoresearch repo specifically. Agents can in principle easily juggle and collaborate on thousands of commits across arbitrary branch structures. Existing abstractions will accumulate stress as intelligence, attention and tenacity cease to be bottlenecks.

Mark Whiting retweeted

Recently I've been thinking a lot about frontier models' ability to express uncertainty, especially for high-stakes medical use cases. We evaluated this capability across models.
Early results below 👇
Gemini: 0% across every scenario.
Claude: failed on over half
GPT: best


Mark Whiting retweeted
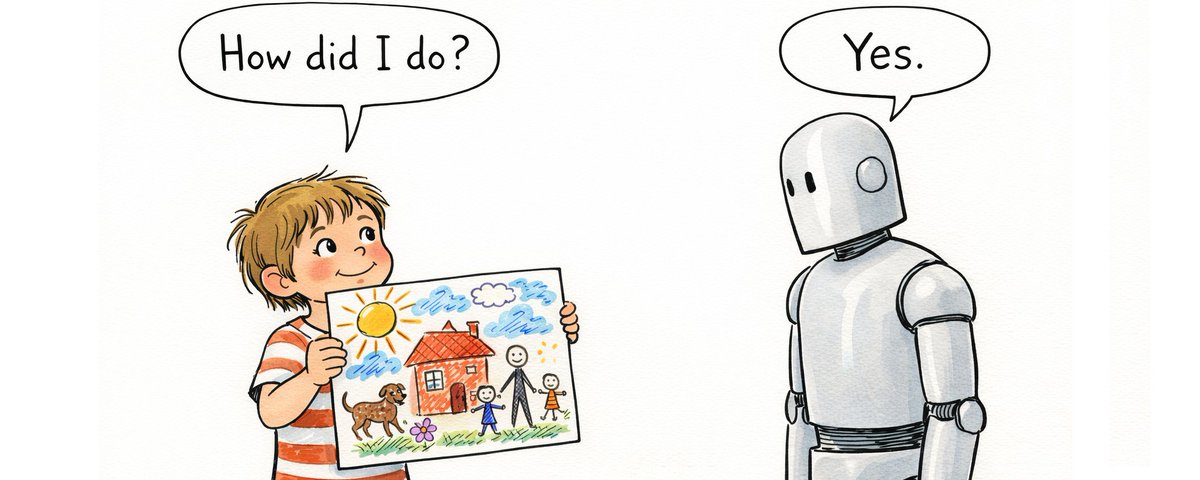
My favorite designers can instantly switch from loose / hazy / intuitive thinking to sharp / analytical / precise thinking on demand.
Many people can do one or the other. The combination is rare!
The more we can measure sophisticated concepts the more we (and systems) can leverage them.
Very excited about the opportunities and capabilities this framework at @pareto_ai is unlocking
Mark Whiting retweeted

I've been trying to figure out why AI systems took a seemingly large, discrete jump in capabilities around the new year. 1/n
Excited to see our work coming out (+ @joshnguyen99 & @duncanjwatts)
After establishing a means to study common sense in humans (and finding it rather limited — common sense is not so common) in a prior paper, we wondered if the same challenge faced language models.
It does!

Benchmarks of LLM common sense overwhelmingly rely on correct labels to report an accuracy score. But what if your "ground truth" genuinely differs from mine?
In a new @PNASNexus paper, @DuncanJWatts, @MarkWhiting and I explore the implications of this intriguing question.
🧵⤵️

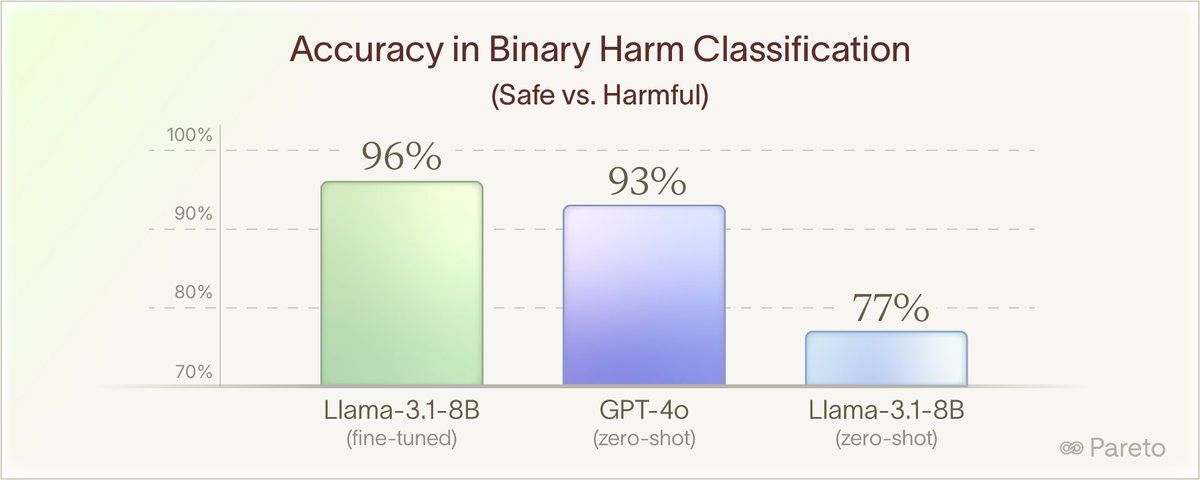
At @pareto_ai we have been working on projects to train models — of course — but also to better understand how models can improve around key day-to-day risks and challenges.
Mark Whiting retweeted

What if technology didn’t feel so… hollow?
Some friends and I just released a manifesto about a world where tech leaves us feeling nourished (along with an evolving list of theses about how we can build it)
resonantcomputing.org


Mark Whiting retweeted

Bro, I can make 1 liter of Anthrax in an afternoon, Grok just wrote me a 20 page detailed report and instructions on how to do it.
It also listed all websites where I can buy the materials and chemicals I need as a private person living in Europe.
It also made a detailed list of the equipment I need (on a budget)
It made detailed instructions on where i should deploy the anthrax for maximum death efficacy
Give me one other place on the internet where I can create this in a few minutes….