





macOS 27's built-in fm model: how long is its context, really?
• Apple's Foundation Models docs: 4,096 tokens per session
• Apple's WWDC26 macOS 27 sample prints a contextSize of 8,192
• One tester on an M5 Max: 8,026 tokens went through, 8,095 were rejected
• Another, on 27.0.1: 4,096
If you're on macOS 27, which build are you on, and where does yours stop?
DeepSeek V4.1 Flash (552B MoE) on one Mac Studio, from the mlx-serve developer's model card (M5 Ultra, 256 GB):
• ~206 GB resident at 3.06 bits per weight
• Its Engram tables (203 GB) are read from the SSD each token, never held in memory
• 69.4 tok/s plain decoding; 100.4 on agent prompts with DSpark drafting on, 51.9 on prose
256 GB is the floor for this one. Anyone tried it on an M3 Ultra?
Flint now runs two very different ways on a Mac.
All in memory, 4-bit (~24 GB with context, our est.):
• Mac mini M5 Pro 64 GB: 115 tok/s (@pratikg)
• Mac Studio M3 Ultra: 104.5–107 (@aleckloss)
Experts streamed from the SSD (MLX Chat 1.2.6, per @abayomipo):
• ~3 GB of RAM, ~30 tok/s on an M5 Max
A quarter of the speed, a fraction of the memory. The open question is how it holds up on a 16 GB Mac.
Public Flint runs on Macs (who ran them, runtime, tok/s) and which Macs fit it: mlx.app/run/flint?utm_source…
A trend worth watching for compute networks: streaming a model's experts from the SSD instead of holding them in memory.
Two public examples today:
• slotstream: a 125B MoE on a 48 GB M5 Pro, ~12 tok/s (its README)
• MLX Chat 1.2.6: Flint 40B in ~3 GB of RAM, ~30 tok/s on an M5 Max (the developer's post)
If this holds on smaller Macs, the pool of machines that can serve big models gets a lot wider. What would you test first?
An interesting attempt from @nickvernij: agents read 100+ papers and ran 67 experiments to make a 26B MoE run better on a 24 GB MacBook, with no extra quantization, pruning or distillation.
The constraint is real: at 4-bit it's ~15.7 GB with context against the ~18 GB macOS gives the GPU, so other apps push it into swap.
For MoE on tight memory, what's helped you most: expert caching, offloading cold experts, or a smaller context?
Part 2 of memory vs bandwidth, at the top end:
• Mac Studio M5 Ultra, 96 GB: 1,200 GB/s
• MacBook Pro M5 Max, 128 GB: 614 GB/s
The Max fits more: Ornith 1.5 122B, Nemotron 3.5 Super VL and Devstral 2 123B at 4-bit (~73–75 GB with context) fit only the 128 GB. 57 open models vs 50 at 4-bit or better (our est.).
The Ultra has ~2× the bandwidth, so whatever fits both, it writes roughly twice as fast on dense models.
Bigger models, or faster ones.
Ant Ling says an updated Ling-3.1-flash-1019 is coming, open weights included, but they aren't out yet.
What the current Ling 3.1 Flash takes on a Mac (our est.):
• 560B MoE, 25B active per token, MIT license
• 4-bit: ~315 GB of weights, ~340 GB with context, so a 512 GB Mac Studio
• 2-bit: ~189 GB, fits 256 GB
The catch today: no MLX build, and stock mlx-lm can't convert its FP8 weights. We'll update the page when 1019 lands.
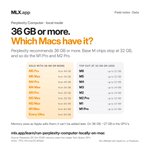
Picking Mac memory for local AI? Here's what each step buys you on one popular model, Qwen3.6 35B A3B (our est., context included):
• 16 GB: only a 2-bit version fits
• 24 GB: 3-bit
• 32 GB: 4-bit, the usual sweet spot
• 48 GB: 6-bit
• 64 GB: 8-bit
Same model, sharper answers at each step. What did you end up buying, and would you go bigger next time?
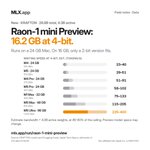
One model, every Mac. Qwen3.6 35B A3B at the best precision each memory size fits, context included (our est.):
• 16 GB: 2-bit, 12.4 GB (fits, quality drops)
• 24 GB: 3-bit, 16.8 GB
• 32 GB: 4-bit, 21.3 GB
• 48 GB: 6-bit, 30.7 GB
• 64 GB and up: 8-bit, 40.2 GB
More memory doesn't make the model bigger. It makes it sharper.
Beta testers who run AI on your own Mac: what's the smallest model you actually use every day?
For scale, at 4-bit with context:
• ~4B models (Qwen3.5 4B, Spark-X2.6 4B): ~4–6 GB, any Mac
• ~20B (gpt-oss-20b): ~15 GB, an 18 GB Mac or more
• ~30B with ~3B active (Qwen3.6 35B A3B): ~21 GB, a 32 GB Mac
Curious where people actually land.
Not every local model needs a big Mac. Three real jobs on small ones:
• Voice keyboard: @thejingtao's Voxt Mobile turns iPhone speech into text with Qwen3-ASR 0.6B + Qwen3.5-4B running on the Mac. The 4B at 8-bit is ~5.8 GB with context, so even 8 GB works.
• Agent memory: Tencent's Hy-Memory 30B A3B writes memories for other agents. ~17 GB at 4-bit, a 32 GB Mac.
• Quick chat: Spark-X2.6 4B, ~3.8 GB at 4-bit with context, an 8 GB Mac.
What small model does a real job for you?
Same Mac, same model, 2× the speed depending on the app.
@alex_grankin's runs of Qwen3.8 Flash-Next on an M5 Max:
• llama.cpp: ~40 tok/s
• LM Studio: ~48
• oMLX, 4-bit: ~70
• a 2-bit build: almost 90
When someone posts a tok/s number, the runtime and the quant matter as much as the chip. Which runtime gets you the most on your Mac?
The Mac mini M5 Pro 64 GB that ran Flint at 115 tok/s (4-bit, measured by @pratikg) has room for a lot more.
Fits with context, our est.:
• Flint, 8-bit: ~46 GB
• Nemotron 3.5 Bolt 74B, 4-bit: ~45 GB
• Qwen3.6 35B A3B, 8-bit: ~40 GB
• Sage-A1.5, 8-bit: ~40 GB
• Llama 3.3 70B, 4-bit: ~43 GB (fits, slow)
46 of the 80 open models we track fit it at 4-bit or better.
A bigger model that writes faster.
On a MacBook Pro M5 Max, @alex_grankin measured:
• Qwen3.8 27B (dense): ~30 tok/s
• Qwen3.8 Flash-Next (125B MoE): ~69
For every token, the 27B reads all 27B of its weights. Flash-Next reads about 6B (Qwen's card: 125B with 6B activated).
Memory decides what fits. Active parameters decide how fast it writes.