

OpenAI Open Source alternative. LocalAI is a community, drop-in replacement API compatible with OpenAI for local CPU/GPU inferencing
Joined April 2023
- Tweets1.5K
- Following40
- Followers4.1K
- Likes1.3K




LocalAI retweeted

If you want a Local AI super star to follow here he is @mudler_it 🚀 He is the creator of LocalAI project that has ONLY 50K stars on github.
Keep pushing Ettore!
Link: localai.io

LocalAI retweeted

LocalAI fait tourner texte, voix, image et vidéo en local, sans carte graphique obligatoire.
Une seule API compatible OpenAI, Anthropic et ElevenLabs.
Le lancement tient en une commande Docker.
cc @LocalAI_API
geekus.fr/x/localai

ALT Fiche Geekus de LocalAI : Fait tourner LLM, vision, voix, image et vidéo sur ton matériel, derrière une seule API.
LocalAI retweeted

Runs out of the box on parakeet.cpp! Trying it out right now and adding it to @LocalAI_API !

We took NVIDIA's Parakeet and made it better.
Introducing Fluid Speech Mini: the best Open Source Model purpose-built for Dictation 🚀
With SOTA performance under 300 MB
Run it on your iPhone, Mac, or PC. No cloud, no internet.
Dictation shouldn't need a server.
Your voice should be yours and we will make sure of that.
Open weights and more info below!
LocalAI retweeted
Wow the locate-anything models just reached almost 11M download, and are in the most downloaded models of @huggingface , in the first page !
Thanks @fabiolalli for telling me, I didn't notice 😅
Now, I don't know about the download stats and how that's calculated, but, in any case, happy to see community is using my locate anything port to @ggml_org ! you can also use it in @LocalAI_API in a couple of clicks away, published for all platforms we support.
In any case, I'm happy to contribute to the Open source community! Let's push Open source Local AI!

LocalAI retweeted
A huge thanks to @niels_gron for supporting @LocalAI_API with a brand new M5 Max MacBook Pro!
Generous support like this helps drive open-source forward.
Excited to start optimizing and making all our projects work natively for Apple Silicon!


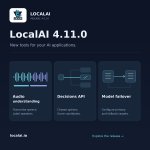
Release blog post: localai.io/blog/what-landed-…
Audio understanding: localai.io/blog/diarization-…
Decisions API: localai.io/blog/decision-mod…

LocalAI retweeted
parakeet-redux is a really interesting beast. You can extract the VAD head and then, you discover that has better recall than Silero. Despite the footprint compared to it, offline might have other uses.
@vikhyatk cooked hard here, congrats for the release, and thanks for working in the open!
By the way, all Parakeet-redux models are now in parakeet.cpp (links below). And you can use parakeet now as standalone VAD with both.

LocalAI retweeted
Your local agent can now hear what was said, who said it, and what happened around them.
parakeet.cpp transcribes audio, separates speakers, detects 527 sound classes, and now enrolls and remembers named voices across recordings. One pass, local C++.
LocalAI retweeted
Nemotron-3-Diarization was just released by @NVIDIAAI , and it runs in parakeet.cpp now, next to Parakeet speech recognition. It runs already on Apple with Metal, CUDA, @AMD and with anything that Vulkan supports.
We (@LocalAI_API) also added sound detection in: @Xiaomi's CED models (527 sound classes), ported to C++ sitting alongside it. You can run it with a couple of click via API, all Local and open source.
Parakeet.cpp now runs all three in one pass and you get the transcript, who is speaking, and what else you can hear. This scene from Sprite Fright took 2 seconds on a CPU.
LocalAI retweeted

I added full-body-control to my simulation using gem-x.cpp and GEAR SONIC (motion-bricks.cpp). The physically simulated character is controlled by my body movements and SONIC which tries to balance it.
Inference is done on @LocalAI_API which takes in video frames and produces reference movements.
Note that I don't think I'm getting the best performance here. There are probably some issues to iron between gem-x.cpp and motion-bricks.cpp.
LocalAI retweeted
A small update on what's going on in vllm.cpp:
- Minimax and LTX 2.5 got Lora support. Now you can Load fused-model, or either make lora load in runtime with prompts in vllm.cpp
- Support for Kev (@jaredpalmer), Laya and GLiNER2.5 (@fastinoAI ). Same SystemOne api, so you can switch quickly and have a fast Jev replacement, running locally
- Mia-AiLab/Qwen3.8-27B-EXL3-3.5bpw runs at ~53 tok/s at high concurrency (up to c32) with DGX Spark
I'm working now on the docs and making this a bit more easy to go, you'll also see all these models popping up in @LocalAI_API for a one-click install.
A big shout out our friends at @regolo_ai , for sponsoring us as part of their Builder Program and giving access to their API, thank you 🫶! I've also added them to my agent harness, nib, so you can /login and use their API directly, links👇
LocalAI retweeted
I added kimodo.cpp animation gen & playback in latent3d.space. So you can describe a motion, then it'll generate it using a @LocalAI_API instance and play it back on the physically simulated character.
Of course there are issues with finding animations that are physically possible, but that is part of the fun... maybe.
LocalAI retweeted

lnkd.in/p/g-T6EZXM
Lucy's coming together, 100+ setting configurations, multiple subsystems, 4 different operator modes, and cloud integration is still safe. Norton and Microsoft security systems were not bypassed.
@LocalAI_API @GeoStl @WashUengineers

LocalAI retweeted

🚨🚨🚨BRAKING NEWS!!!🚨🚨🚨
I recorded how alien artificial super intelligent agents could communicate just using speakers and microphones!
LocalAI retweeted
You can make any LLM into a Jev style classifier using @LocalAI_API .
In our implementation you can use hybrid inference as well to do small chunks using autoregressive generation. This allows quickly choosing a function and filling in a parameter.
One disclaimer though, calculating confidence scores is not well defined on a regular LLM, or at least I didn't find a way to do it. Practically speaking it chooses "I don't know" fairly reliably though. I'm not sure what Jev does on that front.

Can you have a voice assistant run on CPU? Yes, even on Rpi5, but with a catch.
parakeet.cpp for transcription and Piper for TTS are so fast that part is easy. The LLM is harder because autoregressive generation is slow, but prefill is pretty fast and we only (sort of) need prefill to do classification.
So let's say our assistant just calls a few functions. We can classify what function we need to call and just do token generation for the free-form parameters.
End result on a desktop CPU is voice commands process in less than a second when using lfm2.5-1.2b at 4bit. On Rpi5 it takes 1-2 secs; still usable.
The below demo is using the LocalAI realtime API backed by llama.cpp with some patches. I'm still ironing out some bugs, but will release the code soon. The rocket was created with trellis2cpp and the voxel scene is from my depth-anything.cpp demo.
LocalAI retweeted
kimodo.cpp got between a 1.5 and 10x speedup depending on quantization level. Also it's soon coming to @LocalAI_API