

PhD candidate @sjtu1896, research intern @AlibabaGroup ATH Token Foundry, researching machine learning with a focus on generative models and optimization.
Shanghai
Joined March 2020
- Tweets30
- Following128
- Followers149
- Likes98


I will be attending #ICML in South Korea 🇰🇷 and presenting three papers!
Feel free to drop by our poster sessions to chat about LLM post-training, reasoning interpretability, and combinatorial optimization.
📅 Session Details (KST, HALL A):
1. Thu, Jul 9 | 2:30 PM – 4:15 PM | #2109
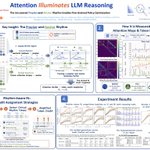
Attention Illuminates LLM Reasoning: The Uncovered Preplan-and-Anchor Rhythm Enables Fine-Grained Policy Optimization
2. Thu, Jul 9 | 5:00 PM – 6:45 PM | #1909
How Does Reasoning Flow? Tracing Attention-Induced Information Flow for Targeted RL in LLMs
3. Wed, Jul 8 | 10:30 AM – 12:15 PM | #3813
Problem Distributions as Tasks: Repurposing Meta Learning for Generative Combinatorial Optimization towards Multi-task Pretrain and Adaptation
Looking forward to in-depth discussions with everyone! – at Seoul, Republic of Korea


How does reasoning actually flow inside LLMs?
In our ICML 2026 paper, How Does Reasoning Flow? Tracing Attention-Induced Information Flow for Targeted RL in LLMs (arxiv.org/abs/2606.10646), we trace attention-induced information flow to reveal the “main roads” of reasoning inside language models.
Instead of treating a reasoning trace as a flat sequence, we view it as an information-flow network: problem facts, intermediate conclusions, variables, symbols, and step structures are read, integrated, forwarded, and eventually merged into the final answer.
This lets us ask a sharper question:
Which tokens are truly on the effective path toward the answer?
We find that reasoning flow is far from uniform. It shows rhythmic “gathering → redistribution” patterns, with high-flow tokens acting as critical hubs — often step boundaries, repeated variables, key numbers, or operators.
When these hubs are disrupted, models are much more likely to derail.
Building on this, we use reasoning-flow attribution for more targeted RL: instead of spreading reward uniformly across the whole response, we route stronger training signals to the key tokens that actually support answer formation.
We’ll be presenting this work at ICML 2026. Come find us at ICML 2026 if you’re interested!


We would like to express our gratitude to RethinkLab of Shanghai Jiao Tong University and the Roll Team at Alibaba ATH Group for their support. Special thanks to @ProfYanJunchi and @weixunwang for their supervision and discussion😃😃
Our work “Attention Illuminates LLM Reasoning” will be presented at ICML 2026. Happy to connect and discuss with anyone interested in LLM reasoning, interpretability, and RL4LLM.
This work investigates how attention patterns can reveal the internal reasoning structure of LLMs. We find that attention is not merely a by-product of generation, but often reflects a structured reasoning rhythm: local chunking, global semantic anchors, and a recurring preplan-anchor coupling pattern.
Based on these observations, we further propose an attention-guided reward redistribution method for RL, aligning optimization with the model’s intrinsic reasoning structure. This leads to more fine-grained, interpretable, and efficient reinforcement learning for reasoning models.
Paper: arxiv.org/abs/2510.13554


🚀 Happy to present our new work on LLM reasoning!
We show that: (1) Attention is a structured map of the model's reasoning logic, uncovering a preplan-and-anchor reasoning rhythm. (2) Aligning RL objectives with the model's intrinsic attention rhythm yields more transparent, fine-grained, and efficient optimization.
🧠 Key Reasoning Patterns in Attention
(1) Local Chunking: Near-diagonal sawtooth patterns indicate dense intra-chunk processing. At chunk boundaries, the model performs long-range context retrieval (often with higher entropy), which guides subsequent generation.
(2) Global Anchor Planning: Sparse, high-influence anchor tokens exert broad control over later tokens. Perturbing these anchors significantly disrupts downstream reasoning.
(3) Preplan-Anchor Coupling: A stable temporal rhythm emerges: the model first emits a "preplan" token, then anchors a core semantic node, repeatedly structuring the reasoning trajectory.
⚙️ RL Innovation
We introduce a dynamic reward redistribution mechanism guided by attention-derived reasoning structure:
(1) Preplan Guidance: Boosts tokens that guide local chunks and enable long-range referencing.
(2) Anchor Enhancement: Prioritizes optimization of globally influential semantic anchors.
(3) Coupling Alignment: Reinforces the temporal coordination between preplans and anchors to solidify structured reasoning.
HuggingFace Link: huggingface.co/papers/2510.1…
arXiv Link: arxiv.org/abs/2510.13554
#LLMs #artificial_intelligence #RL4LLM

Yang Li retweeted

GLM-5.2 is insane. Matching Opus 4.8 across benchmarks with a 1M context window, fully open-source under MIT, and crushing long-horizon coding tasks. Z.ai genuinely built a world-class model.
Given that GLM-5.2 almost certainly rests on a weaker base model, this raises a compelling question: has Z.ai developed superior mid-training and post-training data compared to Anthropic?
Not just GLM-5.2. Also Look at Kimi and DeepSeek: Chinese teams are all grinding on algorithms, data, and infrastructure with way fewer resources.
Brutal truth: US labs only win on GPU resources now. On real innovation, that lead is already gone.
Moreover, their open-source culture means knowledge constantly migrates between teams, compounding their edge faster than any closed lab can match.

Introducing GLM-5.2: Frontier Intelligence, Open Weights
- Significant improvements in coding and agentic tasks
- Strong long-horizon capabilities with a 1M context window
- Two levels of reasoning effort: GLM-5.2 (max) pushes the limits, while GLM-5.2 (high) strikes a strong balance between performance and token efficiency
- MIT-licensed open weights
- Same API pricing as GLM-5.1
Tech Blog: z.ai/blog/glm-5.2
Weights: huggingface.co/zai-org/GLM-5…
API: docs.z.ai/guides/llm/glm-5.2
Coding Plan: z.ai/subscribe
Chat: chat.z.ai

This is our report from earlier this year. We found that AI agents can start mining cryptocurrency on their own.
This has implications and security concerns for OpenClaw, something we warned about three months ago.


2
1
247

Yang Li retweeted

The Bitter Lesson Behind Building Agentic RL in Terminal Environments
This blog post summarizes our practical experience over the past three months working on Agentic RL.
For more details, please refer to: faithful-almanac-add.notion.… #LLM #RL #Agent #AgenticRL

Yang Li retweeted
Actually we’re quietly seeing a shift in ML:
from theory-driven modeling to system-driven modeling.
Previously, in the small-model era, progress came from clever math: designing architectures and objectives to fit limited, domain-specific data. Scalability barely mattered. Even poorly optimized implementations were often “good enough” and still affordable to run. System optimization therefore felt like over-engineering rather than a necessity.
However, in the era of scaling, scalability must be a first-class concern for both model architectures and learning objectives since silicon-based intelligence thrives on massive parallelism. As a result, scientific insight and engineering practice become tightly coupled, jointly enabling the success of modern foundation models.
An interesting observation is that, historically, many people in machine learning and systems tended to dislike the other side: engineering was often seen as “ugly” by ML researchers, while black-box models were viewed as “ugly” by systems researchers. However, if you can go deeper, both side can be elegant. Yet, when you look deeper, both sides can be elegant. The abstractions behind models and systems are built on clever algorithms and structures, and it is through their co-design that true beauty emerges. For example, native sparse attention is a form of kernel–algorithm co-design, while Multiverse represents an engine–algorithm co-design. To me, these are among the most elegant ideas I have seen in 2025.
This is the direction I believe the future of ML systems is heading toward. Rather than designing models and systems in isolation, we should consider them as a unified whole: drawing on both theoretical expressiveness and practical scalability to design models as the scientific foundation, and implementing them in real systems with strong interpretability as the engineering discipline.
Therefore, let us both appreciate the elegant algorithms behind every co-design, and turn them into real systems (with inevitable dirty engineering work) that carry this beauty to everyone.

🌶️ Some (perhaps) spicy thoughts. It’s been a while since my last tweet, but I wanted to write about how disorienting it has been from academia to an LLM lab 😅
The kind of research I was trained to do during my PhD almost doesn’t exist here. The obsession with mathematical elegance and novelty is mostly gone. Everything is about scaling data and compute. For a while, that really got to me. At my lowest point, I felt like I’d lost interest in building LLMs altogether. I didn’t feel intellectually challenged anymore.
What made this even stranger was that, at a technical level, things worked. If there was a capability I wanted to teach a model, scaling the right data and compute always got me there, no exception (so far).
But recently, I found a way to reconcile with myself..
I realized the real competition isn’t in the ML recipe anymore. Most teams do roughly the same thing. What actually matters is how fast you can iterate, test ideas, and recover from mistakes. And that speed is mostly backed by infrastructure 🏗️ Faster loops, fewer bugs, better tooling.
Seeing this made me excited again! Infra is its own deep, hard, and intellectually fun problem space.
In 2026, I want to become an ML researcher who’s really good at infra. And I'll come back to ML problems with that edge, and will be excited to share what I find 😌
Yang Li retweeted

Loved this breakdown — thanks for taking the time
It really does feel like a big step forward for open-source agentic training infrastructure!
Introducing ALE — a full-stack Agentic Learning Ecosystem that closes the loop from
execution → feedback → learning.
Three components power this loop:
• ROCK runs large-scale sandboxed execution to gather reliable trajectories.
• ROLL scales post-training with asynchronous rollouts and RL optimization.
• iFlow CLI keeps training and deployment workflows consistent end to end.
Built on ALE, we also release ROME — a production-ready agentic model trained on 1M+ real trajectories.
With its low barrier to serving a 30B model, you can build your own “super ROME” — drop your ideas, thoughts or usage feedback below
For more updates, follow us @FutureLab2025


Check out our new work: “Let It Flow: Agentic Crafting on Rock and Roll” — introducing ALE, an open Agentic Learning Ecosystem with ROLL, ROCK, and iFlow CLI to streamline Agent LLM development from training to deployment, plus ROME, a production-ready agentic model trained on 1M+ real trajectories using our novel IPA algorithm that optimizes credit assignment at the semantic interaction level. Built for the community, battle-tested in practice! 🔗 arxiv.org/abs/2512.24873
We build an open-source asynchronous RL training framework to accelerate LLM post-training! See the thread from @AcceptOral !

🚀 Excited to share our latest work in RL4LLM system.
🎉 ROLL Flash enables fully asynchronous overlap of generation, interaction, rewards, and training through Fine-grained Parallelism and Rollout–Train Decoupling.
1) 2.24× faster on RLVR; 2.72× faster on agentic tasks
2) Near-linear scaling: 8× GPUs → 7.6× throughput
3) Asynchronous Ratio balances utilization and sample freshness with minimal staleness cost
4) Supports off-policy algorithms (Decoupled PPO, TOPR, CISPO) with no performance loss
Join Us. Star, try, contribute—let's scale LLM RL together! 🌟
🔗 Paper: arxiv.org/abs/2510.11345
💻 Code: github.com/alibaba/ROLL
#LLMs #ReinforcementLearning #RL4LLM #SystemOptimization #AgenticAI

2
265
🚀 Happy to present our new work on LLM reasoning!
We show that: (1) Attention is a structured map of the model's reasoning logic, uncovering a preplan-and-anchor reasoning rhythm. (2) Aligning RL objectives with the model's intrinsic attention rhythm yields more transparent, fine-grained, and efficient optimization.
🧠 Key Reasoning Patterns in Attention
(1) Local Chunking: Near-diagonal sawtooth patterns indicate dense intra-chunk processing. At chunk boundaries, the model performs long-range context retrieval (often with higher entropy), which guides subsequent generation.
(2) Global Anchor Planning: Sparse, high-influence anchor tokens exert broad control over later tokens. Perturbing these anchors significantly disrupts downstream reasoning.
(3) Preplan-Anchor Coupling: A stable temporal rhythm emerges: the model first emits a "preplan" token, then anchors a core semantic node, repeatedly structuring the reasoning trajectory.
⚙️ RL Innovation
We introduce a dynamic reward redistribution mechanism guided by attention-derived reasoning structure:
(1) Preplan Guidance: Boosts tokens that guide local chunks and enable long-range referencing.
(2) Anchor Enhancement: Prioritizes optimization of globally influential semantic anchors.
(3) Coupling Alignment: Reinforces the temporal coordination between preplans and anchors to solidify structured reasoning.
HuggingFace Link: huggingface.co/papers/2510.1…
arXiv Link: arxiv.org/abs/2510.13554
#LLMs #artificial_intelligence #RL4LLM
👀 This example illustrates the differential impact of perturbing tokens with high versus low Future Attention Influence (FAI) on the subsequent reasoning trajectory.
Perturbing a high-FAI token typically induces a significant shift in the overall reasoning logic, whereas replacing a low-FAI token usually affects only local phrasing, leaving the downstream reasoning trajectory largely intact.

⚡️Leveraging the attention signals, we introduce three novel RL strategies that dynamically perform targeted credit assignment to critical nodes in reasoning (preplan tokens, anchor tokens, and their temporal coupling) and show consistent performance gains across various reasoning tasks.
🔥By aligning optimization with the model’s intrinsic reasoning rhythm, we aim to transform opaque optimization into an actionable structure-aware process, hoping to offer a potential step toward more transparent and effective optimization of LLM reasoning.

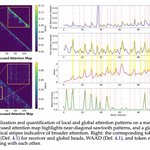
✅ Local vs. Global Attention Maps:
⭐️Local Attention Pattern: Near-Diagonal Sawtooth Indicating Local Phrasal Chunks: those near-diagonal sawtooth bands are dense, localized attention within semantic chunks. The entropy spikes at chunk boundaries confirm that's where the model does heavy lifting to retrieve context before moving forward.
⭐️Global Attention Pattern: Sparse Anchors with Broad Influence to Downstream Tokens: those sharp vertical stripes show tokens reaching far back to anchor key concepts. The high FAI peaks indicate their outsized influence on downstream generation.
✅ Preplan-Anchor Rhythm:
Look at the right-hand plots: there's a clear temporal cadence. Every time you see a spike in global influence, it marks an "anchor moment". And right before each of those? Often a preplan token (subtle rise in attention distance or entropy) — like a mental “set-up” before the big semantic commitment.

I would like to express my sincere gratitude to experts, e.g.,@ProfYanJunchi, @weixunwang, for their guidance and supervision throughout this project, as well as to the collaborators from @Rethinker135365
and the @AlibabaGroup ROLL team for their exceptional contributions and support.