
PhD candidate in Shanghai Jiao Tong University @sjtu1896.
Joined June 2024
- Tweets6
- Following17
- Followers60
- Likes6

🚀 Excited to share our latest work in RL4LLM system.
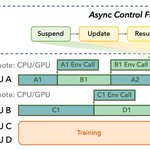
🎉 ROLL Flash enables fully asynchronous overlap of generation, interaction, rewards, and training through Fine-grained Parallelism and Rollout–Train Decoupling.
1) 2.24× faster on RLVR; 2.72× faster on agentic tasks
2) Near-linear scaling: 8× GPUs → 7.6× throughput
3) Asynchronous Ratio balances utilization and sample freshness with minimal staleness cost
4) Supports off-policy algorithms (Decoupled PPO, TOPR, CISPO) with no performance loss
Join Us. Star, try, contribute—let's scale LLM RL together! 🌟
🔗 Paper: arxiv.org/abs/2510.11345
💻 Code: github.com/alibaba/ROLL
#LLMs #ReinforcementLearning #RL4LLM #SystemOptimization #AgenticAI

I would like to express my sincere gratitude to experts, e.g.@ProfYanJunchi @weixunwang, for their guidance and supervision throughout this project, as well as to the collaborators from @Rethinker135365 and the
@AlibabaGroup ROLL team for their exceptional contributions and support.
1
5
463
📊 Theory and practice validation:
We theoretically prove the efficiency upper bound of async training and validate four key findings through extensive experiments:
1) Resource scalability: As GPU count increases, Async maintains near-linear scaling while Sync degrades due to long-tail issues
2) Resource utilization: Optimizing the train/inference resource ratio achieves up to 2× acceleration
3) Async ratio tuning: In most configurations, Async Ratio = 2 achieves optimal throughput without sacrificing sample freshness
4) Training stability: Various off-policy algorithms achieve performance comparable to Sync under Async settings
5
471
💡 Key technical innovations:
1) Queue Scheduling: Each task is independently scheduled and seamlessly assigned to idle GPUs, completely eliminating the "straggler" effect in batch processing
2) Prompt Replication: Splits multi-candidate generation into independent tasks distributed across different GPUs for parallel execution, significantly mitigating long-tail latency
3) Environment-Level Async Rollout: When agents interact with environments, GPUs immediately switch to process other trajectories, avoiding idle waiting
4) Redundant Environment Rollout: Uses redundant environment groups to combat fail-slow/fail-stop issues, enhancing training robustness

Han Lu retweeted

🚀 Happy to present our new work on LLM reasoning!
We show that: (1) Attention is a structured map of the model's reasoning logic, uncovering a preplan-and-anchor reasoning rhythm. (2) Aligning RL objectives with the model's intrinsic attention rhythm yields more transparent, fine-grained, and efficient optimization.
🧠 Key Reasoning Patterns in Attention
(1) Local Chunking: Near-diagonal sawtooth patterns indicate dense intra-chunk processing. At chunk boundaries, the model performs long-range context retrieval (often with higher entropy), which guides subsequent generation.
(2) Global Anchor Planning: Sparse, high-influence anchor tokens exert broad control over later tokens. Perturbing these anchors significantly disrupts downstream reasoning.
(3) Preplan-Anchor Coupling: A stable temporal rhythm emerges: the model first emits a "preplan" token, then anchors a core semantic node, repeatedly structuring the reasoning trajectory.
⚙️ RL Innovation
We introduce a dynamic reward redistribution mechanism guided by attention-derived reasoning structure:
(1) Preplan Guidance: Boosts tokens that guide local chunks and enable long-range referencing.
(2) Anchor Enhancement: Prioritizes optimization of globally influential semantic anchors.
(3) Coupling Alignment: Reinforces the temporal coordination between preplans and anchors to solidify structured reasoning.
HuggingFace Link: huggingface.co/papers/2510.1…
arXiv Link: arxiv.org/abs/2510.13554
#LLMs #artificial_intelligence #RL4LLM

Han Lu retweeted

#LLMs #artificial_intelligence #RL4LLM
🚀 Happy to present our work: Asymmetric Proximal Policy Optimization: Mini-Critics Boost LLM Reasoning. We re-examine PPO in LLM domain and find 3 key insights:
👀 (1) The critic might serve as a natural safeguard for stable policy training.
⚡️ (2) Training smarter reasoning agents does not require a giant critic—value estimation capability is not equivalent to model size.
😮 (3) Critic signals can further guide the reconstruction of the policy loss objective itself.
I'll go step-by-step through this thread👇.
