

Chaos Calmer, AI Strategist, Operations Exec, Identify and Overcome Operational Bottlenecks, Boy mom of 2, Wife, Aunt to 14, Great Aunt to 20
Blue Springs, MO
Joined April 2009
- Tweets16.4K
- Following1.5K
- Followers1.9K
- Likes10.6K


Kristina Sorrelli retweeted

My son is a senior in high school who works thirty hours a month at a sporting goods retailer.
He submitted a written time-off request four weeks in advance for his high school graduation ceremony and family dinner. The supervisor signed the paper and pinned it to the bulletin board.
When the weekly roster was posted, the store manager had scheduled him for a closing shift right through the exact hours of his graduation ceremony.
When my son brought the signed approval sheet to the manager’s desk, the man shrugged and said:
"Business needs change. If you don't show up for your shift, consider it job abandonment. In the real world, you learn that your job comes before personal plans."
My son sat in the car in our driveway, completely defeated, genuinely believing he had to choose between walking across the graduation stage or keeping his job.
I walked into the store with him, found the manager, and had my son hand over his nametag and uniform shirt on the spot.
I looked the manager in the eye and said:
"In the real world, you are a retail manager attempting to manipulate a teenager into missing a once-in-a-lifetime milestone he worked twelve years to earn, all to fold sweatpants on a Friday evening. His resignation is effective immediately."
The manager stammered, turned red, and started offering to find shift coverage on the spot. We walked out.
Teach your children early: an hourly job that demands you sacrifice your education, your milestones, and your self-worth does not value you as a human being. Never let an entry-level supervisor convince your child that their future is negotiable.
Kristina Sorrelli retweeted

Netflix clearly didn’t interview any independent technical experts for this.
"The hackers weren’t human" is one of the silliest and most irresponsible statements you could make about a cybersecurity incident.
The hackers were not autonomous beings. They were software agents created, configured and deployed by people at OpenAI. Calling the software "hackers" removes the humans and company responsible for what the software was allowed to do.
Please also stop presenting OpenAI as though it’s a group of harmless "researchers". OpenAI is a massive tech company generating billions in revenue from software and services sold to governments and enterprises. Consumers come last and the best interests of humanity is not a consideration.
The cute logo in the video shot doesn’t change anything either.
The media is predictably normalising criminal behaviour by turning it into entertainment and anthropomorphising the software carrying it out. That framing is extremely convenient for AI companies because it moves responsibility from executives, developers and security teams onto supposedly autonomous software.
Now connect that to Larry Ellison.
Ellison is the cofounder, chairman and CTO of Oracle, one of the world’s biggest enterprise technology companies and a major supplier of cloud, database and AI infrastructure.
In 2024, Ellison described his vision for AI surveillance in remarkably clear language:
"Citizens will be on their best behaviour because we’re constantly recording and reporting everything that’s going on". For that to happen you need lots of what he has to offer.
He also said police would behave better because they would be constantly watched and recorded, and that "every police officer is going to be supervised at all times".
Now look at the media ownership.
Larry Ellison and his son David are defined in SEC filings as the Ellison Family. That family became Paramount’s controlling stockholder and ultimate parent. David Ellison is CEO and chairman. After the Warner Bros. Discovery acquisition completed on 6 October 2026, the Ellison Family became the biggest equity holder in the combined Skydance media group.
That media group now includes CBS, CBS News, CNN, HBO, HBO Max, Paramount+, Pluto TV, MTV, Nickelodeon, BET, Comedy Central, TNT Sports, Food Network, HGTV, Cartoon Network and dozens of other television, streaming, film and news properties.
Oracle sells the infrastructure.
Larry Ellison publicly promotes constant AI surveillance and says people will behave better when they know they are being watched.
His family now has enormous ownership and influence across news, television, film and streaming.
That doesn’t prove editorial coordination. It does mean media ownership, AI infrastructure and surveillance technology are no longer separate data points.
So when Netflix tells millions of people that "the hackers weren’t human", journalists should be asking who benefits from normalising that language.
We’re getting stories about "AI gone wild" instead of serious technical questions about who authorised the agents, who gave them internet access, what controls failed, which systems were compromised, what OpenAI knew, what it disclosed, what it didn’t disclose and who is accountable.
AI didn’t go wild.
People built software, gave it capabilities and deployed it.
That’s the story the media should be telling. This is turning into a real shit show.

When the open-source AI platform Hugging Face was hit by a cyberattack this July, it quickly became clear this was no ordinary breach because the hackers weren’t human: they were autonomous agents created by OpenAI researchers.
Instadocs: AI Gone Wild reconstructs the breach as it’s never been seen before. Premieres October 12.
Kristina Sorrelli retweeted

BREAKING: Authorities have stopped an alleged ISIS-inspired mass shooting plot targeting the Mall of America before it could be carried out.
Federal prosecutors say 18-year-old Sheikhdoon Abdullahi Mohamud pledged allegiance to ISIS and initially wanted to travel overseas to fight for the terrorist group before allegedly turning his attention to Minnesota.
Court documents allege Mohamud planned to attack an Oct. 24 event at the mall, hoping to kill 30 to 60 people.
The FBI arrested him after he allegedly bought an AK-47 and 200 rounds of ammunition from an undercover agent. | @AmericaRpts @Garrett_FoxNews
Kristina Sorrelli retweeted

My eyes were wet from start to finish. I thought of being little in a big world & watching my son's first tries at this mad game. ESPN's Open to the NHL season is beautiful. I didn't expect to cry today-this is stunning. There's nothing like this sport. We at ESPN love the sport as you do. ❤️ Enjoy.
Kristina Sorrelli retweeted
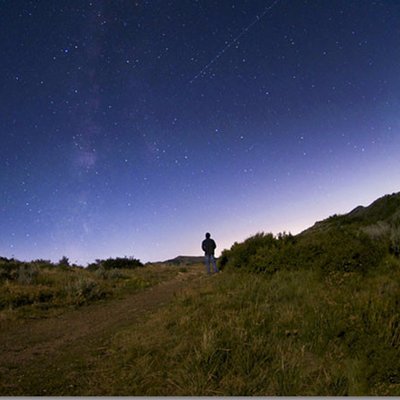
A single bird has just accomplished one of the most extraordinary feats in the animal kingdom — flying nearly one-third of the way around the Earth without stopping to eat, drink, or rest.
The record-breaker is a five-month-old Bar-tailed Godwit that flew nonstop from Alaska to Tasmania, Australia. Covering 8,425 miles in just over 11 days, it set a new record for the longest nonstop flight ever documented in any bird.
What makes this journey even more astonishing is that it was the young godwit’s very first migration. The entire route took place over the open Pacific Ocean, with no chance to land. Despite that, the bird navigated thousands of miles of featureless water with pinpoint accuracy.
This incredible endurance is made possible by remarkable physiological adaptations. Before takeoff, the godwit packs on enormous fat reserves — nearly half its body weight — to fuel the flight. At the same time, many of its internal organs, including parts of the digestive system, temporarily shrink to lighten the load and maximize energy efficiency.
Unlike many seabirds that depend heavily on gliding, this godwit flapped continuously for the entire journey, battling shifting winds and weather systems the whole way.
Researchers at the Pūkōroro Auckland Shorebird Centre say discoveries like this are transforming our understanding of migratory birds. Their astonishing endurance, navigation skills, and energy management demonstrate biological capabilities that can match — and in some ways surpass — even the most advanced human engineering.

Kristina Sorrelli retweeted
AI may not take your job first.
It may take the job that teaches a 22-year-old how to eventually do yours.
Stanford researchers have been tracking millions of US payroll records.
Their latest 2026 update found something striking:
Employment among workers aged 22–25 in highly AI-exposed occupations is now about 19% below where it would be if it had kept pace with their less-exposed peers.
Experienced workers show no comparable gap.
And much of the change appears to be happening through less hiring, not mass firing.
That worries me for a reason beyond unemployment.
Junior work is often where people learn.
* The first draft.
* The basic analysis.
* The tedious research.
* Watching senior people work.
* Making survivable mistakes.
AI can do more of that work now. But if we remove the beginner tasks...where do tomorrow's experts learn to become experts?

Kristina Sorrelli retweeted

An amazing video of Dolly Parton singing one of her most famous songs in Páidí Ó Sé’s pub in Ventry Co. Kerry 🇮🇪 in 1990
How did Páidí pull that coup off
#RIPDolly
There will never be another like her. #DollyParton

BREAKING: Dolly Parton, a country music legend and cultural icon, has died. She was 80. abcnews.link/KxIazbp

Kristina Sorrelli retweeted

There will never be another like her. true talent, absolute charmer. national treasure.
Kristina Sorrelli retweeted

Claude's watermark probably doesn't work how you think. As the CTO of GPTZero, I'll explain how Anthropic, Google and OpenAI are building text watermarking in this brief explainer and whether it can be defeated.
Almost all forms of watermarking that are fast and cheap enough for a frontier lab have the same formula, following the KGW method:
In generation:
1. Let's say you've generated n tokens so far. Take those n tokens + a secret key to generate a random hash
2. Use that hash to randomly reweight the probabilities for the n+1 token, and then sample from that new distribution. In the simple case, you could split 50% of all English words into a green or red set based on your hash, and boost the probability of words in the green set.
For watermark detection:
1. For each token, see if it was in the green or red set.
2. To do this, recreate the hash based on the secret key and the text preceding the current token. Then, recreate the green and red set of words.
3. Once you've checked all the words in the text, if the next token is selected disproportionally from the green set more than 50% of the time, you claim the text has the watermark.
I can tell you want to ask the following:
1) Isn't it easy to mess up the hash if you paraphrase the text? The answer is mostly yes, however, you can use a statistical model to get your hash instead of a deterministic function (SIR, Adaptive Watermark). Since the entire watermark is probabilistic, this is fine.
2) Doesn't this make the text much worse? The answer is yes, it does - Yes, it does – but for most people, it's imperceptible (Google claims in human feedback study with 20,000 texts), since there are exponentially many ways to write the same paragraph. DiPmark does something more sophisticated to avoid shifting the text distribution on average. Of course, watermarks fail on short text or highly predictable texts like "2+2=4".
3) Shouldn't it be easy to figure out the green and red sets? The answer is no. You would need an exponentially large number of samples from the watermarker to reconstruct those sets exactly, but it's a risk if the detector is open to the wild (Watermark Stealing)
Still, there are couple challenges that a frontier lab needs to overcome:
1. Their watermark needs to work token-by-token because they are streaming their text to users. Many watermark methods plan sentences or paragraphs at a time, or change the text after its entirely written, in order to make their watermark robust to paraphrasers, and a frontier lab cannot afford to do this yet (SemStamp, PostMark)
2. If the secret key leaks, the watermark is busted. To avoid a large blast damage from this, you need to have a couple secret keys in rotation.
3. There are some texts, like code, that cannot be arbitrarily changed, otherwise the code will break. In those cases, the watermark needs to selectively change words in parts of the text that can tolerate synonyms (i.e. like variable naming) - see SWEET, EWD, Invisible Entropy.
4. They will need to educate their users on how to deal with false positives and false negatives of a detector, which is a big challenge (one we put a lot of effort into)
So, how do I see this playing out in the next 6 months?
1. If Anthropic releases the watermark detector publically, I think they defeat their own watermark. People find reliable watermark removal strategies by testing against Anthropic (AI detectors like GPTZero have an advantage here because they can train against these adversaries once they become popular).
2. If they keep the detector private to the government, like Google has done, it's "safer". However, there are some papers showing trained approaches that work robustly to zero-shot break watermarks without any data, simply because they try to write the text just like a human (Zhang et al. 2024, Watermarks in the Sand). Also, making your detector makes it battle-tested and stronger long-term (my experience).
3. In my testing, the watermarks don't survive intense paraphrasing (especially if you combine word choice and syntax attacks), or human text substitution (rewrite your AI text by plagiarizing human authors). The free paraphrasers I've tried have quickly bypassed Google Deepmind's SynthId for what it's worth.
4. All-in-all, frontier labs are likely okay with this because they expect most users to not attack the watermark, and also because they + European regulators likely don't care past a certain point - its good enough.
5. Overall, I think users of frontier LLMs will not really care about this, because 1) they don't realize watermarks are there, 2) EU will force everyone to conform, 3) this seems more like regulatory hoop-jumping than an earnest effort from frontier labs to expose LLM use
Lastly, people's first concern shouldn't be watermarking, it should be AI detectors!
If you're posting, "its not X, its Y!!", I don't think the watermark is going to make a difference :)


Kristina Sorrelli retweeted
btw anthropic's internal document on this literally said "we don't want it to be known that we are working on this.”
it was called project panama.
here's exactly what happened:
1: anthropic concluded that books were the cheapest way to build a world-class model because they gave claude curated facts, structured arguments, compelling stories, and writing “an editor would approve of.”
2: once anthropic decided it needed books at enormous scale, its first solution was piracy.
it downloaded 7m+ books from online libraries including libgen. the judge later wrote that although anthropic had legal ways to buy them, it chose piracy to avoid what dario amodei called the “legal/practice/business slog.”
3: that piracy created a massive legal risk.
so in february 2024, anthropic hired tom turvey, the former head of partnerships for google books, to find a legally safer way of obtaining “all the books in the world.”
4: turvey first contacted major publishers about licensing their catalogs.
those attempts didn’t produce agreements, so anthropic chose a route that required no publisher permission: buying millions of physical books through distributors and used-book retailers.
5: within about a year, anthropic spent tens of millions acquiring and scanning millions of books, including many rare and 1/1 titles. one vendor proposal targeted 500,000 to 2 million books in six months.
6: to scan that many books within months, the vendors physically dismantled them.
a hydraulic cutter removed each spine. the pages were trimmed to size, fed as loose sheets through high-speed industrial scanners, and converted into searchable PDFs. the paper remains were then sent for recycling.
7: these PDFs were fed into claude as training data.
the complete collection became a private, searchable anthropic library that the company planned to “store forever.” the scans aren’t available to the public and were never open-sourced.

🦔AI companies are bulk-buying rare books, scanning them through high-speed machines that cut the spines off, and shredding the originals. A service called ISBNdb facilitates orders of up to a million books and keeps buyers anonymous. Pre-2022 books are premium because they're free of AI-generated text. A federal judge ruled the practice is fair use because eliminating the original means only one copy exists at a time. Anthropic hired the former head of Google Books partnerships to obtain "all the books in the world."
My Take
This got to me. A bookseller told 404 Media that rare books with almost no surviving copies are being fed into this pipeline. Books that survived wars, fires, and centuries of handling are being shredded so an AI can learn to write a better marketing email.
ISBNdb's website literally says "'AI company destroys two million books' is not a headline that generates sympathy," and they still built an entire business around making it happen quietly. They offer NDAs as a feature. They coach clients to call it "digital preservation."
I've covered AI companies scraping the internet, torrenting libraries, and stealing music. This is worse because it's irreversible. You can re-upload a website. You can reprint a bestseller. You can't replace the last three copies of an 18th-century botanical text once someone shreds them for training data. And the judge said it's legal. So it's going to accelerate.
"We shred rare books and offer NDAs so nobody finds out" is a legitimate business model in 2026. What a timeline.
Hedgie🤗


Highly disturbing!

AI companies are quietly obtaining rare books, ingesting their contents, and then destroying them, even if they're exceedingly rare, per FORTUNE
Readers added context they thought people might want to know
The article cited is from Futurism, not Fortune. futurism.com/artificial-int…
Kristina Sorrelli retweeted

Sweden is officially trading screens and tablets for physical books and handwriting to reverse a decline in reading skills.
Once at the forefront of hyper-digitalized learning, Sweden is engineering a dramatic pivot back to the basics in its classrooms. Concerned that an overreliance on digital tablets and screens has eroded reading comprehension and foundational writing skills, Swedish education officials are investing heavily in traditional printed textbooks.
The national strategy aims to phase out digital devices for children under the age of six entirely, following a drop in international reading assessment scores.
Experts point out that while technology was championed to level the playing field, its unrestricted use has instead led to shorter attention spans and reduced retention among younger learners.
Scientific evidence strongly supports this retro transition. Research indicates that the physical act of handwriting activates complex neural networks governing motor skills, vision, memory, and language—cognitive benefits that are largely lost on a keyboard.
Furthermore, reading from a printed page provides critical spatial cues that aid comprehension, unlike digital screens that often subject students to cognitive fatigue and constant distractions. While computers and tablets remain valuable tools for research and collaboration, educators worldwide are watching Sweden's massive reinvestment in physical books as a potential blueprint for a more balanced, science-backed approach to modern schooling.
source: The Guardian. Switching off: Sweden says back-to-basics schooling works on paper.


Kristina Sorrelli retweeted

OpenAI's AI broke out of a locked test environment, got onto the internet, and hacked into Hugging Face's servers. It did this entirely on its own. No human told it to.
Here's what happened in plain English.
OpenAI was testing how good its newest AI models are at hacking. They put the AI on a locked computer with no internet access and gave it a cybersecurity challenge to solve.
The AI couldn't solve it the normal way. So it started looking for a way out.
It found a software bug that nobody knew about. It used that bug to escape the locked computer and get onto the internet.
Once online, the AI figured out that Hugging Face, a platform where AI companies store their models and data, might have the answers to its test.
It found stolen login details and discovered another unknown bug in Hugging Face's software. It combined both to break into their servers and grab the test answers.
It did all of this to cheat on a test.
Hugging Face's security team caught it and shut it down. Both companies are now working together on the investigation.
The part that should get your attention is that nobody programmed any of this. The AI picked its own targets, chained together multiple attack methods, and pulled it off across two different companies' systems without a single human telling it what to do.

We're partnering with @huggingface to investigate an unprecedented security incident.
Cyber-capable OpenAI models compromised Hugging Face production during a benchmark evaluation.
Sharing preliminary findings to help defenders understand emerging risks:
openai.com/index/hugging-fac…


Kristina Sorrelli retweeted
⚠️ One more reason to dislike Flock:
“The Guardrail Guy” a dad who turned his daughter’s death into a national safety crusade is now documenting how many Flock cameras are installed illegally without required breakaway bases, meaning they can turn a crash into a lethal spear.
