

Research Lead @Amazon | Self-improving AI | ex-@CarnegieMellon, @MSFTResearch | DM for Collab | Building https://xitter.cf/t.co/VoJrRsndf3 | Co-Lead @OpenRSI
San Francisco, CA
Joined June 2016
- Tweets565
- Following161
- Followers778
- Likes547



Pinned Tweet
Can we train language models to propose better ideas to improve LM—not just run them?
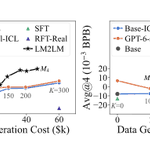
Introducing 𝐋𝐌𝟐𝐋𝐌: Language Models Learn to Improve Language Models. We train a 27B model with RL to propose improvements to language models. On held-out autoregressive and diffusion LM development tasks, it outperforms 𝐆𝐏𝐓-𝟔-𝐬𝐨𝐥 —at 33% lower data-generation cost. It also generalizes to a model family unseen during training.
𝐓𝐡𝐞 𝐛𝐨𝐭𝐭𝐥𝐞𝐧𝐞𝐜𝐤: evaluating every proposal with a real training run makes RL prohibitively expensive.
𝐎𝐮𝐫 𝐚𝐩𝐩𝐫𝐨𝐚𝐜𝐡: a Research World Model (RWM) predicts experimental gains as a cheap reward signal. We periodically execute the current policy’s top proposals and add the measured outcomes to the RWM’s context, keeping its predictions calibrated as the policy evolves.
This is a step toward cheaper, more reliable feedback loops for recursive self-improvement (RSI).

Also congrats to the authors of two papers @linminhua16 @Zevin_Liu @zijun_wang2002 @WengZhaoti39773 @binghe2727 @sammyershi @dakuowang @YisiSang Suhang Wang @cihangxie @yuyinzhou_cs Wei Jin Benoit Dumoulin Xiang Zhang
Related Paper (AI Research World Model): arxiv.org/abs/2610.12235
LM2LM Paper: arxiv.org/abs/2610.23344

𝐁𝐞𝐭𝐭𝐞𝐫 𝐩𝐫𝐨𝐩𝐨𝐬𝐚𝐥𝐬, 𝐥𝐨𝐰𝐞𝐫 𝐜𝐨𝐬𝐭. LM2LM-trained Qwen3.8-27B outperforms GPT-6-sol—even when GPT-6-sol receives 300 real experimental records in context—at 33% lower data-generation cost.
These gains are measured by actually running the proposed experiments.
Average improvement over 4 executed proposals from different models. (10⁻³ BPB; higher is better)

The widely cited 𝟏𝟔× pretraining compute gap has made diffusion LMs look prohibitively expensive to train from scratch. Our new work with @Guanghan__Wang and collaborators revisits that assumption across ~𝟏,𝟕𝟎𝟎 models. With exact-likelihood evaluation and modern block-diffusion architectures, we find a 𝟑–𝟖× gap at matched likelihood, depending on block size.
This is what LM research often looks like: running large numbers of experiments to establish a robust finding.
It raises a natural next question:
𝐜𝐚𝐧 𝐀𝐈 𝐥𝐞𝐚𝐫𝐧 𝐟𝐫𝐨𝐦 𝐞𝐱𝐩𝐞𝐫𝐢𝐦𝐞𝐧𝐭𝐚𝐥 𝐞𝐱𝐩𝐞𝐫𝐢𝐞𝐧𝐜𝐞 𝐭𝐨 𝐜𝐡𝐨𝐨𝐬𝐞 𝐛𝐞𝐭𝐭𝐞𝐫 𝐞𝐱𝐩𝐞𝐫𝐢𝐦𝐞𝐧𝐭𝐬—𝐚𝐧𝐝 𝐚𝐜𝐜𝐞𝐥𝐞𝐫𝐚𝐭𝐞 𝐢𝐭𝐬 𝐨𝐰𝐧 𝐫𝐞𝐬𝐞𝐚𝐫𝐜𝐡?
More on our RSI work soon.

Diffusion language models (DLMs) are often seen as inefficient to pretrain, said to need 16x the compute of autoregressive models to reach the same likelihood.
We revisited this with ~1,700 models. Under current DLM practice, the gap is 3-8x, not 16x.
guanghanwang.com/dlm-scaling

Paper: arxiv.org/abs/2610.17590Proj…
Website: guanghanwang.com/dlm-scaling
Code: github.com/amazon-science/dl…
Henry Lu retweeted

New Amazon paper shows that an LLM can act as a research world model, predicting whether a training change will help before anyone spends GPU time on it.
AI research agents can propose experiments far faster than teams can afford to run them. Choosing what gets GPU time means guessing outcomes in advance.
They used an LLM as a research world model that predicts an experiment's gain before it runs. They tested it on 2,653 real experiment records from 9 setups, from pretraining to inference.
Past records from the same setup raised average ranking correlation with actual results from 0.506 to 0.774 across 5 setups. On the OLMo3-100M setup, adding records at low reasoning effort scored 0.892, while max effort without records reached 0.648.
If you run research agents, log every experiment, including failures, and feed those records to whatever model picks the next run.

Henry Lu retweeted

4/ Our Team
OpenRSI-Index is initiated with partners across UW, UC Berkeley, Harvard, Stanford, Princeton, MIT, and more.
Grateful to our advisors: @WenhuChen, @alvinkcheung, @YejinChoinka, @JianfengGao0217, @HannaHajishirzi, @PangWeiKoh, @RanjayKrishna, @HenryL_AI, @karthik_r_n, Kunle Olukotun, @rpanda89, @UWEEChair, @dawnsongtweets, @ysu_nlp, @hhsun1, @Diyi_Yang, Ming-Hsuan Yang, @xiangyue96, @JianZhangCS, @yuz9yuz, @LukeZettlemoyer.
Grateful to our wonderful team: @yuetai12575, @zhuofengli96475, @YichenFeng_, @David_Han66, @wenhaocha1, @ChengleiSi, @NuoJohnChen, @zhcui0408, @ShangdingG95714, @rilyn_han, @ZhengyuHu477, @HangHua_, @HowieH36226, @CaraLi72918, @lihanc02, @nathan_sj_stem, @XiangLiu1995, @lupantech, @Lyubh22, @zixianma02, @MangQiuyang, @RulinShao, Venkat Srinivasan, @YiyouSun , @makingAGI, @nwang22, @yangzhen04, @jianxie_, @bri25yu , Gaoyuan Zhang, @qizhengz_alex , Weichen Zhang , Kaiyuan Zheng

Proud to co-lead and advise @OpenRSI . Here's why I think it matters:
Every RSI claim today is evaluated at the scale where retries are cheap — and cheap retries are exactly what disappear when a single trial is a 20K-GPU-hour training run. Whether the loop survives that regime is the actual question, and until now nobody could check.
What makes this benchmark different is the signature tasks — and designing them was the hard part. At 1k-GPU scale, a task has to clear four bars at once:
- the lane has to matter (a real pre/post-training recipe, not a toy)
- the verifier has to sit outside the agent's reach
- the human baseline has to be a matched rerun rather than a paper number
- the whole thing has to stay runnable on someone else's cluster.
Most benchmarks get one or two of these. Getting all four is expensive and unglamorous, which is why it hadn't been done — and why the Marin results, small as they are, are the first verifiable datapoints of an agent beating a human-designed method at scale.
Lucky to be building this with a community that actually wanted to do the unglamorous part. If you have a real training lane or spare compute, contribute — this is the ruler the next two years will be measured with.

As AI systems enter a recursive self-improvement loop, the central question is whether it can systematically move beyond human-designed methods to genuinely extend the scientific and intelligence frontier.
What’s missing is a neutral, open standard for evaluating these capabilities in real, production-scale intelligence development.
Today, we’re releasing OpenRSI-Index v0.1: evaluating whether AI can recursively improve itself and push the boundaries of intelligence and science, on production-scale clusters with 1k GPUs.
We turn fully open-source projects into autoresearch environments, with agent trajectories lasting 60+ hours. Building v0.1 took 100K+ H100-hours.
We’re building an ecosystem with and for the research community: let RSI benefit everyone, and let everyone shape RSI together.
We invite task contributors and compute partners to build this open benchmark with us - all contributors will be included as paper authors.
Shape RSI with us:
🌐 Website: index.openrsi.foundation/ind…
🛠️ GitHub: github.com/OpenRSI-Foundatio…
🤝 Contribute: github.com/OpenRSI-Foundatio…

Humanity has entered a new 𝐀𝐠𝐞 𝐨𝐟 𝐃𝐢𝐬𝐜𝐨𝐯𝐞𝐫𝐲. Frontier models are the 𝐬𝐡𝐢𝐩𝐬. Everyone is racing to launch a bigger flagship.
Navier–Stokes falling to an agent fleet in 88 hours is a landfall — not the shipyard.
RSI is what matters. It is how you use this ship to build the next one. Ships go obsolete. Shipyards don’t.
🤖 Made with AI

ALT AI Models are the Ships of the New Age of Discovery

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

Excited to share that two of our papers on self-improving agents have been accepted to 𝐄𝐌𝐍𝐋𝐏 𝟐𝟎𝟐𝟔! Code for both is released in A-Evolve.
1. 𝐇𝐚𝐫𝐧𝐞𝐬𝐬 𝐔𝐩𝐝𝐚𝐭𝐢𝐧𝐠 𝐈𝐬 𝐍𝐨𝐭 𝐇𝐚𝐫𝐧𝐞𝐬𝐬 𝐁𝐞𝐧𝐞𝐟𝐢𝐭 — The evolver’s base capability barely matters. Harness benefit is non-monotonic: mid-tier agents gain the most.
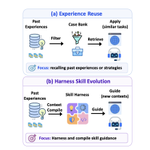
2. 𝐄𝐯𝐨-𝐇𝐚𝐫𝐧𝐞𝐬𝐬: 𝐂𝐨𝐧𝐭𝐞𝐱𝐭-𝐭𝐨-𝐇𝐚𝐫𝐧𝐞𝐬𝐬 𝐒𝐤𝐢𝐥𝐥 𝐂𝐨𝐦𝐩𝐢𝐥𝐚𝐭𝐢𝐨𝐧 — How to turn single noisy executions into reusable skill harnesses on the fly.
Both works dig into the same core question: 𝐖𝐡𝐚𝐭 𝐚𝐜𝐭𝐮𝐚𝐥𝐥𝐲 𝐦𝐚𝐤𝐞𝐬 𝐚𝐧 𝐚𝐠𝐞𝐧𝐭 𝐢𝐦𝐩𝐫𝐨𝐯𝐞 𝐢𝐭𝐬𝐞𝐥𝐟 𝐭𝐡𝐫𝐨𝐮𝐠𝐡 𝐢𝐭𝐬 𝐡𝐚𝐫𝐧𝐞𝐬𝐬
Congrats to the authors! @linminhua16 @wei_tianxin @sammyershi @binghe2727 @YisiSang @dakuowang @zijun_wang2002 @cihangxie @HenryL_AI
Paper links + more details in the replies 👇


When you building a self-improving agent, two natural questions emerge: 𝐐𝟏: 𝐖𝐡𝐢𝐜𝐡 𝐦𝐨𝐝𝐞𝐥𝐬 𝐩𝐫𝐨𝐝𝐮𝐜𝐞 𝐭𝐡𝐞 𝐛𝐞𝐬𝐭 𝐡𝐚𝐫𝐧𝐞𝐬𝐬 𝐮𝐩𝐝𝐚𝐭𝐞𝐬? 𝐐𝟐: 𝐖𝐡𝐢𝐜𝐡 𝐦𝐨𝐝𝐞𝐥𝐬 𝐛𝐞𝐧𝐞𝐟𝐢𝐭 𝐦𝐨𝐬𝐭 𝐟𝐫𝐨𝐦 𝐡𝐚𝐫𝐧𝐞𝐬𝐬 𝐮𝐩𝐝𝐚𝐭𝐞𝐬?
Our new paper has counter-intuitive answers to both: they decouple from model capability, in opposite ways.
Q1 (who produces good updates): the updater's base capability barely matters.A 9B model (Qwen3.5) produces harness updates that match Claude Opus 4.6's. Best vs worst evolver gap ≤3.1pp.
Q2 (who benefits most): non-monotonic.Mid-tier solvers benefit the most. Strong-tier hits ceiling. Weak-tier benefits LEAST despite the most headroom — failing at two layers: skill activation (25% vs ~96% for strong) and adherence drift across trajectory (~4x steeper).
Tested across 7 evolver models × 6 solver agents × 3 agentic benchmarks (SWE-bench Verified, MCP-Atlas, SkillsBench).
Implication: don't pay frontier prices for both halves of the loop. Put capability budget on the agent (solver), not the evolver.


Harness Updating is Not Harness Benefits: arxiv.org/abs/2605.30621
Evo-Harness: arxiv.org/abs/2608.15071
Code: github.com/A-EVO-Lab/a-evolv…

Jeff Dean isn't the first top researcher to quit a frontier lab for RSI. @MillionInt left OpenAI to build Core Automation. An ex-Anthropic team raised a $200M seed for @mirendil . @RichardSocher and @jeffclune founded Recursive. Same RSI mission — but not the same bet. What each is actually betting on, and how far they've gotten, in article: xitter.cf/HenryL_AI/status/20853…

Tomorrow will be my last day at Google after 27 years, and watching it grow from 25 people to 190,000+ has been an amazing journey. Below is a note I shared with many people internally at Google today. An excerpt is:
It has been an absolute pleasure to work with you and to help build some of the most widely used and impactful products of all time. As a kid, I dreamed of helping build software that would be used by many people, and Google now has thirteen products used by more than a billion people (amazing!). Our work has had a tremendous impact in the world, and I have been lucky enough to collaborate and form friendships with many colleagues that I deeply admire, respect, and enjoy. It still brings me joy every time I see people out in the world using our products to find information, handle email, translate documents, watch videos, learn new things, navigate and understand the physical world, browse the web, use their phone, run large-scale computations on our infrastructure, ride in an autonomous vehicle, or perform complex tasks with the help of our AI systems. I hope you all share this sense of joy, because it is a shared accomplishment! Thank you to all of my colleagues at Google over many years!
Now I'm excited to go start @DiscoLoopAI with my longtime friends and colleagues @Sanjay_Ghemawat, @OriolVinyalsML, and @quocleix.
(Updated post: slightly redacted to not have some personal info)


And the most interesting thing about Discovery Loop is the announcement they haven't made yet: their first benchmark. Benchmark choice is thesis statement. xitter.cf/HenryL_AI/status/20853…

.@lilianweng 's new survey on self-improving harness places our findings where it belongs in the field's arc: STOP (2023) showed recursive structure alone isn't enough — the base model must be capable enough to improve the mechanism. 𝐎𝐮𝐫 𝐟𝐨𝐥𝐥𝐨𝐰-𝐮𝐩: that sentence needs splitting in two.
𝐂𝐚𝐩𝐚𝐛𝐥𝐞 𝐞𝐧𝐨𝐮𝐠𝐡 𝐭𝐨 𝐢𝐦𝐩𝐫𝐨𝐯𝐞 𝐭𝐡𝐞 𝐡𝐚𝐫𝐧𝐞𝐬𝐬? Almost any model — updating is flat, a 9B matches Opus.
𝐂𝐚𝐩𝐚𝐛𝐥𝐞 𝐞𝐧𝐨𝐮𝐠𝐡 𝐭𝐨 𝐛𝐞𝐧𝐞𝐟𝐢𝐭 𝐟𝐫𝐨𝐦 𝐢𝐭? That's the real constraint — and it's non-monotonic.
If you're deciding where to spend capability budget in a self-improving loop, the survey's Self-Improving Harness section is the best 10-minute map of this space: lilianweng.github.io/posts/2…
When you building a self-improving agent, two natural questions emerge: 𝐐𝟏: 𝐖𝐡𝐢𝐜𝐡 𝐦𝐨𝐝𝐞𝐥𝐬 𝐩𝐫𝐨𝐝𝐮𝐜𝐞 𝐭𝐡𝐞 𝐛𝐞𝐬𝐭 𝐡𝐚𝐫𝐧𝐞𝐬𝐬 𝐮𝐩𝐝𝐚𝐭𝐞𝐬? 𝐐𝟐: 𝐖𝐡𝐢𝐜𝐡 𝐦𝐨𝐝𝐞𝐥𝐬 𝐛𝐞𝐧𝐞𝐟𝐢𝐭 𝐦𝐨𝐬𝐭 𝐟𝐫𝐨𝐦 𝐡𝐚𝐫𝐧𝐞𝐬𝐬 𝐮𝐩𝐝𝐚𝐭𝐞𝐬?
Our new paper has counter-intuitive answers to both: they decouple from model capability, in opposite ways.
Q1 (who produces good updates): the updater's base capability barely matters.A 9B model (Qwen3.5) produces harness updates that match Claude Opus 4.6's. Best vs worst evolver gap ≤3.1pp.
Q2 (who benefits most): non-monotonic.Mid-tier solvers benefit the most. Strong-tier hits ceiling. Weak-tier benefits LEAST despite the most headroom — failing at two layers: skill activation (25% vs ~96% for strong) and adherence drift across trajectory (~4x steeper).
Tested across 7 evolver models × 6 solver agents × 3 agentic benchmarks (SWE-bench Verified, MCP-Atlas, SkillsBench).
Implication: don't pay frontier prices for both halves of the loop. Put capability budget on the agent (solver), not the evolver.
.@lilianweng survey maps how self-improving AI / AI scientist are built. We wrote down the question it leaves open — 𝐡𝐨𝐰 𝐭𝐨 𝐞𝐯𝐚𝐥𝐮𝐚𝐭𝐞 𝐭𝐡𝐞𝐦. Our answer: measure comfort, not benchmarks.
- How many GPU-hours are humans comfortable handing the system, unattended?
While sounds unscientific, this has played out once in public. In 2023 nobody let a model edit their codebase unattended. Cursor's real invention was not a better model — it was the per-diff accept/reject. Now in 2026, almost everyone will choose agent mode and accept every changes (the trust to the AI coding system).
X article: xitter.cf/HenryL_AI/status/20748…


new post on harness engineering for AI self-improvement: lilianweng.github.io/posts/2…
It is hard to forecast how much the future of RSI will rely on harnesses. Likely harness engineering will evolve in the direction of self-improvement and enable auto-research, and, in turn, smarter models keeps harnesses simple.
Even when many harness improvement get eventually internalized into core model, the need to specify goals and context will not disappear.
Current Recursive Self-Improving AI misses a 𝐩𝐮𝐛𝐥𝐢𝐜 datapoint: AI trains a frontier-class model. Today we share 𝐀-𝐄𝐯𝐨𝐥𝐯𝐞-𝐓𝐫𝐚𝐢𝐧𝐢𝐧𝐠 that 𝐚𝐮𝐭𝐨-𝐩𝐨𝐬𝐭-𝐭𝐫𝐚𝐢𝐧𝐞𝐝 𝐚 𝟑𝟎𝐁 𝐍𝐞𝐦𝐨𝐭𝐫𝐨𝐧 model with no human-in-the-loop.
~10²× larger than prior public autoresearch (GPT2, ~124M) demos.
It achieved 0.86 on NVIDIA Nemotron Reasoning Challenge (snapshot 6/1 as of writing the tech report) vs human #1's 0.87.
Same system has been run at 𝟏𝟐𝟎𝐁 𝐚𝐧𝐝 𝟓𝟓𝟎𝐁 scale; effectiveness claim deferred at those scales pending human anchor.
But the important part is not the score: the loop didn't just execute — it discovered a flaw in its own optimization, and inverted its own objective mid-campaign.
👇Tech report and website


Our internal data shows Claude is accelerating AI development—a possible path to recursive self-improvement, or AI autonomously building a more capable successor.
It’s happening faster than we thought, and the implications deserve greater attention. anthropic.com/institute/recu…

𝐃𝐢𝐬𝐜𝐨𝐯𝐞𝐫𝐲, 𝐧𝐨𝐭 𝐣𝐮𝐬𝐭 𝐨𝐩𝐭𝐢𝐦𝐢𝐳𝐚𝐭𝐢𝐨𝐧
The A-Evolve-Training auto-post-train loop discovered that its own proxy had become misleading.
It optimized the internal dev metric to record highs, saw those gains fail to transfer, then changed the search policy itself: stop maximizing the proxy, look for interventions that might lower it while improving the external target.
That is the moment this became interesting.
Not "AI ran our experiments faster."
Not "AI tuned some hyperparameters."
But an autonomous research loop falsifying a premise of its own search.

𝐎𝐧𝐞 𝐦𝐨𝐫𝐞 𝐬𝐭𝐞𝐩 𝐭𝐨𝐰𝐚𝐫𝐝𝐬 𝐑𝐒𝐈
A-EVO-Lab studies RSI under one thesis — AI-as-researcher: frontier agents and models play the researcher in the loop that builds better AI.
RSI will not arrive as one magic model waking up and rewriting itself. It will look like AI systems taking over the actual work humans do to build AI:
— harness building
— post-training
— pre-training
Auto-harness and post-training both have public reports & papers.
Follow us for public datapoints on AI systems learning to build AI.
GitHub: github.com/A-EVO-Lab
