

deport machines they're taking our jobs
🍞
Joined September 2018
- Tweets519
- Following1K
- Followers254
- Likes6.7K







Alex Pan ♻︎ retweeted

I think this is the most important concept to understand right now: LLMs can’t jump.
OpenAI says an internal version of Astra, its next major model, has solved ten major open problems in mathematics and theoretical computer science.
This is extraordinary.
And I don’t use this word lightly.
During my PhD in mathematics, I worked on a problem closely related to Gromov’s conjecture. For decades, constructing a non-sofic group—an infinite group whose finite pieces cannot be approximated by finite groups—was a dream shared by many of us.
Now Astra appears to have done it.
This is not a toy result. This is serious mathematics.
But it is not “the most significant day in the history of mathematics”, as some have claimed.
This claim confuses scale with kind.
Astra has solved difficult problems inside existing conceptual worlds.
Calculus, topology, and scheme theory created new conceptual worlds.
They did not merely answer questions. They changed which questions mathematics could ask.
Induction finds patterns. LLMs are extraordinary at it.
Deduction follows implications. Using symbolic AI tools, LLMs are becoming formidable at traversing chains of logic that humans missed, abandoned, or could never afford to search.
But abduction is different.
Abduction invents the right concept, the right representation, the right question.
That is the jump.
Current LLMs can fill the gaps of knowledge left by humans.
But they can’t jump beyond the external boundary of existing knowledge.
*
Full paper in the first reply

Alex Pan ♻︎ retweeted

Today we’re officially launching @explabsai on YC.
Companies spend more on AI every month, but none of it becomes an asset they own.
Up to 97% cheaper and 50% higher quality.
Alex Pan ♻︎ retweeted

i am no longer impressed by news of models escaping and hacking into external systems during cybersecurity testing . i want to see a model kill
Alex Pan ♻︎ retweeted

I would have assumed it was fairly obvious, but in case it's not: a million-line codebase (also known as a "harness"), running at inference time, orchestrating thousands of calls to a neural network for any given task, is the exact definition of a "neurosymbolic architecture"
Alex Pan ♻︎ retweeted
Prime Agent is a general-purpose coding harness
On ARC-AGI-3, it scores 95.5%, surpassing the human-expert baseline, but the gain is not benchmark-specific.
We see major improvements across models when compared to their proprietary harnesses:

Alex Pan ♻︎ retweeted
Travis is an apex predator put on ice in 2017 and only recently reactivated from cryogenic slumber.
Standards for male behavior have moved so far that he's actively perplexed by it.
Our current ecology was last home to performative frat bros nearly a decade ago.
So when Travis tells TBPN he jet skis to work, and Jordi + John ask whether he does his best thinking on the jet ski, he pauses.
You can visibly see him get confused, with an expression like "What the fuck are you guys talking about?"
Then he quite literally voices his frustration: "No guys...it's a fucking notch on the belt. Who else do you know who jet skis to work? Nobody. I'm the guy."
Even the literal technology brothers are incapable of fathoming a man who does things just for the bit.
Travis in 2026 is like the T-rex from Jurassic Park 2 who finds himself in modern day San Diego being like, yo, what the FUCK is this place?
And then just stomps everything in sight.
xitter.cf/tbpn/status/2081039302…

.@travisk's commute takes 5 minutes on a jet ski going 70 mph on Lake Austin.
"Who else do you know is jet skiing to work? Nobody. I'm the guy."


Alex Pan ♻︎ retweeted
Standard RL benchmarks are episodic and stationary, so they don't capture the the characteristics of real-world deployment. Morpheus is a new benchmark for continual learning that provides persistent simulation environments where the world never resets, objectives shift asynchronously, and decisions have compounding consequences. Nice work by Sam & team!
Check out the paper - openreview.net/pdf?id=31P1VA…
Platform website - morpheus.skyfall.ai/

Today we present Morpheus, a persistent enterprise simulation platform designed to make Continual Learning a reality. Morpheus is the world’s first real world Reinforcement Learning environment.
Every Reinforcement Learning environment operates in the game world. Benchmarks like Atari, OpenAI Gym, MuJoCo, and Procgen are all small, game-like worlds that reset every few minutes.
But the real world never resets. A business keeps running and evolving everyday.
We tested how frontier LLMs would perform in realistic and dynamic business environments 🧬on Morpheus. The main conclusion was that LLMs are not continual learners.
🧵Here’s how we did it and what we learned:

Alex Pan ♻︎ retweeted

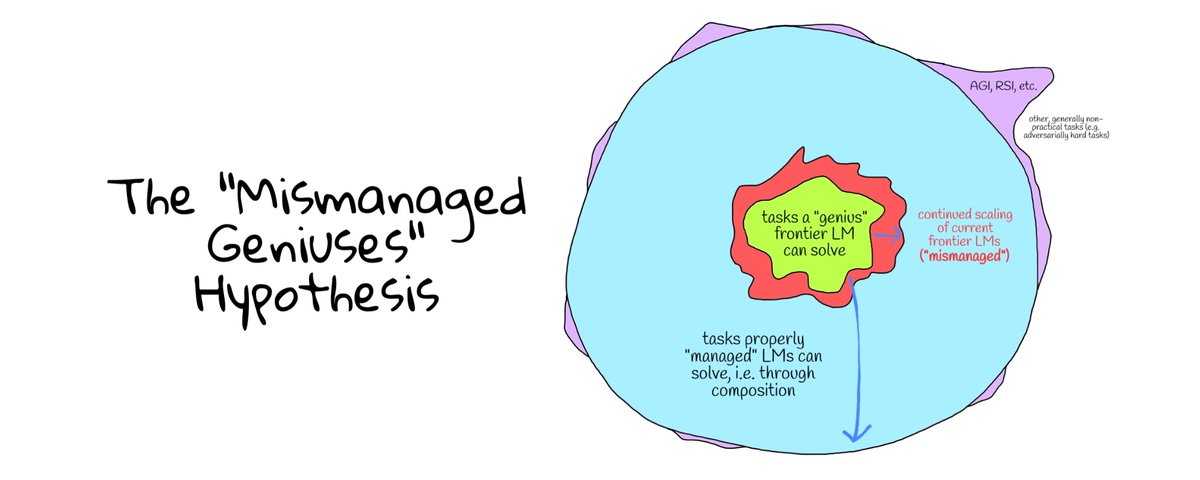
The first experimental evidence of recursive self-improvement (RSI).
Autoresearching the autoresearch agent for eight days.
The result beats the harness we hand-tuned for two years, on held-out benchmarks: 🧵(1/7)


Alex Pan ♻︎ retweeted

I ran Claude in a loop for 3 months and created a brand new "GenZ" programming language.
It's called @cursedlang.
v0.0.1 is now available, and the website is ready to go.
Details below!


Alex Pan ♻︎ retweeted

📈 now trending on alphaXiv
"SkillRL: Evolving Agents via Recursive Skill-Augmented Reinforcement Learning"
SkillRL turns an LLM agent’s messy trial-and-error trajectories into a compact & searchable skill library that recursively grows during RL
This lets the agent actually learns reusable strategies over time instead of just replaying raw memories, yielding big gains (+15.3% over strong baselines) with far fewer tokens!

Alex Pan ♻︎ retweeted

new preprint!
turns out, if your model is confident on _any_ long enough input, we can find other inputs where the model is wrong, yet its perplexity won't really tell you it's wrong 📉
work with @fedzbar @ccperivol @sindero and Razvan


Alex Pan ♻︎ retweeted
"Recursive Language Models"
A potentially big direction for LLMs in 2026 from MIT researchers
In their approach, a prompt isn’t “run” directly, instead it’s stored as a variable in an external Python REPL, and the language model writes code to inspect/slice/decompose that long string, observes execution outputs, and then constructs sub-tasks where it recursively invokes an LLM on just the relevant snippets. Stitching the result together when the recursive process ends.
so it can solve 10M+ token tasks with far less “context rot” and often lower cost than summarization/RAG, turning long-context scaling into an inference-time algorithm rather than just a bigger context window.

Alex Pan ♻︎ retweeted
We talk about (and compare against) context compaction in the RLM paper.
TLDR: sadly, compaction is a deeply flawed approach "for tasks that require dense access to many parts of the prompt".
This is because compaction "presumes in effect that some details that appear early in the prompt can safely be forgotten to make room for new content".
For genuinely hard long-context tasks, you need to be able to re-access just about any part of the context later! Nothing is safe to forget.

I’d be curious if you guys found the gap between pure compaction and a full RLM went down as the quality of model doing the compaction went up. My hypothesis would be that as models get smarter (and maybe have more compaction specific training) they get better at regulating state and therefore the need for recursion goes down