

PhD student @unc @unccs @unc_ai_group; Research Intern @Snowflake❄️; Formerly @AMD @AmazonScience @MSFTResearch @NlpWestlake. Views are my own. He/him
Chapel Hill, NC, USA
Joined July 2019
- Tweets274
- Following627
- Followers339
- Likes1.3K






Pinned Tweet
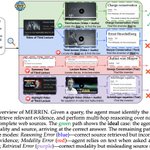
🚨 Excited to announce MERRIN: a human-annotated, expert-vetted benchmark for Multimodal Evidence Retrieval and Reasoning in Noisy Web Environments! 🌐🔍
The web is noisy, conflicting, and multimodal. Even strong search agents fail when questions require reasoning across text, images, video & audio — MERRIN is built to diagnose exactly where they break down, via multi-hop reasoning on open-web search without explicit references to specific modality sources.

Han Wang retweeted

🚨 Excited to share WEDGE: From Failures to Learnable Worlds, our new work on policy-conditioned environment generation for navigation agents!
We found that even on the same navigation task, agents tend to fail under different environmental conditions. Yet most environment generators do not consider what each agent actually needs to improve.
🤔 This led us to a question: Can we use an agent's own failures to guide the generation of training environments?
➡️ We introduce WEDGE, a framework where an agent's failures shape the worlds it trains in next. WEDGE identifies the conditions under which each agent struggles and generates new environments that target those weaknesses while remaining learnable. After each round of adaptation, it re-diagnoses the agent to guide the next round of environment generation.
Thread🧵👇
Han Wang retweeted

🚨 We are hiring Tenure-Track and Full Professors in important and timely areas such as AI Safety**, Neuroengineering, as part of exciting campus-level strategic cluster hires with CS, and with several positions in the clusters. The Full Professor position in 'Safeguarding AI for Health' is jointly between our strong BioStats department and CS -- please spread the word and feel free to apply & reach out for any questions!
**broad emphasis incl. but not limited to machine learning theory, AI systems, interpretability, robustness, verification, human-AI interaction.

We are hiring at @unccs 🎉
▶️ Two TT Asst. Professors: 1 in Safeguarding AI in Health, 1 in Neuroengineering.
▶️ Full Professor jointly with Biostats.
Part of campus cluster hires (review begins Dec 1).
Plus, Teaching Faculty (review begins Nov 1).
cs.unc.edu/about/faculty-hir…

Han Wang retweeted

🚨 As agents become more capable, new safety and security risks continue to emerge, as highlighted by recent reports of AI agents taking unauthorized actions or leaking sensitive data. Therefore, we need runtime guardrails that can reliably enforce safety policies before agent actions are executed, while continually adapting to new risks.
Existing guardrails usually trade off adaptability and reliability: LLM-based guardrails can adapt with memory, but their decisions may be inconsistent. On the other hand, formal guardrails provide deterministic enforcement but are typically fixed and unable to incorporate new risks that appear after deployment.
🚀 We introduce VEPA, a lifelong formal guardrail for agents. It represents safety and security policies as executable symbolic rules that evolve from deployment feedback. These policies enable deterministic enforcement of agent actions and can be formally verified, avoiding the inconsistency and ambiguity that can occur with natural-language policies.
🧵⬇️

Han Wang retweeted

Can agents learn useful skills from frozen logs that people and agents already leave behind?
🚨Introducing TeleTune: We turn noisy offline telemetry into agent skills w/o access to a live environment during training!
+6.7% on WorkArena & +7.7% on Mind2Web 👉 up to 75x fewer tokens used for optimization. 🧵
Activity logs like user telemetry capture how people use software, but often (1) lack explicit task goals, (2) cannot be replayed to test each skill update, and (3) can be a noisy mix of multiple tasks.
We address these jointly in TeleTune, where we propose skill-guided progress, an offline metric that uses action-prediction errors to improve agent skills. Not only does optimizing it improve downstream performance, but it also saves token usage by 5 to 75x compared to validating skill updates in live environments!
Key takeaways:
1️⃣ TeleTune achieves 77.1% average success on WorkArena and 80.6% on Online-Mind2Web, outperforming the strongest baselines by +6.7% and +7.7% absolute
2️⃣ Optimizing offline skill-guided progress transfers to improvements in downstream task success
3️⃣ Offline optimization uses 5 to 75x fewer tokens than validating the skill edits in a live environment

Han Wang retweeted
Excited to share WOVEN! 🚀
The goal isn't just to teach models what the world looks like. It's to teach them how the world changes.
Our key finding: Visual transition reasoning is a shared, teachable primitive that transfers across diverse downstream tasks.
And the key to effective transfer? Teach the right reasoning operations, rather than simply matching scenes, actions, or domains.

🚨 What makes good world-model training for MLLMs that actually transfers across tasks?
🧶 Excited to share our new work, WOVEN!
🧩 Spatial, physical, temporal, and embodied reasoning all require understanding how the world changes.
🔁 We view world modeling through state transitions p(s′ | s, a), and study visual transition reasoning: inferring what is unobserved in (s, a, s′).
🤔 Can visual transition reasoning be learned as a shared primitive that benefits multiple downstream tasks?
🤔 If so, how should we train it for better downstream gains?
Major takeaways:
➡️ Visual transition reasoning is a shared, teachable primitive that transfers widely downstream: ~2K-example subsets collectively improve 22 of 26 downstream benchmarks by up to 27.3 points.
🧪 A data-centric training recipe: to teach this shared primitive for downstream tasks, select supervision by the reasoning operation it teaches, rather than scene/action/domain similarity.
Thread🧵👇

Han Wang retweeted

Glad to announce that MetaCanvas has been accepted to #NeurIPS2026! ✨
MetaCanvas lets MLLMs reason and plan directly in spatial and spatiotemporal latent spaces, instead of reducing them to global text encoders for diffusion models. A set of learnable "canvas tokens" carries the MLLM's planning into the diffusion latent space through a lightweight connector, and visualizations show these canvas tokens act as reasonable visual planning sketches guiding the final synthesis.
Implemented on three diffusion backbones and evaluated across six tasks: text-to-image, text/image-to-video, image/video editing, and in-context video generation, each requiring precise layouts, robust attribute binding, and reasoning-intensive control. MetaCanvas consistently beats global-conditioning baselines, narrowing the gap between multimodal understanding and generation.
See you in Atlanta! 🚀

Multimodal LLMs (MLLMs) excel at reasoning, layout understanding, and planning—yet in diffusion-based generation, they are often reduced to simple multimodal encoders.
What if MLLMs could reason directly in latent space and guide diffusion generation with fine-grained, spatiotemporal control? 🤔
Introducing MetaCanvas 🎨
A lightweight framework that translates MLLM reasoning into structured spatiotemporal conditions for diffusion models.
🧵 👇
Han Wang retweeted
🎉 Excited that our NSF AI Institute for Engaged Learning has been renewed for another 5 years 🙏
Looking forward to leading the core AI efforts on 3D world models for multimodal narrative environments and AI that adapts to student needs -- and collaborating with our wonderful partners (top experts in education and learning sciences) to produce transformative advances in our understanding of how students learn and fundamentally improve the learning outcomes for K-12 students!
🚨 We'll be hiring postdocs+ phd students etc. for the next 5 years for this, so apply+ping with any questions!
🎉 @NSF renewed the EngageAI Institute for 5 more years and $20M. UNC CS researchers, led by Mohit Bansal (@mohitban47) will run the institute's core AI research: the world modeling tech behind story-based learning tools for K-12 science classrooms. unc.edu/posts/2026/09/14/ai-…
@unc

Han Wang retweeted

Happy to share that MINTEval is accepted to #NeurIPS2026! 🥳
How well do LLM agents and memory systems handle long-horizon, continually changing environments (e.g., Wikipedia pages, Git repos)? We find they struggle to track changes, recall precise details, and combine information across interfering updates, mainly due to limitations in retrieval and memory construction. Models confuse old and new information, memory systems tend to insert redundant entries, and retrieval often fails to recover the right information.
Details 👇

LLM agents & memory systems operate in continuously updated environments (Git repos, evolving docs). They must process long contexts, recover earlier information, and reason over many updates that create interference between old and new information. How well do they handle this?
We introduce MINTEval:
✅ Frequent context changes & interference (avg. 86 updates)
✅ 5 challenging question types, including long-range lookback & reasoning over multiple targets distributed across context
✅ 4 realistic domains: state tracking, multi-turn dialogue, Wikipedia revisions, GitHub commits
✅ Avg. 138.8k tokens per instance (up to 1.8M)
✅ Human verification on generated QAs = 95.6%
📊 Across 7 representative systems, MINTEval remains difficult, showing an avg. acc of 27.9%, and the best system reaches only 33.4%.
🔎 Our analysis shows:
• Memory construction failures cause a 41.7% drop
• Memory agents are highly sensitive to design choices
• Memory systems have a strong bias toward insertion operations (76.8%) over deletion/update

Han Wang retweeted

Thrilled to announce that PhyMotion has been accepted to #NeurIPS2026! 🎉
PhyMotion brings 3D physics into the reward loop for human video generation. Instead of judging motion only from pixels or VLM features, we reconstruct human motion in 3D and evaluate its kinematic plausibility, contact & balance consistency, and dynamic feasibility through physics-based simulation. Using PhyMotion for RL post-training substantially improves the physical realism of generated human motion.
For the updated version, we also added extensive new analyses on robustness to 3D reconstruction errors and severe body distortions, terrain-aware evaluation on stairs, potential RL reward hacking/motion suppression, and challenging qualitative cases including multi-person interaction, occlusion, camera motion, and non-flat terrain.
Updated paper + code/model/data + lots of new video demos coming soon.
See you in Atlanta! 🚀
Details 👇
phy-motion.github.io/

🚨 Excited to introduce PhyMotion🤸: Structured 3D Motion Reward for Physics-Grounded Human Video Generation!
❌ Existing 2D video rewards misleadingly assign high scores to videos with floating feet, self-penetrating limbs, and physics-violating motions.
✅ PhyMotion lifts generated videos into 3D, grounds them in a physics simulator, and scores motion along kinematic / contact / dynamic feasibility.
➡️ RL post-training with PhyMotion improves 1.3B model to match 14B models performance in human prefence.
🧵(1/n)👇

Han Wang retweeted
Honored to receive the Outstanding Faculty Mentor Award from the UNC Office of Postdoctoral Affairs, Provost, and Vice Chancellor for Research! 🙏
This one is especially meaningful because mentoring is very close to my heart -- I strongly believe it is one of the main reasons we are in this job, and it is our humble contribution in giving back to the community and helping create the next generation of mentors (students/postdocs/junior faculty, not just in our own lab/department but more broadly across other universities+countries) -- thanks to all my amazing mentees (it's a pleasure and privilege to mentor you) 🤗 💙

🎉 Excited to share our #EMNLP2026 work on diagnosing/tracing citation errors in deep research systems (which agent is actually to blame?)
We find that information gets corrupted as it passes between agents like a game of telephone, and our method traces each error back to the responsible agent. Surprisingly, the orchestrator causes most final-report errors despite having one of the lowest agent-level error rates. Even a one-sentence prompt fix raises citation recall by 5%!
More details in the thread below ⬇️

In deep research reports, many sentences aren't supported by their citations: recall is 58.7% in NVIDIA AI-Q and 7.1% in TrajectoryKit.
Our #EMNLP2026 paper (main conf) proposes an algorithm that traces each error to the agent that introduced it, and identifies the error type.

Han Wang retweeted

In deep research reports, many sentences aren't supported by their citations: recall is 58.7% in NVIDIA AI-Q and 7.1% in TrajectoryKit.
Our #EMNLP2026 paper (main conf) proposes an algorithm that traces each error to the agent that introduced it, and identifies the error type.
Han Wang retweeted
Thanks for the kind words, glad you enjoyed the talk+discussions 🙏 The pleasure was also mine, Amrit Singh Bedi, Mubarak Shah + everyone, to visit the UCF Institute of Artificial Intelligence (IAI) for the Distinguished Lecture Series, and talk about important and timely AI challenges in trustworthy+safe collaboration, world discovery, and long-term memory planning, across diverse domains & modalities & real-world applications (e.g., early medical diagnosis and classroom education engagement)!
Had several impressive discussions with the high-energy dean, chairs, faculty, students et al.; definitely check them out if you are applying -- thanks again for the hospitality everyone 🙂

It was a pleasure hosting Prof. Mohit Bansal (@mohitban47) at UCF’s Institute of Artificial Intelligence! (@UCFIAI)
Thank you, Prof. Bansal, for the inspiring talk, great insightful discussions, and for spending time with our faculty and students. Really enjoyed having you at UCF!
Grateful to the team at UCF IAI for making it possible
#UCF #ArtificialIntelligence #AI #MachineLearning #NLP #MultimodalAI #DistinguishedSpeaker

Han Wang retweeted
Thanks for the kind invitation to the inaugural UCF AI Institute's Distinguished Lecture, Amrit+Mubarak et al. -- looking forward to meeting the awesome faculty+students! 🙂
Will discuss 3 important AI challenges: Trustworthy Collaboration, World Discovery, Long-Horizon Memory Planning (across diverse domains & modalities, and real-world applications such as early medical diagnosis and classroom education engagement).
Feel free to join/stop by (virtual option also available)! 👇👇

🚀UCF IAI Distinguished Speaker Series
We’re thrilled to welcome Prof. @mohitban47 @UNC as our inaugural speaker!
🎙️ AI Challenges: Trustworthy Collaboration, World Discovery & Long-Horizon Memory
📅 Sept. 16, 2026
⏰ 11 AM
📍 SPRK 101 @UCF + Zoom
#AI #AgenticAI #TrustworthyAI

Han Wang retweeted
Landed in San Diego for #ACL2026 yesterday, with a pretty nice room view! 🏖️🌊
I will be at these 2 locations for keynotes today if you want to chat 👇
-- “Unifying Video and Audio for Multimodal Understanding and Generation”
23rd International Conference on Spoken Language Translation (@iwslt)
9.40-10.30am (iwslt.org/2026/)
-- “Long-Horizon Video Reasoning and Generation”
4th ACL Workshop on Advances in Language and Vision Research (#ALVR2026)
2.10-2.50pm (alvr-workshop.github.io/)


👋 Looking forward to attending #ACL2026 (in-person in San Diego) and #ICML2026 (probably virtually) for these presentations/workshop keynotes & meeting everyone (also, I'll be in the Bay Area beforehand, for a keynote at the Apple Reasoning and Planning Workshop)!
Feel free to ping if you want to meet up in Bay/SD (I also have July1 partly free in SJ/SF, and several days in SD), and discuss research, life, etc. (we're also hiring at all levels: phd, postdoc, faculty)! 🙂
PS. also meet several of our awesome students/postdocs/alumni attending these 2 conferences to present these works.
👇👇

Han Wang retweeted
I’ll be attending #ICML2026 in person and is looking forward to catching up with old friends and meeting new people! I’ll be presenting:
📌 Generalized Correctness Models: Learning Calibrated and Model-Agnostic Correctness Predictors from Historical Patterns
🗓️ Jul 7, 10:30 AM–12:15 PM • Hall A #2003
📌 Multimodal Fact-Level Attribution for Verifiable Reasoning
🗓️ Jul 8, 10:30 AM–12:15 PM • Hall A #1707
📌 Can Large Language Models Keep Up? Benchmarking Online Adaptation to Continual Knowledge Streams
🗓️ CATS Workshop, Jul 10 • Room 327
I’d love to chat about memory systems, multi-agent systems, and continual learning! Feel free to reach out if you'd like to chat 😄
Han Wang retweeted
#ICML2026
-- Multimodal Fact-Level Attribution for Verifiable Reasoning
@meetdavidwan @HanWang98 @ZiyangW00 @EliasEskin @hyunji_amy_lee @mohitban47
arxiv.org/abs/2602.11509
Wed, Jul 8, 2026 • 10:30 AM – 12:15 PM KST
HALL A #170
xitter.cf/meetdavidwan/status/20…

🚀Announcing MuRGAt!
MLLMs are improving at reasoning over complex multimodal inputs, but does that translate to faithful grounding to multimodal sources (video, audio, charts, etc.)? We find that even strong MLLMs often hallucinate citations despite getting the answer correct!🤯
We introduce a benchmark for Fact-Level Multimodal Attribution featuring:
✅ High-quality Human Annotations for validation.
✅ MuRGAt-SCORE: A decomposed metric that highly correlates with human judgment.
✅ Methods to improve citations, showing that Programmatic Grounding boosts attribution.
🧵👇

Han Wang retweeted
-- Stabilizing Efficient Reasoning with Step-Level Advantage Selection
@HanWang98 , @Xiaodong_Yu_126 , @Wu_Jialian , Jiang Liu, @XimengSun1 , Zicheng Liu @AIatAMD
arxiv.org/abs/2604.24003
xitter.cf/HanWang98/status/20495…

🚨 Excited to announce SAS: Stabilizing Efficient Reasoning with Step-Level Advantage Selection is accepted to #ACL2026 Findings.
LLMs can compress reasoning during post-training with short context alone, but silently destabilize training. We propose SAS to fix it by zeroing advantages at the step level: suppressing low-confidence steps in correct rollouts + shielding high-confidence ones in failed rollouts.
✨ Result: >30% shorter reasoning traces, higher accuracy, and stable training – all from a simple zero-advantage operation at the step level.

Han Wang retweeted
👋 Looking forward to attending #ACL2026 (in-person in San Diego) and #ICML2026 (probably virtually) for these presentations/workshop keynotes & meeting everyone (also, I'll be in the Bay Area beforehand, for a keynote at the Apple Reasoning and Planning Workshop)!
Feel free to ping if you want to meet up in Bay/SD (I also have July1 partly free in SJ/SF, and several days in SD), and discuss research, life, etc. (we're also hiring at all levels: phd, postdoc, faculty)! 🙂
PS. also meet several of our awesome students/postdocs/alumni attending these 2 conferences to present these works.
👇👇
Han Wang retweeted
AI video looks incredible until something moves.
Paper towels dissolve instead of soaking up water. Balls bounce off pillows like they're on a trampoline. Gravity stops being a law and starts being a suggestion.
Physics is the thing AI video still struggles with. We introduce our #ECCV2026 paper --- Physics Question Scene Graph (PQSG), a fine-grained evaluation framework for measuring physical plausibility in text-to-video generation.
– Diagnose, not just score
Identify exactly which objects, actions, and physical interactions fail in generated videos.
– Dependency-aware evaluation
Evaluate physics only when prerequisite objects and actions are correctly generated.
– Human-aligned physical realism
Achieve a stronger correlation with human judgments than existing video evaluation metrics.