
深層学習を最適化するライブラリ DeepSpeed の情報を日本語で発信する公式アカウントです。 大規模な分散学習や推論を高速かつ簡単に実施できます。 このアカウントでは、DeepSpeedの新機能や論文などの最新情報を紹介していきます。英語Twitterアカウント: @DeepSpeedAI
Joined March 2023
- Tweets139
- Following43
- Followers1.3K
- Likes132





DeepSpeed (日本語アカウント) retweeted

DeepSpeed Office Hours: Tue Aug 25, 12pm ET
v0.19.3–0.19.5:
• Grad accum for custom & serverless (Tinker)
• AutoEP+AutoTP folding & ZeRO-3 TP inference
• Hybrid Engine for on-policy distillation
• Pinned-memory CPU/NVMe offload speedups
Join: zoom-lfx.platform.linuxfound…
DeepSpeed (日本語アカウント) retweeted

Don't miss @DeepSpeedAI virtual office hours on May 26 at 12:00 PM America/New_York to ask questions of @toh_tana member of DeepSpeed TSC & get the latest recent key updates, including AutoSP (sequence parallel), AutoEP (expert parallel), and AutoTP (tensor parallel).

DeepSpeed (日本語アカウント) retweeted

Good news! Ulysses Sequence Parallelism from the Snowflake AI Research and the Deepspeed teams has been integrated into @huggingface Trainer, Accelerate and TRL
For extensive details please see this writeup:
huggingface.co/blog/ulysses-…
Thanks a lot to @krasul for helping make it happen. Also the others in the HF team who helped with integration.

DeepSpeed (日本語アカウント) retweeted
Zhipeng (Jason) Wang, PhD (@PKUWZP) explains how @DeepSpeedAI supports ML training research and why joining PyTorch Foundation benefits researchers and developers working on AI training workloads.
🔗youtu.be/67719mlOSp0 #PyTorch
#DeepSpeed #OpenSourceAI #AIInfrastructure
DeepSpeed (日本語アカウント) retweeted
UIUC, AnyScale, and Snowflake significantly enhanced LLM offloading for the Superchip era!

🚀 SuperOffload: Unleashing the Power of Large-Scale LLM Training on Superchips
Superchips like the NVIDIA GH200 offer tightly coupled GPU-CPU architectures for AI workloads. But most existing offloading techniques were designed for traditional PCIe-based systems. Are we truly tapping into their full potential for LLM training?
🎯 SuperOffload is our answer to this challenge, a new DeepSpeed component rethinking offloading from the ground up, specially designed for LLM training on Superchips.
✨ SuperOffload is exact -- no approximation, no heuristics, and no changes to your training algorithm. Just faster, larger model with longer sequence training using the same code, which are made possible by system-level optimizations exploiting Superchip architecture.
🧪 SuperOffload allows you:
- Finetune models like GPT-OSS-20B, Qwen3-14B, and Phi-4 on a single GH200
- Up to 4X faster speed than previous approaches like ZeRO-Offload
- Effortlessly scales to:
-- Qwen3-30B-A3B and Seed-OSS-36B on 2 x GH200s
-- LLaMA2-70B on 4 x GH200s
-- 1M sequence length on 8x GH200 with 55% MFU
- Easy-to-use: Fully integrated and open-sourced in DeepSpeed. Just a few lines of code to enable!
📚 Read more through official PyTorch blog: pytorch.org/blog/superoffloa…
🧠 For more technical details, please read our technical report: arxiv.org/abs/2509.21271
🛠️ SuperOffload is fully open-sourced through DeepSpeed. Try it now: github.com/deepspeedai/DeepS…
📄 SuperOffload has been accepted to ASPLOS 2026! Kudos to Xinyu Lian (@Alexlian0806), Masahiro Tanaka (@toh_tana), and Olatunji Ruwase.
🎤 Featured at PyTorch Conference 2025
SuperOffload will be featured in the DeepSpeed & vLLM keynote at this year's PyTorch Conference in San Francisco.
🔥Come see how we're rethinking large-scale LLM training for the Superchip era: events.linuxfoundation.org/p…

DeepSpeed (日本語アカウント) retweeted

📢 Yesterday at USENIX ATC 2025, Xinyu Lian from UIUC SSAIL Lab presented our paper on Universal Checkpointing (UCP). UCP is a new distributed checkpointing system designed for today's large-scale DNN training, where models often use complex forms of parallelism, including data, tensor, pipeline, and expert parallelism.
Existing checkpointing systems struggle in this setting because they are tightly coupled to specific training strategies (e.g., ZeRO-style data parallelism or 3D model parallelism), which break down when the training configs need to dynamically reconfigure over time. This makes it difficult to have resilient and fault-tolerant training.
UCP solves this by decoupling distributed checkpointing from parallelism strategies. Our design introduces a unified checkpoint abstraction -- atomic checkpoint, and a full pattern matching-based transformation pipeline, which enables scalable and low-overhead checkpointing with reconfigurable parallelism across arbitrary model sharding strategies.
We show that UCP supports state-of-the-art models trained with hybrid 3D/4D parallelism (ZeRO, TP, PP, SP) while incurring less than 0.001% overhead of the total training time.
UCP is fully open-sourced in DeepSpeed. It has been adopted by Microsoft, BigScience, UC Berkeley and others for large-scale model pre-training and fine-tuning, including Phi-3.5-MoE (42B), BLOOM (176B), and many more. It also has been selected for presentation at PyTorch Day 2025 and FMS 2025(the Future of Memory and Storage).
Big thanks to the amazing collaborators from Microsoft and Snowflake: @samadejacobs , @LevKurilenko, @MasahiroTanaka, @StasBekman , and @TunjiRuwase.
🔗 Project: lnkd.in/gG6j4vJe
📄 Paper: lnkd.in/gUiC5kcR
💻 Code: lnkd.in/g6uS29nH
📚 Tutorial: lnkd.in/gi_zWSWh
#ATC2025 #LLM #Checkpointing #SystemsForML #DeepLearning #DistributedTraining #UIUC #DeepSpeed

DeepSpeed (日本語アカウント) retweeted
PyTorch Day France marked the launch of a global PyTorch Day series—and the announcement of a major milestone: PyTorch Foundation is now an umbrella foundation. First new projects: @vllm_project + @DeepSpeedAI.
Next Stop: PyTorch Day China, June 7 🇨🇳 hubs.la/Q03lJvHh0
#PyTorch #OpenSourceAI #vLLM #DeepSpeed


DeepSpeed (日本語アカウント) retweeted
PyTorch Foundation has expanded into an umbrella foundation. @vllm_project and @DeepSpeedAI have been accepted as hosted projects, advancing community-driven AI across the full lifecycle.
Supporting quotes provided by the following members: @AMD, @Arm, @AWS, @Google, @Huawei, @huggingface, @IBM, @Intel, @LightningAI, @Meta, @NVIDIA, and @Snowflake.
🔗💡 Read the full announcement: hubs.la/Q03lmJNH0
#PyTorchFoundation #PyTorch #OpenSourceAI #vLLM #DeepSpeed

DeepSpeed (日本語アカウント) retweeted
This is pretty neat. They insert into torch.compile and insert some profile-guided optimizations as well as a bunch of other specific optimizations like offloading.
Since torch.compile is all in Python all their compiler passes are fairly accessible too!
github.com/deepspeedai/DeepS…

Introducing 🚀DeepCompile🚀: compiler-based distributed training optimizations.
- Automatic parallelization & profile-guided optimizations
- Enable ZeRO1, ZeRO3, Offloading, etc. via compiler passes
- 1.2X-7X speedups over manual ZeRO1/ZeRO3/Offloading
tinyurl.com/8cys28xk

DeepSpeed (日本語アカウント) retweeted

🚀 Excited to introduce DeepSpeed, a deep learning optimization library from @Microsoft! It simplifies distributed training and inference, making AI scaling more efficient and cost-effective.
Learn more 👉 hubs.la/Q0351DJC0
#DeepSpeed #AI #OpenSource #LFAIData

DeepSpeed (日本語アカウント) retweeted
Microsoft Research congratulates Yasuyuki Matsushita on being named a 2025 IEEE Fellow for his outstanding contributions to photometric 3D modeling and computational photography. msft.it/6018oINMG

ALT A graphic with a blue and pink geometric background. The text on the left side reads: Yasuyuki Matsushita named IEEE Fellow.
DeepSpeed (日本語アカウント) retweeted
【 Microsoft Research Asia - Tokyo を設立】
アジア太平洋地域における人工知能研究とイノベーションの推進を強化するため、東京に新たな研究拠点である「Microsoft Research Asia-Tokyo(マイクロソフト リサーチ アジア東京)」を設立したことを発表します。
msft.it/6018WqGNw

DeepSpeed (日本語アカウント) retweeted

Microsoft releases GRIN😁 MoE
GRadient-INformed MoE
demo: huggingface.co/spaces/GRIN-M…
model: huggingface.co/microsoft/GRI…
github: github.com/microsoft/GRIN-Mo…
With only 6.6B activate parameters, GRIN MoE achieves exceptionally good performance across a diverse set of tasks, particularly in coding and mathematics tasks.

DeepSpeed (日本語アカウント) retweeted

One more JD: we are hiring at Tokyo Lab!
jobs.careers.microsoft.com/g…
DeepSpeed (日本語アカウント) retweeted
Keep hiring for our new Tokyo lab...
jobs.careers.microsoft.com/g…
DeepSpeed (日本語アカウント) retweeted

MS Phi-3.5 のリリースブログ
Phi-3.5-mini、Phi-3.5-vision、Phi-3.5-MoE の 3 つ。多言語対応、128k Context Length、複数フレーム理解、16 Experts / 6.6B Active Parameters。安全性にも焦点。Azure AI Studio 経由で Guidance を用いて出力制御も。多言語、知識系タスクには RAG の使用を推奨。

Phi-3.5について、公式のリリースブログが掲載されました!
techcommunity.microsoft.com/…

DeepSpeed (日本語アカウント) retweeted
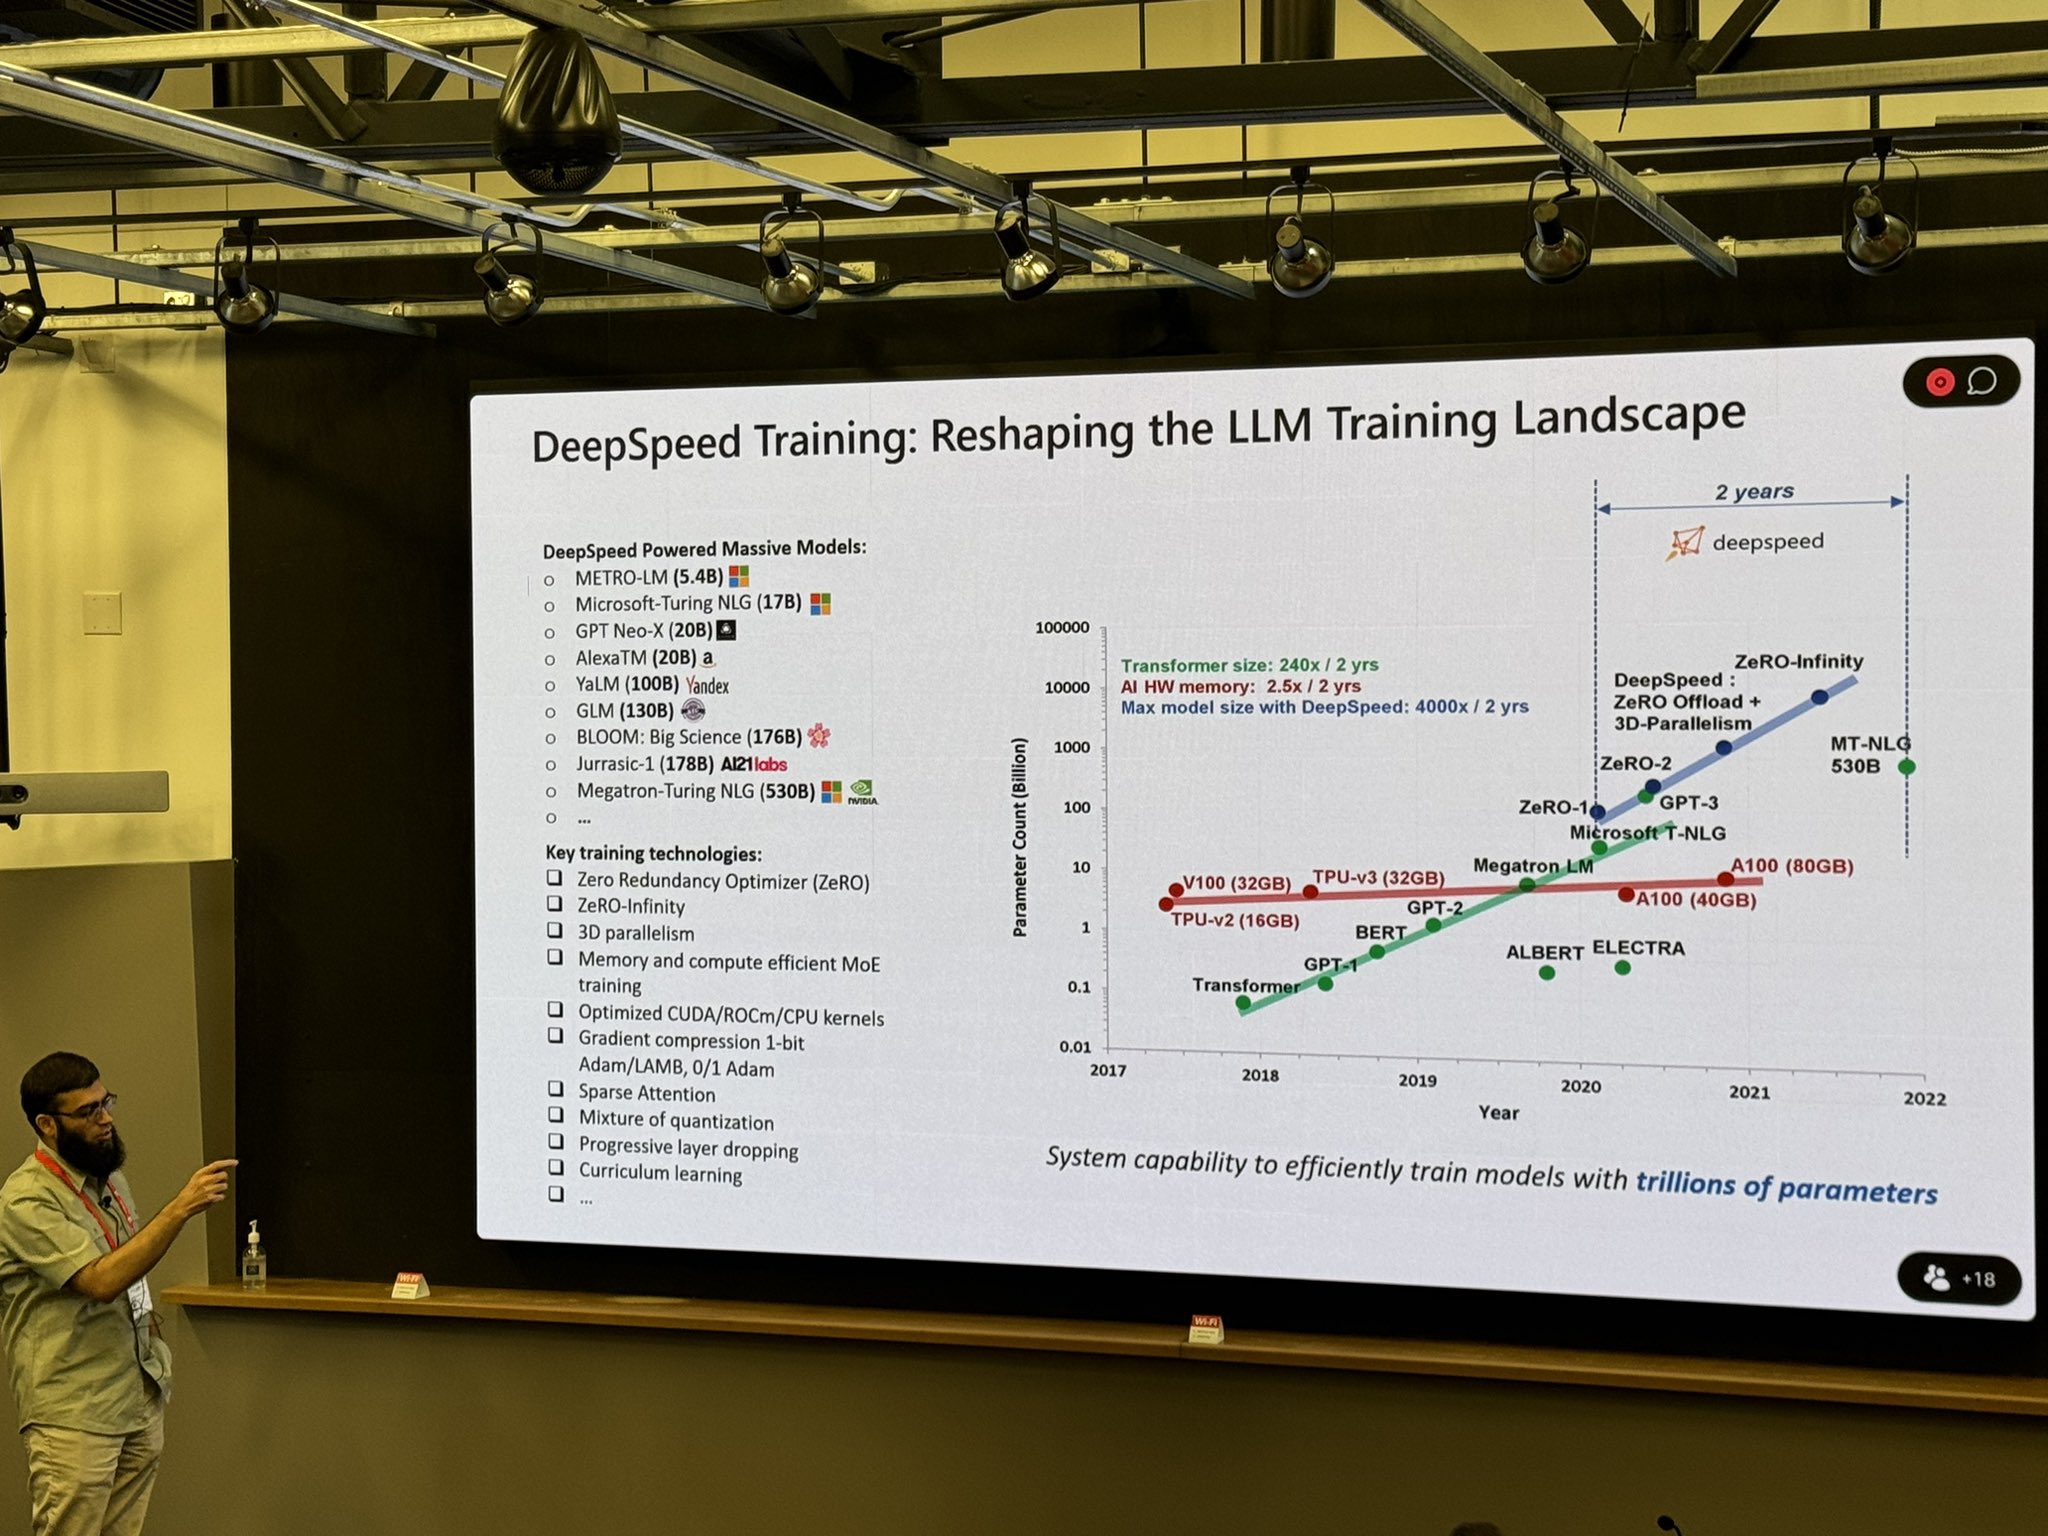
Great to see the amazing DeepSpeed optimizations from @Guanhua_Wang_, Heyang Qin, @toh_tana, @QuentinAnthon15, and @samadejacobs presented by @ammar_awan at MUG '24.

Dr. Ammar Ahmad Awan from Microsoft DeepSpeed giving a presentation at MUG '24 over Trillion-parameter LLMs and optimization with MVAPICH.
@OSUengineering @Microsoft
@OhTechCo @mvapich
@MSFTDeepSpeed
@MSFTDeepSpeedJP #MUG24 #MPI #AI #LLM #DeepSpeed



DeepSpeed (日本語アカウント) retweeted

Phi goes MoE! @Microsoft just released Phi-3.5-MoE a 42B parameter MoE built upon datasets used for Phi-3. Phi-3.5 MoE outperforms bigger models in reasoning capability and is only behind GPT-4o-mini. 👀
TL;DR
🧮 42B parameters with 6.6B activated during generation
👨🏫 16 experts with 2 active in generation
🪟 Instruct model with 128k context
🚀 Outperforms Llama 3 8b, Gemma 2 9B across benchmarks
🥈 Closely behind GPT-4o mini, but outperforms Gemini 1.5 Flash
🌎 Multilingual support (unclear which languages)
📜 MIT License
📊 Trained on 4.9 trillion tokens (including 10% multilingual)
🤗 Available on @huggingface
Model: huggingface.co/microsoft/Phi…

DeepSpeed (日本語アカウント) retweeted

We released phi 3.5: mini+MoE+vision
A better mini model with multilingual support: huggingface.co/microsoft/Phi…
A new MoE model:huggingface.co/microsoft/Phi…
A new vision model supporting multiple images: huggingface.co/microsoft/Phi…

DeepSpeed (日本語アカウント) retweeted
Announcing that DeepSpeed now runs natively on Windows. This exciting combination unlocks DeepSpeed optimizations to Windows users and empowers more people and organizations with AI innovations.
- HF Inference & Finetuning
- LoRA
- CPU Offload
Blog: shorturl.at/a7TF8
