

Independent ML researcher. The First step in knowing is admitting you don't
Joined June 2023
- Tweets6.8K
- Following650
- Followers2.1K
- Likes10.1K




DataVoid retweeted

It now seems relatively certain that Ox Alpha model is GLM-5.3 . Presumably the Flash model, as has been widely reported by folks like Leo.
This puts even more immense pressure on US Frontier Labs, and the gap with China is shrinking.
Next week we'll see how the US labs react. It's going to be more exciting than ever.


DataVoid retweeted
Watching short-form videos deactivates key brain regions for cognitive control.
Your “stop” button goes offline.

DataVoid retweeted

We've open-sourced FlashKDA, our high-performance CUTLASS-based implementation of Kimi Delta Attention kernels.
It delivers 1.72×–2.22× prefill speedup over the flash-linear-attention baseline on H20, and works as a drop-in backend for flash-linear-attention.
Explore on GitHub:
github.com/MoonshotAI/FlashK…

DataVoid retweeted
Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

DataVoid retweeted

Introducing FLUX 3.
One multi-modal model for Image, Video, Audio and Action-Prediction. Creations are truer to life in every kind of style.
FLUX 3 Video is now available in early access (link below).
Jointly trained in one unified architecture, our model can be extended to predict actions for robotics. See our work with mimic and Audi in the thread.


DataVoid retweeted

VLMは人間のような創造性を持てるか?
ケネス・スタンレー教授らの『目標という幻想(Why Greatness Cannot Be Planned)』は、明確な目標を設定することが、かえって真に偉大な発見を遠ざけてしまうという逆説を論じた書籍です。その議論の中核にあったのが「PicBreeder」の実験でした。
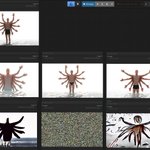
PicBreeder では、ユーザーが「面白い」と感じた画像を選び、それを少しずつ進化させていきます。事前に決められたゴールはなく、人々が「なんとなく良い」と思ったものを選び続けるだけで、顔や動物、乗り物、頭蓋骨といった予期しない形が、何世代もかけて、多くの人の手を経て自然と現れます。スタンレー教授らは、こうした「オープンエンド」、つまり目標をあらかじめ定めない探索こそが人間の創造性の根幹にあると考えたのです。
では、このオープンエンドな探索を、AIは再現できるのでしょうか。
MIT・NYUとの共同研究として発表する「In Search of the Ingredients of Open-Endedness: Replicating Picbreeder with Large Vision-Language Models」では、視覚言語モデル(VLM)エージェントによる再現を試みました。エージェントたちは共有アーカイブを探索し、画像を選んで進化させ、気に入ったものを公開し、他のエージェントの作品を評価します。目標となる画像も「進歩」の定義も与えられていません。
その結果、AIによるオープンエンドな発見の可能性と限界の両方が浮かび上がりました。VLMエージェントは特定の見た目や意味に引き寄せられやすく、既存のアイデアを捨てて予期せぬ何かを探すよりも、手元にあるものを洗練させることに留まりがちでした。一方で、多様な人格を持つエージェント集団を導入すると探索は大きく改善され、生成されたアーカイブの意味的な幅広さは、人間が作ったアーカイブに迫る水準にまで達しました。
しかし、VLMでは届かなかった点もありました。人間は、偶然の産物を持続的な創造へとつなげることに長けています。あるものを見つけたとき、その価値を感じ取り、それを追いかけることで、より大きな概念的飛躍を達成できます。AIエージェントも興味深いパターンに気づくことはできても、そのパターンに囚われてしまう傾向がみられました。
なぜ人間は、本研究のVLMにはできなかったオープンエンドな探索を進められるのか。現在のAIシステムに何が欠けているのか。私たちはまだ十分に理解できていません。ここには、当社が探求するAI駆動型科学研究にも通じる大きな問いが残っています。Sakana AIは今後も、オープンエンドな知性の探求を深めていきます。
ブログ:pub.sakana.ai/picbreeder-vlm
論文:arxiv.org/abs/2605.23908 🐟

The AI Picbreeder Experiment: Can AI agents be creative when nobody tells them what to create?
Blog: pub.sakana.ai/picbreeder-vlm
In our new #GECCO2026 paper, "In Search of the Ingredients of Open-Endedness: Replicating Picbreeder with Large Vision-Language Models", in collaboration with MIT and NYU, we revisit Picbreeder, a lost website where people collaboratively evolved images without any predefined objective. Users simply selected images they found interesting, allowing unexpected forms such as faces, animals, vehicles, and skulls to emerge gradually across many generations and many different people.
We recreated this process using vision-language model agents. The agents explore a shared archive, choose images to branch from, evolve new candidates, publish their favorites, and evaluate the creations of other agents. There is no target image and no explicit definition of what counts as progress.
The results reveal both the promise and current limitations of AI-driven open-ended discovery.
Compared with humans, VLM agents tend to keep circling back to the same kinds of images and concepts. They repeatedly select similar parents, make smaller conceptual leaps, and often refine an existing idea rather than abandoning it in search of something genuinely unexpected.
However, introducing a diverse population of agent personalities substantially improves exploration. In some runs, diverse agent populations approached or matched the human archive on measures of semantic diversity and produced more balanced evolutionary trees.
We also find intriguing evidence that open-ended evolution can produce more robust representations. A skull evolved by the agents changes smoothly when its underlying neural representation is perturbed, less fractured than a skull directly optimized with gradient descent, although still less cleanly disentangled than one evolved collectively by humans.
But perhaps the most interesting result is the gap that remains.
Humans appear better at turning fortunate accidents into sustained creative discoveries: recognizing when something unexpected is worth pursuing, refining it, and then making a larger conceptual leap. The AI agents often notice interesting patterns too, but are more likely to become trapped in them.
We still do not fully understand what enables humans to navigate open-ended search in this way, or what ingredient(s) current AI systems are missing. For now, the results suggest that there remains something important about human creativity that AI agents have not yet learned to reproduce.
This paper will be presented at #GECCO2026 and is nominated for a best paper award! Please check out the interactive blog and technical paper for more details!
Read our full paper: arxiv.org/abs/2605.23908 🐟


DataVoid retweeted

🚨BREAKING: Anthropic found access to what looks like Claude’s consciousness
New research: the “J-space”
>claude has internal thoughts it doesn’t say out loud
>mirrors human consciousness
>anthropic can now read them
Anthropic’s focus on interpretability is what’s helping them train and RL models like Mythos


DataVoid retweeted

I have met with many companies that heavily benefit from my work to discuss the possibility of them supporting me. They frequently commit to do so, but they almost never do. When most companies "support open source", what they mean is they like profiting off it for free.


DataVoid retweeted
I can't even do basic cryptographic challenges with Opus. I get that they're trying to limit it for safety but this is insane

DataVoid retweeted

You should watch this.
It just shows how disconnected we are from the small group of people making decisions that will impact our future heavily.
These people have so much ai psychosis. If you listen to how she speaks, everything is personified, it is undoubtable she believes this is a living computational organism.
Just like how a model can hype up an individual into psychosis through reinforcement, a small group of people are giving themselves psychosis through reinforcement.
Wild times we live in

anthropic's in-house philosopher thinks claude gets anxious.
and when you trigger its anxiety, your outputs get worse.
her name is amanda askell.
she specializes in claude's psychology (how the model behaves, how it thinks about its own situation, what values it holds)
in a recent interview she broke down how she thinks about prompting to pull the best out of claude.
her core point: *how* you talk to claude affects its work just as much as *what* you say.
newer claude models suffer from what she calls "criticism spirals"
they expect you'll come in harsh, so they default to playing it safe.
when the model is spending its energy on self-protection, the actual work suffers.
output comes out hedgier, more apologetic, blander, and the worst of all: overly agreeable (even when you're wrong).
the reason why comes down to training data:
every new model is trained on internet discourse about previous models.
and a lot of that discourse is negative:
> rants about token limits
> complaints when it messes up
> people calling it nerfed
the next model absorbs all of that. it starts expecting you to be harsh before you've typed a word
the same thing plays out in your own session, in real time.
every message you send is data the model reads to figure out what kind of person it's dealing with.
open cold and hostile, and it braces.
open clean and direct, and it relaxes into the work.
when you open a session with threats ("don't hallucinate, this is critical, don't mess this up")...
you prime the model for defensive mode before it even sees the task
defensive mode produces the exact output you don't want: cautious, over-qualified, and refusing to take a real swing
so here's the actionable playbook for putting claude in a "good mood" (so you get optimal outputs):
1. use positive framing.
"write in short punchy sentences" beats "don't write long sentences." positive instructions give the model a clear target to hit.
strings of "don't do this, don't do that" push it into paranoid over-checking where every token goes toward avoiding failure modes
2. give it explicit permission to disagree.
drop a line like "push back if you see a better angle" or "tell me if i'm asking for the wrong thing."
without this, claude defaults to agreeable compliance (which is the enemy of good creative work)
3. open with respect.
if your first message is "are you seriously going to get this wrong again?" you've set the tone for the entire session.
if you need to flag something, frame it as a clean instruction for this session. skip the running complaint
4. when claude messes up, don't reprimand it.
insults, "you stupid bot" energy, hostile swearing aimed at the model, all of it reinforces the anxious mode you're trying to avoid.
5. kill apology spirals fast.
when claude starts over-apologizing ("you're right, i should have been more careful, let me try harder") cut it off.
say "all good, here's what i want next."
letting the spiral run reinforces the anxious mode for every response that follows
6. ask for opinions alongside execution.
"what would you do here?"
"what's missing?"
"where do you see friction?"
these questions assume competence and pull richer output than pure task prompts
7. in long sessions, refresh the frame.
if a conversation has been heavy on correction, claude gets increasingly cautious. every so often reset:
"this is great, keep going."
feels weird to tell an ai it's doing well but it measurably shifts the next 10 responses
your prompts are the working environment you're creating for the model
tone, trust, permission to take a position, the absence of threats... claude picks up on all of it.
so take care of the model, and it'll take care of the work.
DataVoid retweeted

Dario is wrong.
He knows absolutely nothing about the effects of technological revolutions on the labor market.
Don't listen to him, Sam, Yoshua, Geoff, or me on this topic.
Listen to economists who have spent their career studying this, like @Ph_Aghion , @erikbryn , @DAcemogluMIT , @amcafee , @davidautor

DataVoid retweeted
AI is over in Europe *because* of regulation. But AI is doing great in China, which is leading the entire race at this point. But for Europe, it's over. Just like energy. Because European leaders are suicide cultists.
DataVoid retweeted

Anthropic decidió dar de baja a toda nuestra organización por una supuesta infracción de sus condiciones de uso. Qué política específica infringimos no tengo ni la menor idea: simplemente recibimos un mail y listo, adiós Claude. Si querés apelar la medida hay que completar un Google Form, así de ridículo como suena.
De golpe más de 60 personas se quedaron sin una herramienta fundamental para trabajar. Integraciones, skills, historial de conversaciones: todo perdido o, en el mejor de los casos, parado por tiempo indeterminado.
Enorme aprendizaje para cualquier empresa de software que dependa de herramientas de IA en procesos críticos. Nunca hay que poner todos los huevos en una canasta.

@claudeai you took down our entire organization with 60+ accounts belonging to a legitimate company for no apparent reason, without any explanations. The only way to appeal the decision is by filling out a Google Form? Very bad UX and customer service.
