






🦉DVC retweeted

What does the data architecture for production AI agents actually look like?
Join MinIO and @lakeFS to dive into agent memory, data isolation, reproducibility, and governance + how to build those capabilities into the infrastructure layer without slowing development down.
📅 10/22 | 12 PM ET
🔗: bit.ly/3WbJB15

🦉DVC retweeted

Every ML failure I have debugged traces back to unversioned data.
Code has Git.
ML data has DVC, lakeFS, Delta Lake, and Iceberg.
Most teams use none of them.
Here is the data versioning landscape and how to pick,
grouped into 3 capability areas:
𝐖𝐡𝐲 𝐕𝐞𝐫𝐬𝐢𝐨𝐧 𝐘𝐨𝐮𝐫 𝐃𝐚𝐭𝐚
① Reproduce a model months later without guessing
② Debug regressions: was it the code or the data
③ A/B test with different data snapshots
④ Roll back bad training data before it hits production
𝐓𝐨𝐨𝐥 𝐂𝐨𝐦𝐩𝐚𝐫𝐢𝐬𝐨𝐧
⑤ DVC: Git-like, works with any storage, best for file-level ML datasets
⑥ LakeFS: Git for object storage, branch/merge on S3, best for lakehouse workflows
⑦ Delta Lake: table-level time travel + versioning, best for Databricks/lakehouse
⑧ Iceberg: open table format with snapshots, best for multi-engine environments
𝐖𝐡𝐢𝐜𝐡 𝐭𝐨 𝐏𝐢𝐜𝐤
⑨ File-based ML datasets (images, audio, docs): DVC
⑩ Lakehouse-native workflows on S3: LakeFS or Iceberg
⑪ Databricks or Delta-committed shops: Delta Lake native
⑫ Snowflake shops adopting open formats: Iceberg via Polaris
Unversioned data is the #1 hidden cause of "the model was working last week."
Real senior data engineers make data versioning the default,
Not an afterthought triggered by a production incident.
The gap between "our model is broken and we do not know why"
And "we rolled back to yesterday's data snapshot in 10 minutes"
Is where data versioning earns its keep.
Which tool are you using today? 👇
Follow for more.
If you are looking for a Data Engineering Roadmap, Resume Template or Interview questions with answers do check out my Product — lnkd.in/gpcJ5rxj
hashtag#DataEngineering hashtag#ML hashtag#MLOps hashtag#Reproducibility
🦉DVC retweeted
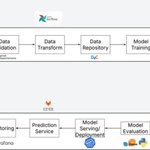
DevOps to MLOPS 🚀
How is MLOPS different from usual DevOps workflows?
MLOps is different from the usual DevOps workflows, just like machine learning is different from traditional software development.
For example,
In MLOps, you need to track three components: code, data, and models
While in DevOps, you only track code.
Additionally, MLOps introduces the following.
- 𝗗𝗮𝘁𝗮 𝘃𝗲𝗿𝘀𝗶𝗼𝗻𝗶𝗻𝗴: To track changes in datasets using tools like DVC (Data Version Control) or LakeFS
- 𝗘𝘅𝗽𝗲𝗿𝗶𝗺𝗲𝗻𝘁 𝘁𝗿𝗮𝗰𝗸𝗶𝗻𝗴: To log hyperparameters, metrics, and model versions for each training run
- 𝗠𝗼𝗱𝗲𝗹 𝗿𝗲𝗴𝗶𝘀𝘁𝗿𝘆: To version and manage models separately from application artifacts
- 𝗖𝗼𝗻𝘁𝗶𝗻𝘂𝗼𝘂𝘀 𝗧𝗿𝗮𝗶𝗻𝗶𝗻𝗴 (𝗖𝗧): Beyond CI/CD, models need regular retraining as data changes
In the latest newsletter edition,
We break down everything about what MLOps means for DevOps engineers. It covers,
- What is MLOPS
- Skills Required For DevOps Engineers
- Key MLOPS Tools
- Do you need GPU-based clusters to learn MLOps?
So if you are ready to go “all in” with MLOPS, this edition is for you.
𝗥𝗲𝗮𝗱 𝗶𝘁 𝗵𝗲𝗿𝗲: newsletter.devopscube.com/p/…
Are you working on any MLOps projects right now?
Or are you planning to upskill in MLOps?
Either way, share your thoughts in the comments.
#devops #MLOPS

🦉DVC retweeted

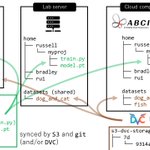
You can now use @huggingface Buckets as a @DVCorg remote.
(DVC is a "git for data" tool, i.e. version datasets & models without stuffing large files into git.)
Buckets speak S3 now → DVC points right at one: pointers in git, data in your bucket, no egress on pulls.

🦉DVC retweeted

We're co-hosting a webinar with @lakeFS to showcase how CytoReason are using @nextflowio, Seqera, and lakeFS to ship reproducible disease models as governed, versioned data products.
Register now: hubs.la/Q04lpHJk0

🦉DVC retweeted

"The manual model breaks": What happens when agents write to production data thenewstack.io/lakefs-agenti…

🦉DVC retweeted

how do you manage unstructured data? what issues, struggles do you have? I would be happy to discuss and learn!
🦉DVC retweeted
A small DataChain video on processing audio data from @huggingface with 🤗 models. We need more tools to do ETLs, analytics, governance, preparation for unstructured data at scale!
- stream files from tar or wds archives! 🤯
- enrich, prepare, version, publish datasets 🚀
- bonus! 🤗 is natively integrated like a storage provider!
🦉DVC retweeted
What is the trick to make progress bars look decent on Colab? Anyone, from the top of your head? :)

🦉DVC retweeted

@DVCorg : Git-like version control system for data, ensuring effective management of machine learning projects.
github.com/iterative/dvc




🦉DVC retweeted

After trending in Hacker News, our open-source is now trending in GitHub.
What’s next - Netflix special?
github.com/iterative/datacha…

🦉DVC retweeted

Datasets + LLMs + Pydantic = DataChain
...now with @huggingface !💛
DataChain by @DVCorg just added @huggingface support ! Create, Load, Transform HF Datasets with LLMs easily.
- Pydantic for dataset schema
- Use your own or public HF Datasets
- Run your own or public HF Models

🦉DVC retweeted
DVC is trending on Hacker News! news.ycombinator.com
Why does this always happen on weekends? 🤔
🦉DVC retweeted

Thank you to everyone who joined us for the OSPO #InnovateWeek panel on Open Source and AI last week! Special thanks to our panelists: Paige Bailey @DynamicWebPaige, Will Falcon @williamfalcon, Dmitry Petrov @FullStackML, and moderator Nhi Le @ngocnhile.

🦉DVC retweeted
California is winning over regulations 🎉
Thanks to all who helped!

Thank you Governor @GavinNewsom for vetoing SB-1047 -- your pro-innovation leadership is much appreciated!
And to the many people who've been pushing back on SB-1047, a huge thank you as well. Congratulations to all -- we won! 🎉
Looking ahead, lets keep on protecting AI open-source and innovation. We must make sure AI policy is based on science, not science fiction!
🦉DVC retweeted

Gave a talk yesterda at @UWMadison where @KyleCranmer and team are building a great OSS center to get more students building opensource ⚡️ ⚡️
Bonus ⚡️, got to hang with @DynamicWebPaige from the Gemini team, Dmitry from DVC and @alpha_fund


🦉DVC retweeted

💻 Really enjoyed talking about open-source and its impact on AI last night at the Data Science Institute in @UWMadison!
Panel session and lightning demos with @williamfalcon (@LightningAI) and Dmitry Petrov (@iterativeai), hosted by @KyleCranmer and Nhi Lê (Alpha Intelligence Capital).
The conversations immediately afterward with students and faculty were inspiring – universities need more startup incubators. 🚀 – at Wisconsin, USA


Finally got to meet my fellow @RiceUniversity 🦉alum and open source enthusiast @DynamicWebPaige! The panel on open source, AI, and innovation was awesome! @datascience_uw
