





🦉DVC retweeted

What does the data architecture for production AI agents actually look like?
Join MinIO and @lakeFS to dive into agent memory, data isolation, reproducibility, and governance + how to build those capabilities into the infrastructure layer without slowing development down.
📅 10/22 | 12 PM ET
🔗: bit.ly/3WbJB15

Phat Vo from @fintech24h_com treats data lineage as AI security infrastructure: DVC keeps an audit trail of what went into every training run, alongside layered defenses and continuous monitoring. Provenance first 💪🏼
hubs.la/Q04z1rMS0

Evgeny Levashov's guide to ML storage on S3: naming schemes for datasets, features and model weights, DVC for dataset versioning, MLflow for artifacts, Feast for features, and lifecycle rules to control costs ✨
hubs.la/Q04z1pXk0

Tomorrow, 11:30 AM ET: AWS's own solutions architects walk through the DVC + SageMaker AI + MLflow lineage pattern from their blog, live.
📣Last call: hubs.la/Q04wzs_d0

🎯 DevOps, MLOps, DataOps, AIOps, AgentOps... confused?
Rabiya Abbasi's beginner's guide covers ALL the 'Ops' with tool recommendations for each discipline + a decision-making framework.
Your 2026 roadmap starts here!
hubs.la/Q04wyVcB0

How do you prove a specific record was excluded from training after an opt-out? Next week AWS's own solutions architects show the pattern live 👉🏼 DVC + SageMaker AI + MLflow. Sept 22.
Register here: hubs.la/Q04wzjXr0

Nothing screams "we don't have a data version control tool" quite like a shared folder full of final_final_v3_actually_final.csv files.

🦉DVC retweeted

Every ML failure I have debugged traces back to unversioned data.
Code has Git.
ML data has DVC, lakeFS, Delta Lake, and Iceberg.
Most teams use none of them.
Here is the data versioning landscape and how to pick,
grouped into 3 capability areas:
𝐖𝐡𝐲 𝐕𝐞𝐫𝐬𝐢𝐨𝐧 𝐘𝐨𝐮𝐫 𝐃𝐚𝐭𝐚
① Reproduce a model months later without guessing
② Debug regressions: was it the code or the data
③ A/B test with different data snapshots
④ Roll back bad training data before it hits production
𝐓𝐨𝐨𝐥 𝐂𝐨𝐦𝐩𝐚𝐫𝐢𝐬𝐨𝐧
⑤ DVC: Git-like, works with any storage, best for file-level ML datasets
⑥ LakeFS: Git for object storage, branch/merge on S3, best for lakehouse workflows
⑦ Delta Lake: table-level time travel + versioning, best for Databricks/lakehouse
⑧ Iceberg: open table format with snapshots, best for multi-engine environments
𝐖𝐡𝐢𝐜𝐡 𝐭𝐨 𝐏𝐢𝐜𝐤
⑨ File-based ML datasets (images, audio, docs): DVC
⑩ Lakehouse-native workflows on S3: LakeFS or Iceberg
⑪ Databricks or Delta-committed shops: Delta Lake native
⑫ Snowflake shops adopting open formats: Iceberg via Polaris
Unversioned data is the #1 hidden cause of "the model was working last week."
Real senior data engineers make data versioning the default,
Not an afterthought triggered by a production incident.
The gap between "our model is broken and we do not know why"
And "we rolled back to yesterday's data snapshot in 10 minutes"
Is where data versioning earns its keep.
Which tool are you using today? 👇
Follow for more.
If you are looking for a Data Engineering Roadmap, Resume Template or Interview questions with answers do check out my Product — lnkd.in/gpcJ5rxj
hashtag#DataEngineering hashtag#ML hashtag#MLOps hashtag#Reproducibility
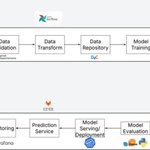
Sysdai builds a production data pipeline end-to-end: Kafka streaming, Airflow batch orchestration, Great Expectations validation, and DVC for dataset versioning and lineage. Handles Lambda and Kappa patterns, batch and streaming both. Check it out!
👉🏽 hubs.la/Q04tJY5P0

2 weeks out! AWS solutions architects walk through the SageMaker + DVC + MLflow lineage pattern from their own blog post, live. Sept 22.
Join us!
hubs.la/Q04wyX9n0

Balajee Asish Brahmandam containerizes an MLOps pipeline end to end: multi-stage training/serving containers, MLflow tracking, DVC data versioning, and GPU passthrough, all in one Compose file. A year of hard-won lessons.
👉🏽 hubs.la/Q04tMCFR0

Dr. Aleena Baby turns the classic 47-files-in-one-folder ML mess into a professional project layout: configs, src, tests, CI/CD workflows, MLflow tracking, and .dvc files for data. A one-weekend cleanup for reproducibility.
👉🏽 hubs.la/Q04tN6wj0

New research: Buhayh, McKinnie, Canel & Burke simulate 4 profile-portability scenarios across Amazon, Goodreads & MovieLens, using DVC for reproducibility. What happens to your recommender data when you switch algorithms?
👉🏽 hubs.la/Q04tKBmf0

AWS featured DVC in an official ML lineage pattern alongside SageMaker AI and MLflow.
Join the team who built it for a live walkthrough on Sept 22!
hubs.la/Q04v-GN80

New research: Madugula & Esteva de la Rosa invert the Kelly Criterion to price DeFi loan risk, with MLflow tracking and DVC + DagsHub versioning RWA data for reproducibility. A Reverse Kelly AMM for risk-adjusted lending.
👉🏽 hubs.la/Q04tMBfG0
