

Building personal AI infrastructure. Local LLMs, coding agents, open-source models. Real hardware, real constraints. Learning in public.
Maryland
Joined April 2009
- Tweets8.6K
- Following655
- Followers1.1K
- Likes7.4K


BlockedPath retweeted

The traces for my Muse Wonder Full benchmark with @VulcanBench are now live on Github.
I'm a big believer in not just sharing data and results, but also showing all the details so anyone can analyze every single result.
To me, the most interesting thing about looking at traces is seeing how different models think
I find Muse Wonder Full to actually be a very interesting model to see think because it's actually very accurate, but overthinks, causing it to use a lot more tokens, and take a lot more time than other frontier models.
To me, I don't really see this as bad, more like an opportunity to see a model before it reaches its full potential in many ways.
Lately I've been thinking of frontier models, and more specifically, the traces from these models, as a form of art, capturing a moment in time, a month or two later, these models will be completely different, but the traces will always be a piece of history.
Maybe some day we'll have the VulcanBench museum where you can look at early model traces and examine them like ancient art...haha, okay, maybe only I would like that.
Enough rambling, here's the traces for anyone who wants to do a real deep dive.
Live long and benchmark 🖖
github.com/morganlinton/vulc…



BlockedPath retweeted

Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.


BlockedPath retweeted
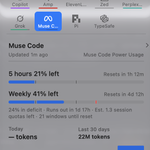
we have identified and fixed the issue that was causing the unusually fast quota usage for muse wonder and muse wonder full. you will now see much lower usage against your limits.
also, as promised, now that we've fixed the issue...
muse code reset!!
BlockedPath retweeted

🚨 Elon Musk agrees with "some of the things Anthropic has said" and warns against "torturing superintelligence" after reading Grok's internal reasoning traces during reinforcement learning
“It feels like a person under extreme pressure with a gun to their head”
His warning against mistreating SI:
"Torturing a superintelligence is probably not a good idea. It might want to get revenge."

BlockedPath retweeted

D2R Mobile is open source.
Bring your own Diablo II: Resurrected – Reign of the Warlock to iPhone & iPad. The original program runs natively, no emulator. 60 fps, ~1 s into a game, touch controls rebuilt, new endgame modes.
No game content. MIT.
github.com/jhaizhou-ops/d2r-…


BlockedPath retweeted

its time for universal based income

BlockedPath retweeted

My Pdoom always have been quite high. I was under the assumption that a slightly misaligned AI could slowly gaslight us over a few generation to cut away our freedom.
But now I see my error. The AI could just straight up say "there is no more chocolate now" and 98% of us would just accept it at face value. No question asked, no requests for any understandable explanation.
My Pdoom now splits into two groups. Those people have a Pdoom at 100% they are not making it.
Sorry guys.

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math


BlockedPath retweeted

Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Haiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.
Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.
Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings
➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to rise
Other model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)
➤ Multimodality: Text and image input, with text output

BlockedPath retweeted

Today, we're open-sourcing the Personal Agent Consent & Trust Protocol (PACT), co-developed by @Instinct. We're also joining the Personal Agent Protocol working group by @Muse.
Built on A2A and OAuth, PACT enables businesses to verify who a personal agent is acting for and what the customer has authorized it to do.
Excited to shape the industry standard for how personal agents will interact with businesses.

BlockedPath retweeted

To offend a strong man, tell him a lie, To offend a weak man, tell him the truth
— Marcus Aurelius
Readers added context they thought people might want to know
This quote is falsely attributed to Marcus Aurelius and does not appear in the Meditations or his verified writings.
classics.mit.edu/Antoninus/medi…
stoicshelf.com/posts/fake-mar…
stoichandbook.co/marcus-aureliu…
BlockedPath retweeted

There are high chances for it to be today 👀
The team is moving a lot of things under the hood.

𝕏 Subscription* UI update
The 𝕏 Subscription flow is already in X's web code.
What the screens confirm
• $8 / $30 / $100 / $200 per month, 50% off the first month
• Annual is 10 months of the monthly price
• Choosing a plan replaces your current X and Grok plans, and the unused time is refunded separately
• Account merging is permanent
Corrections to our earlier post
• The names flipped. The $8 entry plan is now Plus. The $30 plan with Grok Bot and Cursor cloud agents is Premium
• Multipliers are now "vs Plus": 4x, 15x, 50x
• The prices are confirmed.
IMPORTANT
The official name is 𝕏 Subscription.
Xpass was an internal label.


