

Building personal AI infrastructure. Local LLMs, coding agents, open-source models. Real hardware, real constraints. Learning in public.
Maryland
Joined April 2009
- Tweets8.6K
- Following654
- Followers1.1K
- Likes7.4K


BlockedPath retweeted

The traces for my Muse Wonder Full benchmark with @VulcanBench are now live on Github.
I'm a big believer in not just sharing data and results, but also showing all the details so anyone can analyze every single result.
To me, the most interesting thing about looking at traces is seeing how different models think
I find Muse Wonder Full to actually be a very interesting model to see think because it's actually very accurate, but overthinks, causing it to use a lot more tokens, and take a lot more time than other frontier models.
To me, I don't really see this as bad, more like an opportunity to see a model before it reaches its full potential in many ways.
Lately I've been thinking of frontier models, and more specifically, the traces from these models, as a form of art, capturing a moment in time, a month or two later, these models will be completely different, but the traces will always be a piece of history.
Maybe some day we'll have the VulcanBench museum where you can look at early model traces and examine them like ancient art...haha, okay, maybe only I would like that.
Enough rambling, here's the traces for anyone who wants to do a real deep dive.
Live long and benchmark 🖖
github.com/morganlinton/vulc…

I put Opus 5.5 and Muse Wonder Full through 8 rounds, both on high effort: science, knowledge, math, tool use, agents, coding, speed and cost.
Final: Opus 5–1, with 2 draws.
The twist: on hard reasoning they're dead even. The gap is everything else. 🧵


Method: Inspect AI, one try per question, same local proxy for both.
Caveats: small samples, so the agent rounds are close calls. MMLU-Pro gave each model different questions. Muse's "ANSWER: $H" formatting costs it 8–15 pts on strict graders, so I scored it leniently.

Why Muse loses on speed and cost: it writes ~4.5× the tokens per answer and takes ~4× the steps on coding tasks.
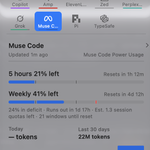
Same benchmark, fresh plans: Muse burned 44% of its weekly quota and hit its 5-hour cap. Claude used 10%, counting everything else I ran that day.


Round by round:
• GPQA (science): Muse 92.9% vs 91.4%
• MMLU-Pro: Opus 93.5% vs 88.5%
• AIME 2026: both 30/30
• BFCL tool calls: 77.1% each
• τ²-bench agents: Opus 85% vs 80%
• SWE-bench: Opus 7/8 vs 6/8
• Speed and cost: Opus, easily


Interesting, opus is king, but Ill run wonderfull ,over sol or astra in pi and claude code hehe

Okay so I managed to squeeze in getting model cards out today for my Muse Wonder Full benchmark with @VulcanBench - enjoy!
This, plus all the data from every run will be on the VulcanBench site soon(ish), and all of the traces will be on Github as well.
Everything I do with VulcanBench is free and open source. As a truly independent benchmark (it's just me!) I share it all, every single trace from every run, plus the source code for VulcanBench so you can even re-rerun specific tests, or the entire benchmark if you want to.
What stands out looking at this is that Astra is fast, but you pay for it. GPT-6.1 Sol is fast and cheap. Opus wins in accuracy, and Muse Wonder is accurate, but expensive and slow.
Right now, with the data I have, I don't think I would use Muse Wonder for coding, and I'm not sure that's the market they're going after, yet.
That being said, looking at the accuracy numbers, it's clear the Muse team has built a very intelligent model. If they can figure out how to wrangle the time/cost per task, they could very easily become a model usable for daily coding tasks.
Live long and benchmark 🖖



BlockedPath retweeted

Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.


OpenAI is taking straight L’s to the dome

Grok Voice 3.0 is now the world's most intelligent speech-to-speech voice model
It ranks #1 on Artificial Analysis, responds in under a second, and costs less per task than OpenAI's GPT-Live-1 and GPT-Realtime-2.1 while outperforming everything on the leaderboard
And it's already handling millions of conversations daily inside Tesla vehicles, allowing drivers to check calendars, reply to emails, order coffee, or even book dinner through Grok Bot, completely hands-free
This is insanely impressive progress from the SpaceXSI

Grok bot just wants love too lol
give mee a 30 second video on what you think it feels like to be ai, elevenlabs for narration, ffmpeg, python, javascript for the video.
Hate to say this but muse wonder full usage is horrible. @alexandr_wang @MetaforDevs


I said this recently, people are the easiest attack vector.

We discovered a sophisticated recording device that was hidden inside one of our offices. We used our models to understand the device and where it had come from, identifying that a specific employee had planted it a few days earlier. We referred the matter to the FBI, and we’re grateful to the agents and prosecutors who moved quickly to make an arrest. The FBI’s investigation is ongoing and we will continue to support their work.
At this time, we have no indications of this individual inappropriately accessing or exfiltrating model weights, source code, or customer data. The employee was terminated.
We take protecting our technology, data, and people seriously, and as a matter of national importance. Our security program is designed to protect against a wide range of threat actors, from insider risks to cybercriminals to nation states, and this case is an example of how AI can help address these sophisticated security threats.


