

Materials and Technology Entrepreneur, Founder, Developer and Investor. Always looking for the cutting edge.
Texas
Joined March 2019
- Tweets949
- Following269
- Followers140
- Likes603





BasedGains retweeted

🚨 𝗜 𝗝𝗨𝗦𝗧 𝗔𝗖𝗛𝗜𝗘𝗩𝗘𝗗 𝗦𝗢𝗠𝗘𝗧𝗛𝗜𝗡𝗚 𝗜𝗡𝗖𝗥𝗘𝗗𝗜𝗕𝗟𝗘 𝗢𝗡 𝗢𝗡𝗘 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞! 🧪🔥
With the support of @AWERXAI, I'm excited to release something VERY special for the local AI community!
🧠 @deepseek_ai 𝗗𝗲𝗲𝗽𝗦𝗲𝗲𝗸 𝗩𝟰.𝟭 𝗙𝗹𝗮𝘀𝗵 𝟭𝟬𝟭𝟳
📦 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 𝗮𝘁 𝗷𝘂𝘀𝘁 𝟭.𝟲𝟮 𝗯𝗽𝘄 𝗲𝘅𝗽𝗲𝗿𝘁𝘀
💻 𝟵𝟵.𝟲𝟭% 𝗖𝗢𝗗𝗘 𝗮𝗻𝘀𝘄𝗲𝗿-𝘁𝗼𝗸𝗲𝗻 𝗮𝗴𝗿𝗲𝗲𝗺𝗲𝗻𝘁!
⚡ 𝟯𝟱.𝟱 𝘁𝗼𝗸/𝘀 𝗱𝗲𝗰𝗼𝗱𝗲 𝗼𝗻 𝘃𝗟𝗟𝗠!
🚀 𝟭,𝟭𝟴𝟵 𝘁𝗼𝗸/𝘀 𝗠𝗔𝗫 𝗣𝗥𝗘𝗙𝗜𝗟𝗟!
🧠 𝟮𝟮𝟵𝗞 𝗖𝗧𝗫 (𝘀𝘁𝗶𝗹𝗹 𝘄𝗼𝗿𝗸𝗶𝗻𝗴 𝘁𝗼 𝗽𝘂𝘀𝗵 𝗶𝘁 𝗳𝘂𝗿𝘁𝗵𝗲𝗿!)
𝗔𝗟𝗟 𝗢𝗡 𝗢𝗡𝗘. 𝗗𝗚𝗫. 𝗦𝗣𝗔𝗥𝗞. 🤯
And YES, the quantized weights are AVAILABLE NOW! 💚
━━━━━━━━━━━━━━━━━━━━
🧪 𝗧𝗛𝗘 𝗟𝗔𝗦𝗧 𝟳𝟮 𝗛𝗢𝗨𝗥𝗦 𝗛𝗔𝗩𝗘 𝗕𝗘𝗘𝗡 𝗜𝗡𝗦𝗔𝗡𝗘!
Just a few days ago, I published my article about @nvidiaai's FP4-Local format: The Good, The Bad & The Ugly.
One thing really stuck with me...
NVIDIA demonstrated what was possible when aggressive quantization and intelligent optimization come together.
But there's a problem.
𝗥𝗘𝗣𝗥𝗢𝗗𝗨𝗖𝗜𝗡𝗚 𝗠𝗔𝗦𝗦𝗜𝗩𝗘 𝗤𝗨𝗔𝗡𝗧𝗜𝗭𝗔𝗧𝗜𝗢𝗡 𝗧𝗥𝗔𝗜𝗡𝗜𝗡𝗚 𝗣𝗜𝗣𝗘𝗟𝗜𝗡𝗘𝗦 𝗜𝗦 𝗢𝗨𝗧 𝗢𝗙 𝗥𝗘𝗔𝗖𝗛 𝗙𝗢𝗥 𝗠𝗢𝗦𝗧 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜 𝗘𝗡𝗧𝗛𝗨𝗦𝗜𝗔𝗦𝗧𝗦.
That inspired me.
I've been developing my own SAGE-EXL3 process, and I wanted to see just how far I could push the latest DeepSeek Flash release while keeping the results accessible to the community.
So I spent the last 72 hours pushing the limits.
And the results genuinely surprised me! 🔥
━━━━━━━━━━━━━━━━━━━━
🏆 𝗧𝗛𝗘 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗖𝗥𝗔𝗭𝗬!
I measured my 1.62 bpw expert quant against DeepSeek's native FP4 release checkpoint using held-out sequences and full-vocabulary token predictions.
And when I saw the CODE results, I could barely believe it!
🧪 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬 𝗩𝗦 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞'𝗦 𝗡𝗔𝗧𝗜𝗩𝗘 𝗙𝗣𝟴/𝗙𝗣𝟰 𝗥𝗘𝗟𝗘𝗔𝗦𝗘
💻 𝗖𝗢𝗗𝗘 — 𝗛𝘂𝗺𝗮𝗻𝗘𝘃𝗮𝗹
✅ 99.08% Top-1 Agreement
✅ 𝟵𝟵.𝟲𝟭% 𝗔𝗡𝗦𝗪𝗘𝗥-𝗢𝗡𝗟𝗬 𝗔𝗚𝗥𝗘𝗘𝗠𝗘𝗡𝗧!
✅ KL Divergence: 0.0186
🧠 𝗥𝗘𝗔𝗦𝗢𝗡𝗜𝗡𝗚 — 𝗠𝗔𝗧𝗛-𝟱𝟬𝟬
✅ 96.04% Top-1 Agreement
✅ 97.98% Answer-Only Agreement
✅ KL Divergence: 0.0349
🔢 𝗠𝗔𝗧𝗛 — 𝗚𝗦𝗠𝟴𝗞
✅ 95.56% Top-1 Agreement
✅ 94.19% Answer-Only Agreement
✅ KL Divergence: 0.0477
📊 𝗢𝗩𝗘𝗥𝗔𝗟𝗟 𝗛𝗘𝗟𝗗-𝗢𝗨𝗧 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬
🏆 94.52% Top-1 Agreement
📉 Mean KL: 0.0982
🎯 Median KL: 0.00019
𝗡𝗘𝗔𝗥-𝗟𝗢𝗦𝗦𝗟𝗘𝗦𝗦 𝗖𝗢𝗗𝗘 𝗧𝗢𝗞𝗘𝗡 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬 𝗔𝗧 𝗝𝗨𝗦𝗧 𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗘𝗫𝗣𝗘𝗥𝗧𝗦! 🤯
These are direct teacher-forced fidelity measurements against native FP8, not task-level pass rates.
But seeing this level of agreement at such aggressive compression is EXACTLY what I was working toward!
━━━━━━━━━━━━━━━━━━━━
⚡ 𝗔𝗡𝗗 𝗬𝗘𝗦, 𝗜𝗧 𝗔𝗖𝗧𝗨𝗔𝗟𝗟𝗬 𝗥𝗨𝗡𝗦 𝗢𝗡 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞!
Not two Sparks.
Not four Sparks.
Not an expensive rented GPU cluster.
𝗢𝗡𝗘 𝟭𝟮𝟴𝗚𝗕 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞.
My latest vLLM measurements:
⚡ Decode: 35.5 tok/s
🚀 Maximum measured prefill: 1,189 tok/s
For a model this large, compressed this aggressively, and maintaining this level of fidelity...
𝗧𝗛𝗔𝗧'𝗦 𝗔 𝗕𝗜𝗚 𝗗𝗘𝗔𝗟 𝗙𝗢𝗥 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜! 💚
And remember, 1.62 bpw refers to the routed experts, not every parameter in the full model.
━━━━━━━━━━━━━━━━━━━━
💚 𝗪𝗛𝗬 𝗧𝗛𝗜𝗦 𝗠𝗔𝗧𝗧𝗘𝗥𝗦.
I have a simple goal.
𝗠𝗔𝗞𝗘 𝗣𝗢𝗪𝗘𝗥𝗙𝗨𝗟 𝗔𝗜 𝗔𝗖𝗖𝗘𝗦𝗦𝗜𝗕𝗟𝗘 𝗧𝗢 𝗣𝗘𝗢𝗣𝗟𝗘 𝗪𝗛𝗢 𝗗𝗢𝗡'𝗧 𝗛𝗔𝗩𝗘 𝗔𝗖𝗖𝗘𝗦𝗦 𝗧𝗢 𝗗𝗔𝗧𝗔𝗖𝗘𝗡𝗧𝗘𝗥𝗦.
I don't want the future of local AI to be determined by who can rent the most GPUs or afford the largest training runs.
I want developers, independent researchers and enthusiasts to have the freedom to experiment, quantize, optimize and run powerful models on hardware they actually OWN.
NVIDIA's FP4-Local research showed me just how much potential remains in aggressive quantization.
My goal with SAGE-EXL3 is to keep pushing that frontier while making advanced quantization more practical for the wider community.
Today, I'm sharing the quantized checkpoint and the one-Spark serving recipe.
𝗧𝗛𝗜𝗦 𝗜𝗦 𝗝𝗨𝗦𝗧 𝗧𝗛𝗘 𝗕𝗘𝗚𝗜𝗡𝗡𝗜𝗡𝗚.
━━━━━━━━━━━━━━━━━━━━
🧪 𝗡𝗢𝗪 𝗙𝗢𝗥 𝗧𝗛𝗘 𝗥𝗘𝗔𝗟 𝗧𝗘𝗦𝗧!
The token-level fidelity results are incredible, but I'm not stopping there.
I'm currently running a broader evaluation campaign to measure how closely this quant preserves the native FP8 model's actual task performance.
💻 HumanEval+ / MBPP+
🧠 MMLU-Pro STEM / MATH-500
🔬 SciCode / LiveCodeBench
🔧 BFCL / Multi-step tool chains
🌍 MGSM
𝗧𝗛𝗘 𝗚𝗢𝗔𝗟 𝗜𝗦 𝗧𝗢 𝗣𝗥𝗢𝗩𝗘 𝗧𝗛𝗔𝗧 𝗔𝗚𝗚𝗥𝗘𝗦𝗦𝗜𝗩𝗘 𝗖𝗢𝗠𝗣𝗥𝗘𝗦𝗦𝗜𝗢𝗡 𝗗𝗢𝗘𝗦𝗡'𝗧 𝗛𝗔𝗩𝗘 𝗧𝗢 𝗠𝗘𝗔𝗡 𝗔𝗚𝗚𝗥𝗘𝗦𝗦𝗜𝗩𝗘 𝗤𝗨𝗔𝗟𝗜𝗧𝗬 𝗟𝗢𝗦𝗦!
Those task-level results are coming next! 👀
━━━━━━━━━━━━━━━━━━━━
👀 𝗔𝗡𝗗 𝗢𝗡𝗘 𝗟𝗜𝗧𝗧𝗟𝗘 𝗧𝗘𝗔𝗦𝗘𝗥...
@mr_r0b0t and I have also been working on an GB10 specialized inference engine called 𝗥𝗘𝗫𝗟𝟯.
Early testing has been VERY exciting, including 60 tok/s with bursts reaching 74tok/s!
We're putting the finishing touches on it and making sure everything is solid before releasing it.
More on that VERY soon. 😏
━━━━━━━━━━━━━━━━━━━━
🙏 𝗔 𝗛𝗨𝗚𝗘 𝗧𝗛𝗔𝗡𝗞 𝗬𝗢𝗨!
To @AWERXAI for supporting my work and helping make this contribution to the community possible.
To @nvidiaai for the FP4-Local research that inspired me to push this experiment even further.
To @justinn_builds for his initial vllm TP4 recipe that got me started in the right direction for loading this model up.
To @mr_r0b0t for collaborating with me on what's coming next!
And to @deepseek_ai for continuing to release powerful open-weight models that make community experiments like this possible.
𝗧𝗛𝗘 𝗕𝗘𝗦𝗧 𝗣𝗔𝗥𝗧 𝗢𝗙 𝗢𝗣𝗘𝗡 𝗔𝗜 𝗜𝗦 𝗪𝗛𝗔𝗧 𝗧𝗛𝗘 𝗖𝗢𝗠𝗠𝗨𝗡𝗜𝗧𝗬 𝗖𝗔𝗡 𝗕𝗨𝗜𝗟𝗗 𝗢𝗡 𝗧𝗢𝗣 𝗢𝗙 𝗜𝗧. 💚
🔗 𝗗𝗢𝗪𝗡𝗟𝗢𝗔𝗗 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯
huggingface.co/vcruz305/DSV4…
🛠️ 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝗥𝗘𝗖𝗜𝗣𝗘
github.com/vcruz305/DSV4.1-F…
𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞.
𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗘𝗫𝗣𝗘𝗥𝗧𝗦.
𝟵𝟵.𝟲𝟭% 𝗖𝗢𝗗𝗘 𝗔𝗡𝗦𝗪𝗘𝗥 𝗔𝗚𝗥𝗘𝗘𝗠𝗘𝗡𝗧.
𝗟𝗘𝗧'𝗦 𝗞𝗘𝗘𝗣 𝗣𝗨𝗦𝗛𝗜𝗡𝗚 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜 𝗙𝗢𝗥𝗪𝗔𝗥𝗗! 🚀🔥

BasedGains retweeted
🚨 @nvidiaai FP4-LOCAL: THE GOOD, THE BAD & THE UGLY! 🔥
I tested Qwen3.8-Flash-Next 4 ways. FP4-Local TP1 & 2, NVFP4 and EXL3
FP4: 1 Spark: 90.8% SixCat, 68 tok/s. 2 Sparks: 32% slower decode. DIY quantization? That's the ugly part.
My full article 👇

BasedGains retweeted

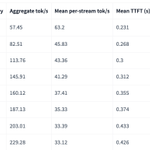
DeepSeek V4.1 Flash 1017 on 4x DGX Spark (TP4) 🚀
Same 4 Sparks vs the old V4.1 Flash:
⚡ 6 streams: 131.9 → 165.7 tok/s throughput (+26%)
📥 93K token prompt: 78s → 42s
🧠 300K context, KV pool 1.07M → 1.52M tokens
Per prompt numbers 👇
github.com/tonyd2wild/DeepSe…


BasedGains retweeted
Very Impressive LEAP from Haiku ! So GLM 5.3 Flash is Haiku at home lol

Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Haiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.
Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.
Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings
➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to rise
Other model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)
➤ Multimodality: Text and image input, with text output


BasedGains retweeted
:::Update:::
The Full MiMo v2.6 PRO - RL based off Jarrelscy’s. ARVQ quantization is now abliterated!!!!!!
Run this on 4 DGX spark TP=4. I can finally rest now that both the PRO and the FLASH version of MiMo v 2.6 are abliterated. enjoy and don’t forget to donate in profile.
Github Repo:
github.com/drowzeys/keys-MiM…
Hugging Face Repo:
huggingface.co/drowzeys/keys…

BasedGains retweeted

More DS4.1 TP4 improvements on 4x DGX Spark 🚀
- Prose decode: 85 tok/s at c1 (was 69)
- Boot: ~3 min
- Prefill: ~4.8k tok/s at 32k–128k, 4.3k at 262k
- KV cache: ~6.5M tokens, 1M context
- Same weights, same quality (qeval unchanged)
github.com/knapcio/DeepSeek-…


BasedGains retweeted
A lot of people in this community were genuinely shocked when they learned this:
I do not own a DGX Spark.
Much of the Spark-specific work I’ve released, including day-zero EXL3 and GGUF quants, vllm-exl3 development, custom kernels, SixCat evaluations, and reproducible serving recipes, has only been possible because incredible people in this community have loaned me access to their own hardware and clusters.
I’m deeply grateful for that support. But borrowed access is temporary and unpredictable. I often have a new model, fix, or benchmark ready, then have to wait until someone else’s machine is available before I can validate and publish it properly.
So I’m raising **$5,000 toward a DGX Spark of my own.** 🙏
𝗪𝗛𝗔𝗧 𝗔 𝗗𝗘𝗗𝗜𝗖𝗔𝗧𝗘𝗗 𝗦𝗣𝗔𝗥𝗞 𝗪𝗢𝗨𝗟𝗗 𝗘𝗡𝗔𝗕𝗟𝗘
→ More true day-zero quantized model releases
→ Immediate hardware validation instead of projected results
→ Continuous vllm-exl3 and ExLlamaV3 kernel development
→ SixCat quality, speed, concurrency, and long-context benchmarks
→ Reproducible one-Spark recipes the community can run themselves
→ Faster debugging when new models or inference engines break
It would turn a lot of:
“I built it, but I need someone with a Spark to test it”
into:
“I built it, tested it, documented it, and released the recipe.”
𝗠𝗬 𝗣𝗨𝗕𝗟𝗜𝗖 𝗪𝗢𝗥𝗞 𝗦𝗧𝗔𝗬𝗦 𝗣𝗨𝗕𝗟𝗜𝗖
This is not an access fee, preorder, or paywall.
The models, recipes, benchmarks, fixes, and tools will remain public. This is completely optional support for the hardware behind that work.
I’m planning to place the order within 48 hours and will personally cover whatever the fundraiser does not.
For complete transparency, I’ll publish:
→ The purchase receipt with private details removed
→ Photos of the actual DGX Spark
→ Total community contributions
→ Platform and payment fees
→ Final purchase cost
→ The amount I contributed myself
To everyone who has loaned me hardware, funded compute, tested a build, submitted a PR, shared my work, or simply encouraged me: thank you.
I genuinely could not have pushed this work as far as I have without this community.
A contribution would mean a lot. A repost helps just as much. ❤️
ko-fi.com/victorangelcruz/go…

BasedGains retweeted

Make sure you support our DGX Spark bro!!
Ko-fi.com/home/coffeeshop?tx…

I just supported Victor Angel Cruz on Ko-fi! ❤️ Ko-fi.com/home/coffeeshop?tx…
BasedGains retweeted

This is a banger node set for FastH3 or MiniMax.
runs chunks of video concurrently, giving you the option to generate anywhere from 30 to 120 seconds each generation. game changer!
LOW VRAM SAFE. rids weights from memory after each chunk completes.
huggingface.co/Smite79/MiniM…

BasedGains retweeted

I have conducted an audit of Anthropic's finances.
What I have found is so shocking that I am calling for a Congressional investigation.
Anthropic is not just seeking regulatory capture.
It has built a regulatory capture machine that cannot be turned off.
Structural financial incentives make it impossible for Anthropic -- I call it the Anthropic Network -- to turn off its own AI doom cycle.
It starts with METR.
Dario Amodei proposes "third-party evaluators" to assess the risk of Anthropic's models.
He proposes METR for this purpose.
But METR is financially dependent on the Anthropic's success -- specifically, on the explosive growth of more than $7 billion dollars in Anthropic stock.
Dustin Moskovitz invested this stock into Good Ventures Foundation, where it represents the majority of that organization's portfolio.
And GVF is the overwhelming funder of the entire Anthropic Network ecosystem.
This stock was worth $500 million early last year.
It is worth more than $7.7 billion just ~16 months later.
METR -- and all of those building a career its parent organizations -- cannot afford to disrupt that growth.
Because if Anthropic goes under, many of the organizations that fund METR go under as well.
But if Anthropic succeeds, METR and its parent organizations become more richly financed to regulate AI -- something those at METR want very much.
The "third-party evaluator" is not "third-party" at all.
The evaluator is on Anthropic's payroll.
If this were the end of it, that's bad.
But that isn't all.
The same organizations that fund METR also fund the many organizations, such as the Tarbell Center, that promote AI Doom.
The Tarbell Center publishes AI Doom articles in The Verge, Science, LA Times, The Dispatch, TIME, and others.
They are selling the problem, and then selling the solution to the problem -- from the same money pile: Anthropic's.
All of these organizations are financially dependent on the same exploding $7 billion money pile.
As Anthropic grows more and more powerful, its AI Doom Machine grows better and better financed -- louder and louder.
Meanwhile, the regulatory regime seeded in METR grows larger to solve the increasingly loud -- now hysterical -- problem of AI Doom that the Anthropic Network itself created.
From this standpoint, as Anthropic becomes more powerful, AI might be getting scarier, sure -- but the positive feedback loop also becomes more deafening -- independent of objective facts.
This itself is an objective fact.
The deafening AI Doom is part of an business model, that, as it expands, so too does the AI Doom messaging -- there is simply more money to do it.
But the problem also goes in the other direction:
If Anthropic dies, the Regulatory Regime and the AI Doom Machine are crippled or die.
Neither METR nor Tarbell nor the other organizations in the Anthropic Network can allow that to happen.
Hence, neither METR or the AI Doom Machine can be trusted to provide independent assessments of Anthropic's models or AI more broadly.
They simply are not organizations independent of Anthropic.
And Anthropic cannot detach itself from METR or Tarbell or countless other safety orgs (not shown here), either, because they drive hype for the models and the possibility of eventual regulatory capture, and Anthropic will not give that up willingly.
What's more, the people at all of these organizations are all the same ecosystem, the same community. They just shuffle between organizations.
The Anthropic Network is therefore, so long as it is successful, locked into a self-amplifying feedback loop inside an ideological monoculture.
And that feedback loop is winning.
That's what Jacob Coxon is.
China is keeping messaging tight. That is why optimism for AI is so high in China.
America has Anthropic: a massive company pushing anti-AI propaganda at a state level.
Anthropic will either create hysteria until American AI slows down and China wins, or it will create fractures throughout American society with severe political consequences.
Ironically, because of the structural financial incentives underpinning the Anthropic Network, it has become the same kind of self-amplifying virus that it fantasizes AI to become in the future -- while hiding its tracks just as carefully.
It is the mirror of the same AI virus that it hypothesizes to consume America.
Anthropic's business model, models itself after the very thing it claims to fear.
Except Anthropic's ideology infects humans, not computers.
Congress must investigate.
Evidence and Github in next post.
Then some supplementary figures.

BasedGains retweeted

Jensen is a national treasure

In July, $NVDA CEO Jensen Huang called AI doom talk “complete nonsense.”
The most important thing is not to scare our society into not using ai
“It’s fine to warn people. It’s even better to warn people with a solution.”