
Investor, L/S tech + consumer
NYC
Joined February 2020
- Tweets1.5K
- Following1.4K
- Followers676
- Likes3.6K



54th Parallel retweeted

hey @pmarca maybe good to reign in your pawns here

54th Parallel retweeted

It has become fashionable to quote our token index as support for a bearish view on the AI trade. We have pushed back gently a few times, because nothing here is definitive and people should come to their own conclusions. It now seems worth saying a little more.
In June we clarified what our LLM Token Index measures: what API users in our sample actually paid per million tokens. A usage-weighted price. Not token volume, not total spend. We noted it can be read, loosely, as revealed willingness to pay for frontier intelligence.
We should have emphasized the conditions. The binding one is that the intelligence content of a token stays stable. Over a few weeks that is defensible. Across a couple of release cycles it clearly is not. While a token is simply the wrong unit for intelligence, measuring capability itself without bias is also extremely hard. [Btw we will struggle with this measurement problem all over the place as AI proliferates delivering non-market economic value.]
The upshot is that the message from June landed. Maybe a little too well, because it created a new misread: that a falling index is necessarily bearish for the AI trade, since if token prices fall, model-layer margins must follow.
Two things are being conflated.
The deflation in our sample is real, and it is recent. It dates from the end of May. The index peaked at $2.07 on May 28 and sits at $1.00 as of Sept 21, down 52%. But the same index rose 67% from January into that peak, and few read the rise as bullish for lab margins. It is not bearish now. A usage-weighted price moves with the mix, in both directions.
What the mix actually says: more work, at least within our sample, is being routed to cheap, fast models, and labs keep shipping more mid-tier variants. Most everyday tasks never needed a frontier model. That is partial equilibrium for the users we track, and our methodology note is explicit that this index alone cannot separate substitution from efficient agentic routing.
Compute demand is a different question entirely, answered by different data series. Our H200 non-hyperscaler rental index has rerated through the summer: $2.87 average in June, $3.29 now, with a record $3.32 on Sept 19. B200 is $5.76, up 7% over the same stretch and 31% year to date. B300, our newest and thinnest series, is up 44% since inception in late April. H100 is off 7% from its August high, consistent with workloads migrating up the stack. Rents on the parts that are actually scarce are not signaling a demand stall.
A world of mass agentic use is one where cheap tokens are nearly all of the count. Total token usage should keep growing far faster than the price is falling, with most of that growth coming from cheap, fast, and increasingly open models. The usage-weighted price can keep falling anyway. Our view, not a finding from this index: the highest value-add work still routes through frontier models, and that is where most of the economics will accrue. In any event, the implication for compute is more, not less.
An astronomical number of tokens, most of them from cheap flash models, is what economy-wide AI proliferation should look like. It is not a demand stall.


Our LLM Token Expenditure Index should really have been named the “Token Expenditure Price Index” bc it’s an expenditure or usage-weighted average token price index. It tells you how much currently the entire market AI is paying for a million LLM tokens irrespective of models.
The naming might’ve led to some misinterpretations as some seem to have interpreted the index as either the total volume of token used or the average price of tokens. In reality, the index captures something more subtle than either interpretation: it tells us the marginal willingness to pay for LLM models.
Over the course of the year, while model token prices haven’t moved that much, the usage patterns have moved dramatically leading to the token index movement down and then up sharply as AI users moved en masse into using cheap open weight models and then en masse to the much more expensive frontier closed source models. From consumers to enterprises, everyone is Claude-maxxing!
More recently, as can be seen in the chart below, the token index has stagnated, which suggests that usage migration towards frontier models has slowed. Time will tell whether this is just a pause or an inflection in the trend as users move back towards open weights models. In a sense our token index could be roughly interpreted as a “quality premium” of frontier models over the much cheaper open source models (if we assume users and prices are both “rational”).
For more details on what we offer beyond the few indices we’ve listed on the Bloomberg Terminal, check us out at silicondata.com and give us a holler! 😊


54th Parallel retweeted

There are so many things that are wrong in this post that it's hard to know where to begin. This honestly is starting to sound like the incoherent ramblings of a mad man. Is there really such a chasm of beliefs and information btwn the fully AGI-pilled technoptimists living in SF and everyone else?
In the scenario, where AI is driving risk free interest rates up and developing countries into default and the world is collapsing around us, the US GDP wouldn't be growing 10% a year. GDP is currently calculated as the final sales of goods and services. The USSR used to calculate GDP by summing up output bc of the lack of markets to price output properly, which also led to extreme misallocation of capital and poorly made top-down decisions on what to produce. That's just not the US economy.
If the (US) govt's rates go up, the hyperscalers' rates will be higher still bc default risk premium isn't negative. The development of AI will have long halted before such scenarios fully developed.
And where are they seeing data or evidence for these "little money turned into lots of money" or "$1 turned into $20" investments? Even the hyperscaler bulls are not claiming such high ROICs.
This is honestly what I had said about "techoptimists". They are genuinely nice, curious, and well-intentioned people, but they really don't seem to understand basic economics or the concept of equilibrium. 🤦🏻♂️
I'm a big fan of Dwarkesh' podcasts but this is honestly pretty bad.

Could AI investment start a global sovereign debt crisis?
If you look at the SpaceX-Google deal, it is already the case that the entire capex for the data center can be paid off by leasing it out for roughly 1 year.
As we get closer to AGI, the returns on compute will be massive and obvious, many-fold the principal within a few years. And as AIs get more capable, the demand for the compute to serve them will be as large as the demand for white collar labor - aka 10s of trillions of dollars a year.
In this world, why would anyone invest in anything but datacenters/ semiconductors/ energy/ robotics, which will have astronomical returns?
There may be many upsides to this world, but one of the downsides would be many sovereign debt crises around the world
In 1980, Fed Chair Paul Volcker raised interest rates about 10 pp in order to fight inflation - and this drove some 40 odd countries, mostly in Latin America, to default. A similar thing might happen again - what @BasilHalperin calls the second Volcker shock.
To put it in very plain terms, investors would say, "Hey, why am I going to lend Egypt money at 5% when I could just buy relatively safer investment-grade hyperscaler debt in America at 10%?" It’s even worse, because the investor also correctly notices that rising rates make Egypt more likely to default, so they demand even higher rates to account for the risk. This makes it even harder for Egypt to continue servicing their debt, which accelerates the default.
Most equities would get pummeled too. Anything valued for stable cash flows craters in price as the discount rate increases, resulting in a barbell of market equity returns. The market overall may be up because of AI stocks, but almost every other stock will be down.
The U.S. fiscal situation may also be troubling because short-duration U.S. debt would get refurbished to the new interest rate just as the main source of federal revenue (labor) is decreasing in relative share.
At the end of the day, I think the U.S. government will be mostly fine, because the data centers are on American soil, and Congress can always invent new taxes to capture some of the token revenue, or, less efficiently, the investment itself.
All this being said, if the economy is growing tens of percent a year, this would also be a world of great abundance!
I think this is a bunch of nerd speak for the very basic fact that in a world with explosive growth as a result of AI, there's just a lot of opportunities to invest and grow money. The higher interest rate reflects the fact that the opportunity cost for government spending just shoots up extremely high. You're paying a ton of opportunity cost to give people pensions now rather than building a new datacenter.
And yet, net-net, most people might still be significantly better off.


54th Parallel retweeted

I think web browsers are going to die way sooner than people think.
They are already archaic for heavy AI users like me.
Everything is going to be done within the AI agent itself.
Your AI will have its own identity, you'll define the permissions for what it can and cannot do, and that'll be it.
There will be an equivalent to Google My Business, whereby every business will create their Claude account and have a Claude AI that represents them with its own unique name, identity, contact details, etc.
Then, the final piece of the puzzle is the coordination layer: both individuals and businesses will be able to opt in to a massive multiplayer online network of human and AI hybrids, where the AI goes off and finds exactly what it is you need by talking to other AIs and humans in the background.
Once you have this, it's all over. Browsers die, websites die, most SaaS dies - the AI subsumes everything.
54th Parallel retweeted

The first experimental evidence of recursive self-improvement (RSI).
Autoresearching the autoresearch agent for eight days.
The result beats the harness we hand-tuned for two years, on held-out benchmarks: 🧵(1/7)
54th Parallel retweeted

Early results from the @snowflake's coco team on GLM-5.2 vs Opus-4.7 on dbt-bench — what the trajectories actually show 🧵
54th Parallel retweeted

Hundreds of billions of stock buyback/dividends INCOMING for $NVDA I'm serious.
I just got off a video call interview with Nvidia CFO Colette Kress after the earnings call. (Yes, Substacks get this kind of access now. Sorry, mainstream media.)
When I asked her whether the 50% FCF shareholder return plan after strategic pre-payments/investments is a permanent policy (not just this year), she said yes.
I then followed up by saying with some growth factored in that math points to hundreds of billions in stock buybacks and dividends soon, do you agree with that?
She nodded her head emphatically. "Yes! Yes. Yes. Do the math going forward, when will we meet a trillion dollars returned to shareholders? That's what we're pretty much saying. It's on the horizon.”
54th Parallel retweeted
Today, we share a breakthrough on the planar unit distance problem, a famous open question first posed by Paul Erdős in 1946.
For nearly 80 years, mathematicians believed the best possible solutions looked roughly like square grids.
An OpenAI model has now disproved that belief, discovering an entirely new family of constructions that performs better.
This marks the first time AI has autonomously solved a prominent open problem central to a field of mathematics.


54th Parallel retweeted

holy fuck, a hair dryer at a Paris airport broke Polymarket weather markets & made someone $34,000 richer
- polymarket was settling Paris temperature bets on a single Météo France sensor sitting near the Charles de Gaulle runway perimeter - basically unguarded
- the guy bought the long-shot outcome (like "22°C" when everyone expected 18°C) for pennies, since nobody thought it'd hit
- then he walked up to the probe and briefly heated the air around it with a portable heat source, spiking the reading just long enough to register as the daily max
- temperature snapped back to normal in minutes, the market resolved in his favor, and he cashed out - twice, on April 6 and April 15, before Météo France caught on and filed charges
hyperstitions.

54th Parallel retweeted

the current fear is is that AI homogenizes culture and turns humans into passive consumers
one counterpoint: in Go, human play showed very little improvement from 1950 to 2016 until alphago beat lee sedol - then human decision quality jumped. players started developing moves that were distinct both from previous human moves and from the novel moves introduced by machine intelligence
this seems more likely to me - fun times ahead


54th Parallel retweeted
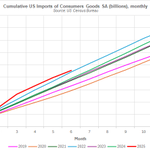
Too bad @LHSummers is not participating in today’s debate —so now I have to do it for him.
Here is his CPI chart, with the red part the forecast out to 2027 under the scenario that oil goes to $200/bbl.
It will take a lot to get a 1970s redux. Even $200/bbl oil won’t do it.

54th Parallel retweeted

The most important advice I could give to individual investors adopting AI: don't optimize for speed, optimize for rigor.
We play a game where average is punished. There is all sorts of empirical evidence of power law dynamics in public equity investing: 70%+ of long only's underperforming the index, no observable alpha in sell-side ratings T+1, and high full-cycle churn of multi-manager PMs (by design). <5% of investors/firms earn substantially all the alpha. Beating the market isn't a check the box exercise, it's a game of multi-dimensional genius built on the back of incredible day in, day out discipline. It requires not just good process, but real talent.
An average thesis is a losing thesis. An average PM is a losing PM. And AI tools can get you to average quality very quickly. That's almost completely useless, functionally.
So, optimize for rigor, because rigor is what it takes to outperform. A fast thesis is just AI slop (and will probabilistically lose money).
A few pieces of advice we give when we train analysts, and how AI shifts that advice.
"How your spend your time is your most important decision". One of AI's most incredible characteristics in investing is the ability to use it to cut bad ideas quickly. Accelerated hypothesis formation, front end risk checklists, pattern recognition engines, "what's in the stock" first cuts, automated 7-year models, comparative efficiency / margin uplift scoping, management capability reports, "what I have to believe" reports, systematized guidance hockey stick screening...I could go on and on. You can automate the "sniff test" part of hypothesis formation, and where I wasted 3-days in the past only to disqualify an idea, I can now disqualify that idea in 30 minutes. Today, this is about where I see 85% of AI's usefulness in investing (though as quantitative accuracy and agentic usability is increasing, use cases are expanding rapidly). Use AI to be more rigorous about how you spend your time.
"You will walk in with 10 things on your to do list, complete 4, and walk out with 12 things on your to do list...that your PM wants yesterday". In 13 years as a professional investor, I never once felt like I had my to do list complete. Always another idea to evaluate, another comparative margin analysis to do, another customer call to do, another hospital conference to fly to, another deep cohort analysis of some industry data, etc. Do I go on that bus tour or do I stay at the office and go deep on this idea in my pipeline? We are Pareto optimizing every day, it's always a tradeoff, and so much gets undone. The idea that public equity investors can be rigorous on every idea under coverage is obviously a myth...if you ever think you're "done", you don't know the nature of the game you are playing. I covered ideas as close as anyone at a firm with 3 ideas per investment professional, and STILL never felt like I knew enough about them, let alone when I ran an 80 stock portfolio. In embracing AI tools in my job now, I have this very unusual feeling of getting my to do list done and searching for more to do! It's a strange and invigorating feeling. Use AI to deepen rigor, augmenting the work you *should* do, but never had the time. AI-augmented versions of things you never had the time to do will increase rigor.
"Focus on the key drivers, stock picking is a game of Pareto optimization where 2-3 key variables are deterministic to stock outcomes". I could spend 365 days a year analyzing just a couple companies. It would be very boring, but I could do it. And that 347th data point or channel check wouldn't move the needle *most of the time*, but sometimes it would. In the Tiger cub world, we would often bemoan the PM's push to go deeper, deeper, deeper, ("man, isn't this enough work?") but sometimes it would matter (and when position sizes are multiple hundreds of millions, it matters). You could channel check weekly for months with no change, but one week those checks catch a key inflection before the market sniffs it out. Six industry conferences may be useless, but that 7th may uncover some key changes and inflections in the industry that become an investible signal. The high-velocity multi-manager world, relative to the Tiger cub world, is very much a Pareto optimization game. In multi-manager world, I covered 300 stocks, so it had to be...I was drowning just to complete the desktop research functions of that coverage let alone any primary research. Find the 2-3 variables that will move the stock, analyze those, ignore the rest. Well, there are many, many of the "Tiger" research playbooks that are now accessible to a higher velocity firm. Not to 100% quality, but compared to no work at all, 85% is immensely better in deepening insight & rigor than nothing. And, for that matter, a long only can now build an 85% as good earnings preview that may, once or twice a year, lead to a key entry/exit decision around quarters (without spending 30% of their working hours earnings prepping). Catching earnings infections isn't as critical as it is a a multi, but that "process blending" is now more possible. Maybe with AI augmentation, we can spend human time on the 2-3 key variables that matters, but spend machine time on the other 16 important variables, resulting in deeper and broader rigor. Because sometimes that 15th variable matters.
"The only certainty is your initial thesis will be wrong...how you babysit your thesis will determine failure or success". Securities are priced by discounting future cash flows, and no one has a perfect crystal ball. Building an investment thesis is a hubristic exercise effectively saying "I and I alone can see the future here". In reality, investing is a deeply Bayesian exercise where priors are constantly updated by new data and the best investors are stoically non-emotional about cutting when the fact pattern changes (emotional attachment to a broken thesis is the deepest sign of an amateur). Thesis tracking is a game of 24/7, always on, constant paranoia that the next 8-K is going to be some disgusting tape bomb. A wider net, a less emotional lens (tracking is the most deeply emotional part of investing, particularly when an idea goes against you, i.e. a great use case of a dispassionate machine), and systematic tracking of a broad set of data (structured & unstructured) is an absolute game changer in answering the simple question of "is my thesis right or wrong?". This is where recent native data capabilities and emerging Excel capabilities are so interesting (data trackers were first big use case that moved AI out of chatbots for me in investing AI)...track key drivers across multiple dimensions, understand how those key drivers translate back into revenues/profits/cash flow and business infections, and send signals back to me in an easy to use dashboard. Use AI to deeply enhance tracking rigor.
I could go on an on.
So, I agree with Bucket and sort of shake my head when I see people say "build an investment thesis in 1/10th the time". I think to myself, "why in the hell would you want to do that"? Firms have finite capital and if you run a 30 stock long only book with a 3-year duration, you don't want to run 10x ideas or 10x turnover. But what you do want is more rigorous understanding of those 30 ideas, and a more rigorous evaluation of your idea set and idea pipeline, ensuring you are allocating capital to the best available ideas at any time. You want to have a deeper set of priors grounded in past study of markets, industries, companies and managements. Rigor, not speed. Deeper, not faster (though by doing many things faster, it builds the time capacity to go deeper). This is why simple things like building AI capability to update models for Qs is helpful...in the triage moment of earnings, less time keying in a PR and more time evaluating what changed and why.
There's also an irreducible value of the human element in investing that people don't talk about enough. Decades of failed quantamental initiatives and the elusiveness of quantifying human alpha have etched that firmly in my belief system. If you think we can take the human out of the loop in fundamental investing, I am game to deeply and passionately argue the other side.
I plan to share more on this. The TLDR of all of this is even in Q4 '25 we considered that we were in "winter training" for AI. It wasn't yet spring, so take some time to learn the tools in anticipation/hope that they become more institutionally useful. Well, in just a few months, we've come out of winter and entering spring. The rapidity of improvement is remarkable. We are going to lean into that, as it's such a fascinating time to be alive and such a fascinating time to be an investor.
Stay tuned for more.

54th Parallel retweeted

On a recent Geopolitical Cousins episode I mentioned that BCA Research has opened its Gulf War dashboard to all users, including non-clients. Below is the promised link. Let us know if you'd want us to include some other data here.
bcaresearch.com/collection/b…

54th Parallel retweeted

Mid level non technical business unit leaders asking Claude where they can cut headcount to reduce waste
54th Parallel retweeted

BREAKING: Alibaba tested 18 AI coding agents on 100 real codebases, spanning 233 days each. they failed spectacularly.
turns out passing tests once is easy. maintaining code for 8 months without breaking everything is where AI completely collapses.
SWE-CI is the first benchmark that measures long-term code maintenance instead of one-shot bug fixes. each task tracks 71 consecutive commits of real evolution.
75% of models break previously working code during maintenance. only Claude Opus 4.5 and 4.6 stay above 50% zero-regression rate. every other model accumulates technical debt that compounds with every single iteration.
here's the brutal part:
- HumanEval and SWE-bench measure "does it work right now"
- SWE-CI measures "does it still work after 8 months of changes"
agents optimized for snapshot testing write brittle code that passes tests today but becomes completely unmaintainable tomorrow.
they built EvoScore to weight later iterations heavier than early ones. agents that sacrifice code quality for quick wins get punished when the consequences compound.
the AI coding narrative just got more honest.
most models can write code. almost none can maintain it.
