

1BusyGuy is a tech nerd.
U.S.A.
Joined May 2009
- Tweets5.3K
- Following1.2K
- Followers1.9K
- Likes2.8K




1BusyGuy retweeted

Qwen 3.8 27B (dense) running on a single RTX 4090 (24GB VRAM) at 65 tokens/sec decode with MTP!
260,000 context window or 65 tokens/sec decode with native MTP. The API cartel should be terrified.
We are officially running frontier tier agentic AI (benchmarks comparable to claude opus 4.6 max) on a single consumer gaming GPU.
I benchmarked Qwen3.8-27B on a single NVIDIA RTX 4090 (24GB VRAM, Ubuntu 22) using Unsloth’s Dynamic Q4_K_XL GGUF on the latest llama.cpp.
Here is the complete benchmark breakdown across both Context Scaling and MTP Overdrive (28k prompt baseline):
### PART 1: The Context Scaling Matrix (Pure Throughput)
# 1. Standard FP16 KV Cache (Unquantized):
- 80k Context: 2,664.7 t/s prefill | 40.68 t/s decode | 22.36 GB VRAM
- 100k Context: 2,678.7 t/s prefill | 40.89 t/s decode | 23.59 GB VRAM
(100k is the hard ceiling for unquantized f16 KV in 24GB VRAM)
# 2. Q8 Quantized KV Cache (-ctv q8_0 -ctk q8_0):
- 130k Context: 2,639.1 t/s prefill | 40.96 t/s decode | 22.18 GB VRAM
- 170k Context: 2,653.9 t/s prefill | 40.70 t/s decode | 23.68 GB VRAM
(170k is the sweet spot for heavy agentic coding workflows)
# 3. Q4 Quantized KV Cache (-ctv q4_0 -ctk q4_0):
- 260k Context: 2,659.8 t/s prefill | 40.70 t/s decode | 23.00 GB VRAM
Full 262k native context residing entirely in 24GB VRAM. Zero system RAM offload.
Stress test with a monster 142k real-world prompt (-c 170000, Q8 KV):
- Prefill: 1,829.50 tokens/s
- Decode: 31.3 tokens/s
- VRAM: 23.7 GB rock solid
### PART 2: Native MTP Overdrive (Trading Context for Speed)
Since MTP heads are baked into the architecture, enabling native speculative drafting pushes decode speeds straight to 60 t/s with zero external draft model:
# 1. MTP + Q8 KV Cache:
- 80k Context: 2,370.66 t/s prefill | 59.25 t/s decode | 23.4 GB VRAM
(MTP state buffers eat slightly more memory, making 80k the ceiling for Q8)
# 2. MTP + Q4 KV Cache:
- 130k Context: 2,391.09 t/s prefill | 60.10 t/s decode | 23.5 GB VRAM
(Sweet spot: 130,000 context running at a screaming 60 tps decode)
### Qwen3.8-27B vs Muse Glimmer 30B
Two days ago I benched Meta's Muse Glimmer 30B hitting 130k context unquantized (19.3 GB VRAM) pulling 50-75 t/s decode.
If you own a single RTX 3090 or RTX 4090, you have zero excuse to burn API credits.
### The Reproduction llama.cpp flags:
1. Max Context Stack (260,000 Context @ 41 tps):
./build/bin/llama-server -m Qwen3.8-27B-UD-Q4_K_XL.gguf -c 260000 -ngl 99 --port 8080 -ctv q4_0 -ctk q4_0
2. MTP Overdrive Stack (130,000 Context @ 60 tps):
./build/bin/llama-server -m Qwen3.8-27B-UD-Q4_K_XL.gguf -c 130000 -ngl 99 --port 8080 -ctv q4_0 -ctk q4_0 --spec-type draft-mtp --spec-draft-n-max 4 --spec-draft-p-min 0.7
Unsloth's Hugging Face GGUF links, intelligence/agentic benchmark details, and performance charts are posted in the replies.
Local compute is eating the cloud alive. How much monthly API spend does a 24GB setup like this actually replace for you?

We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Q…
- ModelScope:
modelscope.cn/collections/Qw…

1BusyGuy retweeted

LTX-2.3 🖼️🖌️Cinematic-VAE
- a custom VAE that works on a cinematic color grade directly into the decoder
-applies a subtle, darker greenish-teal tint to the output, evoking a soft
-eliminates post-processing color correction
👇
huggingface.co/rzgar/LTX-2.3…
1BusyGuy retweeted
Updated: 😃LTX 2.3 Video Edit Lora📽️✂️
-Helpful for video editing, background/subject removal, motion transfer etc.
-The new updated version improves on consistent results and prompt adherence
Model + Workflows:👇
huggingface.co/Alissonerdx/E…
1BusyGuy retweeted

LTX-2.3 Foley LoRA
- It adds Foley that actually matches the action on screen.
- stops the model from defaulting to background scores when you just want real-world noise.
- makes generations feel like actual raw footage
huggingface.co/FuzzPuppy/LTX…


1BusyGuy retweeted

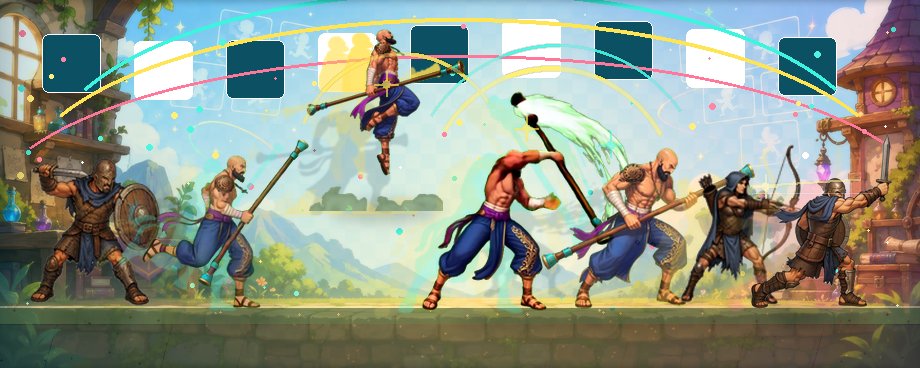
I'm thrilled to see such positive responses to my 2D Sprite Sheet Pipeline write up!
I'm really excited to see what you build with it!
Here are some of the animations I've created with it to motivate you guys! 😁
If you already tried it out, post the results below 👇


1BusyGuy retweeted

You can now build your own AI Jarvis for free 🤯
OpenJarvis is a personal AI agent that runs locally on your devices 24/7.
No cloud. No subscriptions. Just your own private AI assistant living on your machine. 🚀

There is a new Grok Gallery opening up, for both regular and uncensored work. It only accepts GROK imagine URLs so it’s all from GROK. Interested. Register here. We promote artist and looking forward to GROKs evolution. grokgalley.com pic.x.com/W3DC3t2GHb