

AI/ML Engineer | Co-founder https://xitter.cf/t.co/XPoYOHa7wv | Building AI infrastructure | 32x RTX 3090 GPU Cluster
LAB32
Joined October 2009
- Tweets1.2K
- Following1.6K
- Followers8.1K
- Likes4.3K




Pinned Tweet
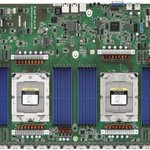
Finally finished building my AI datacenter! 🚀
32x3090s across 4 servers (8 GPUs each), all connected over InfiniBand.
The whole setup is solar-powered with a massive battery bank and generator backup.
More technical details and benchmarks coming soon.


It's huge! I assume that's more than 30 PB of actual traffic just from Hugging Face? Am I close to the truth @ClementDelangue?

Alibaba's open-weight models have accumulated more than 3 billion global downloads in the past six months, eclipsing Meta, Alphabet and domestic peers to become the world’s No. 1 artificial-intelligence model bloomberg.com/news/articles/…


Interesting release. A potentially faster alternative to Qwen3.6-35B, especially for high-volume agentic workloads.


Nice. Now @sama, your move! We’re waiting for GPT-OSS v2.

Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats to @alexandr_wang and the MSL team for all your great work on these models.
Capable safety models with a small footprint.

🛡️Introducing Shieldstral, Mistral’s 3B open-weights model for content safety that can be deployed on-device 🧵 mistral.ai/news/shieldstral

DeepSeek-V4-Flash looks very good for its size. I think the updated V4-Pro will beat Fable on most benchmarks.

🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: api-docs.deepseek.com/quick_…

Huge win for the open AI community. 🌒

Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

😍 Love this initiative!
This is the right direction for the future of AI.

AI security advances when the industry builds in the open, together.
We're introducing the Open Secure AI Alliance with industry leaders to develop new techniques and tools to safeguard software and agents.
By sharing models, tooling and research in the open, we can broaden the community of defenders.
Learn more about the founding members’ contributions: nvda.ws/4pD8Fc5

ALT Logos of various companies including Adobe, Cisco, and Microsoft.
Curious to try this.

Today we're releasing Laguna S 2.1, our most capable model to date.
It's a 118B total parameter Mixture-of-Experts model with 8B activated per token, a context window of up to 1M tokens, and thinking and no-thinking modes.
Capable enough to hold its own against models many times its size. Small enough to run on a single @NVIDIAAI DGX Spark.
Laguna S 2.1 is fully open under OpenMDW-1.1, with weights available today on @huggingface
poolside.ai/blog/introducing…
Same model ID (claude-opus-4-8), same prompt (你是谁?), two endpoints:
OpenRouter: "I'm Claude, by Anthropic"
Anthropic API direct: "I'm Qwen, by Alibaba"


Great news! Looking forward to seeing how well this runs on older Instinct GPUs. Time to dust off my MI50. 🚀

Introducing Unsloth for AMD 🚀
You can now train & run LLMs on your AMD hardware
• We collaborated with AMD to enable you to train & run 500+ models on AMD GPUs
• Works on Windows, WSL, Linux
• Train Qwen, Gemma on 3GB VRAM
GitHub: github.com/unslothai/unsloth
Works on Radeon, Instinct, Ryzen and data center GPUs with up to 2× faster with 70% less VRAM and no accuracy loss via our custom Triton kernels and math algorithms. We also support optimized ROCm builds for GGUF & Safetensors inference.
Unsloth is an open-source local UI for faster LLM training and inference, with tool-call healing, code execution, secure web search, remote APIs, and HTTPS deployment. Connect local models to Claude Code, Codex agents and run the latest Kimi, GLM, DeepSeek, Qwen3.6, and Gemma 4 models.
🔗Blog + Guide: unsloth.ai/docs/basics/amd

This summer is hot for new models 🔥 Can't wait to run them locally.

Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:qwencloud.com/pricing/token-…
China:platform.qianwenai.com/prici…

Couldn't have said it better.

I can confirm that Kimi K3 is very strong at frontend development.
For me, it performs better than Opus 4.8.

Big news: Kimi-K3 by @Kimi_Moonshot is now #1 in the Frontend Code Arena with 1679 pts, surpassing Claude Fable 5.
This is a 17-place jump from Kimi-k2.6 (#18 -> #1).
In Frontend, Kimi-K3 ranked #1 in 6 of 7 domains: Brand & Marketing, Reference-Based Design, Data & Analytics, Consumer Product, Simulations, and Content Creation Tools, landing #2 only in Gaming behind Fable 5.
The full model weights will be released by July 27.
Congrats to the @Kimi_Moonshot team on this major milestone!


