

Mission Control for Your Data Pipelines
Global
Joined March 2021
- Tweets332
- Following117
- Followers273
- Likes82





Pinned Tweet
We relaunched our product, we revamped our brand. But why did this happen?
Our CEO Hung shares why a #ModernDataOpsCloud was necessary to solve the challenges in the data space.
Learn more about Y42's changes here: y42.com/blog/why-first-moder…
youtu.be/wDR02B8x0z8

𝐖𝐞'𝐫𝐞 𝐞𝐱𝐜𝐢𝐭𝐞𝐝 𝐭𝐨 𝐮𝐧𝐯𝐞𝐢𝐥 "𝐏𝐲𝐭𝐡𝐨𝐧 𝐈𝐧𝐠𝐞𝐬𝐭”, 𝐨𝐮𝐫 𝐥𝐚𝐭𝐞𝐬𝐭 𝐢𝐧𝐧𝐨𝐯𝐚𝐭𝐢𝐨𝐧 𝐝𝐞𝐬𝐢𝐠𝐧𝐞𝐝 𝐭𝐨 𝐞𝐧𝐡𝐚𝐧𝐜𝐞 𝐝𝐚𝐭𝐚 𝐢𝐧𝐠𝐞𝐬𝐭𝐢𝐨𝐧 𝐩𝐫𝐨𝐜𝐞𝐬𝐬𝐞𝐬.
With Python Ingest, you can:
🚀 implement custom ingestion logic,
🚀 remove boilerplate code to load data into your data warehouse, and
🚀 get standardized metadata, lineage, and documentation out of the box.
Read on in our announcement post: y42.com/blog/announcing-pyth…
As we embrace the challenges and opportunities of 2024, it's crucial to stay ahead in the data world. We sat together with Madison Schott to discuss key industry trends and make 5 data predictions for 2024. 🔮
Read on in our blog post: y42.com/blog/5-data-predicti…

We're introducing a new stateful, declarative approach for data pipelines. Ensuring auditable, simple, standardized code with full traceability and zero compute cost for changes. Read on here: y42.com/blog/stateful-data-a…

Sharing some best practices for working with dbt and BigQuery. Hands-on insights from a data practitioner. Discussing relevant BigQuery functions, table partitioning, and materialization strategies.
Check it out: y42.com/blog/dbt-bigquery-be…

Calling all data enthusiasts! 🧑💻 Say hello to Virtual Data Builds by Y42! Unify logical changes via Git, materialize code changes, and handle operational changes in a single structure - environment management for Data simplified! 💜 Detailed announcement in the comments.
Read our Founder's detailed announcement here: linkedin.com/posts/hung-dang…

Data teams keep making the same mistakes over and over again. Why is that? 🤔
Here’s our guess:
❌ Lack of reflection and learning
❌ Ineffective collaboration
❌ Inadequate documentation
❌ Failure to adapt to change
Learn more here: y42.com/blog/data-team-chall…

#Readoftheweek 🤓👇🏼
Poor data quality undermines all the time and effort you put into your work.
❌ Your systems don't matter
❌ How robust your pipelines are doesn't matter
Learn more about the importance of #dataquality for #dataengineers here: y42.com/blog/data-quality-fo…

Want to improve your company's #datagovernance program this year?
👉🏼 Check out our #readoftheweek to learn how you can implement data governance best practices into your day-to-day work:
y42.com/blog/data-governance…
Thank you to everyone who joined our #webinar with @redsift and @googlecloud on the benefits of automating your data pipelines.
👉🏼 If you missed out on the webinar, you can watch the recording here: y42.com/event/data-operation…
Part of a data team's responsibility is improving a company's overall #dataliteracy.
Start sharing #datacontent with business users, beginner data analysts, or anyone in between.
Here's our pick for their perfect #readoftheweek: y42.com/blog/data-pipeline/?…

Have we already mentioned that we have a #webinar coming up? 👀
✅ Learn how to manage increasing data needs and requests.
✅ Learn how to automate your data infrastructure as your company grows.
👉🏼 Sign up here: y42.com/event/event-page-red…
Do you know the difference between #datamanagement and #datagovernance?
👉🏼 Check out our #readoftheday to learn the differences, similarities, and use cases of data management and data governance:
y42.com/blog/data-management…

Looking for an insightful read to wrap up the week? 🤓
How about discovering the power of #Git workflows and branching strategies to #versioncontrol your #dataproducts?
Check out our recommended #readoftheweek here: 👇🏼
y42.com/blog/version-control…

Discover the power of automated #datapipelines!
Join Eliott Sacau (@redsift ), Jelena Mijuskovic (@Google ) and Ba Khai Tran (@y42dotcom ) in our upcoming #webinar!
👉🏼 Sign up here: lnkd.in/eXMaE5Nx


Here are 3 steps to follow if you want to implement #dataownership within your organization.👇🏼
1️⃣ Get an overview of all your data assets by making an inventory
2️⃣ Determine domain experts per data asset
3️⃣ Implement a data catalog for better traceability
👇🏼 This is what you need to do to avoid not knowing when a data model failed. 👇🏼
Test intermediate and core models too! 💡
If you don't, you let errors pass onto your final model and have to check all previous models to identify the culprit. 🫠
#datatesting #datamodeling

Types of #datagovernance frameworks:
✅ Command and control framework
✅ Traditional framework
✅ Non-invasive framework
Which one should you choose? That will depend on your company goals and team structure.


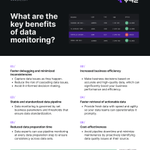
Here are the 6 key benefits of #datamonitoring.👇🏼
1️⃣ Faster debugging and minimized inconsistencies
2️⃣ Increased business efficiency
3️⃣ Stable and standardized data pipeline
4️⃣ Faster retrieval of actionable data
5️⃣ Reduced data preparation time
6️⃣ Cost-effectiveness
