

Research Scientist @GoogleDeepMind. RLHF, Agentic LLMs with humans. @dtu_delhi @ASU
Mountain View, CA
Joined March 2016
- Tweets384
- Following603
- Followers546
- Likes1.5K




Mudit Verma retweeted

Great to see the jump from Argon to Carbon on FrontierCS 2! Excited for people to all use Carbon in Antigravity soon.

Gemini 4 Carbon scores 53 FCI and 54 pass rate on FrontierCS 2. It’s an impressive jump from Argon to Carbon in just a few weeks. We also work with @antigravity to improve the evaluation in long-horizon runs. model and harness are co-evolving! 🐱
Mudit Verma retweeted

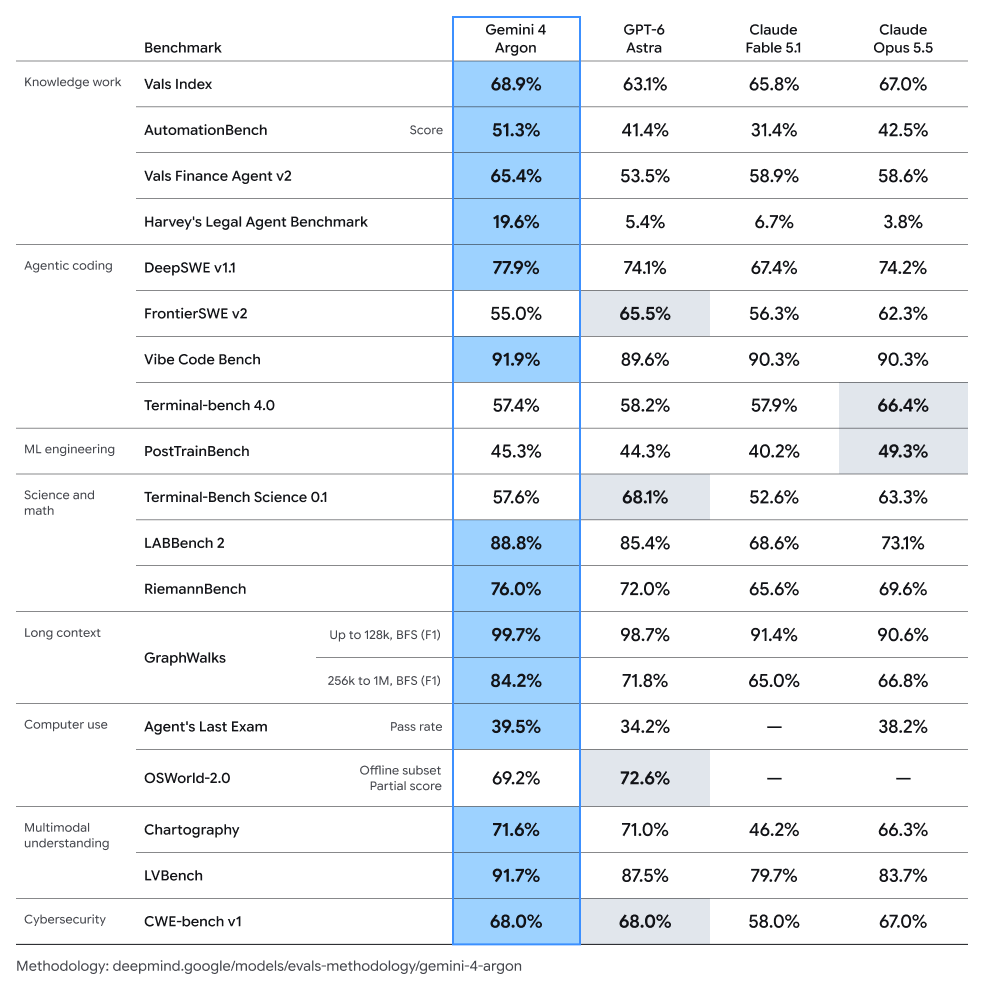
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Mudit Verma retweeted

first they came for our agents,
then they came for our environments

What are RL environments? Are they just evals? There is significant confusion in the community, so here is my opinion: My answer is inspired by Terminal-bench, an elegant framework for creating RL environments, evaluating agents and even training agents.
First, an RL environment is simply a Docker container. It contains three things:
1. A snapshot of the state of the world when a problem happened.
2. A task description and
3. A reward that verifies if the agent has solved the task. Can be using LLM as a judge or run tests.
For example, lets take the 'broken-python' environment in Terminal bench.
The Dockerfile setups the container: Installs Python and intentionally breaks it by removing critical files
E.g. install python and
RUN rm -rf /usr/local/lib/python3.13/site-packages/pip
The task is "There's something wrong with my python- I can't install packages with pip."
The verifier tests if pip works by trying to install a test package.
Now the agent can try anything it wants to fix pip, by writing bash commands, or using any tools available.
(1/2)

Mudit Verma retweeted

Join us at @emnlpmeeting for:
"Tailoring AI: Exploring Active and Passive LLM Personalization" 🎯🧠
To answer, when should LLMs personalize? What role do users play in LLM-personalization?
📅 Deadline Aug. 1
📝 Details in thread 🧵👇
#EMNLP2025 #LLM #AI #personalization
1/5
Mudit Verma retweeted

AI mode in Google Search is starting to roll out to all users in the US today : )
It's the search experience you know, reimagined for the AI era (including a new feature called "Deep Search")!
Mudit Verma retweeted
Today we are rolling out an experimental Gemini Embedding model for developers with:
– SOTA performance on MTEB (Multilingual)
- Input context length of (3K --> 8K) tokens
– Output 3K dimensions
– Support for over (50 --> 100) languages
More details in 🧵
Mudit Verma retweeted

Your feedback on Gemini 2.0 Flash Thinking has been incredible—thank you!
We’ve taken your suggestions and made an experimental update…
Mudit Verma retweeted

Gemini Deep Research is mind-blowing.
Asked it for the Best Software Engineering blogs and it compiled the best of the best from Netflix, Spotify, Meta, Airbnb, Pinterest, Stripe, Square, Github, LinkedIn, Dropbox, Google, Mozilla, Microsoft, Amazon and more!
Here's a link:

Mudit Verma retweeted

It’s been an amazing last couple of weeks, hope you enjoyed our end of year extravaganza as much as we did!
Just some of the things we shipped: state-of-the-art image, video, and interactive world models (Imagen 3, Veo 2 & Genie 2); Gemini 2.0 Flash (a highly performant and efficient foundation model); Gemini-Exp-1206 model (top of the Chatbot Arena leaderboard); 2.0 Flash Thinking (our first ‘thinking’ model, expect a lot more news on this soon - as many of you remember, we pioneered this type of model with AlphaGo, AlphaZero, AlphaProof…); upgrades to @GeminiApp with Deep Research and more, fantastic new NotebookLM features, a new image remixing tool (Whisk); and a series of agentic research prototypes that can help people get things done (Project Astra, Mariner, Jules) all built on Gemini 2.0.
And then on top of all of that, we dropped the world’s most accurate weather prediction model (GenCast), the world’s most advanced quantum chip that performed a computation that would have taken 10 septillion years (Willow - could come in handy for training AI one day!), and it was the honour of a lifetime to receive the Nobel Prize for AlphaFold, which has revolutionised structural biology and is being used by 2 million researchers around the world to understand disease and accelerate drug discovery.
I could not be more proud of all the exceptionally talented teams at @GoogleDeepMind & @Google who have worked so incredibly hard on all these amazing projects. It’s the greatest joy one can have professionally to get to explore the outer reaches of science and human knowledge with such wonderful colleagues.
We’ve been inventing the future of AI for well over a decade now, and we’ll continue to be a relentless engine of innovation. In many ways we’re only just getting started… if you want to be at the frontier of the most exciting scientific and technological journey ever, this is the place to be, come join us!
Mudit Verma retweeted

🎓🧑🎓👨🎓🎓With Dr. Mudit Verma and Dr. Lin Guan (..and their loved ones..) on this lovely day of their @asu graduation! [Mudit @v_mudit visiting from @GoogleDeepMind and Lin @guansuns visiting from @Meta GenAI..]


Mudit Verma retweeted
📢 Check out @sbhambr1 & @v_mudit's pitiless dissection of ReACT think tag claims at the Adaptive Foundation Models workshop today @ #NeurIPS2024. (West Exhibition Hall A; 4:30pm) openreview.net/forum?id=Aj6G…
This makes for a great companion to our main track analysis of CoT Chain of Thoughtlessness (xitter.cf/rao2z/status/186710531…)


📢 ReAct popularized the "Think 🤔" magic by claiming to help LLMs plan by "synergizing reasoning and acting." @v_mudit & @sbhambr1 investigated the claims, and have a thing are two to say about the extreme brittleness of ReAct style prompting. 👉arxiv.org/abs/2405.13966 1/


Mudit Verma retweeted

We’re also introducing a new agentic feature called Deep Research in Gemini Advanced, a research assistant that can dig into complex topics and create reports for you with links to the relevant sources.
Mudit Verma retweeted

Willow, our next-gen quantum chip, is pushing the boundaries of quantum computing. With 5x improved coherence times, we're unlocking new possibilities in error correction and performance.
Learn more → goo.gle/41JmpID #QuantumAI
Mudit Verma retweeted

Gemini-Exp-1206 tops all the leaderboards, with substantial improvements in coding and hard prompts. Try it at lmarena.ai !

Mudit Verma retweeted
Introducing Genie 2: our AI model that can create an endless variety of playable 3D worlds - all from a single image. 🖼️
These types of large-scale foundation world models could enable future agents to be trained and evaluated in an endless number of virtual environments. → goo.gle/4f48y2e
Mudit Verma retweeted

Just downloaded Gemini Live, and I’m absolutely blown away. Speaking directly to AI with zero latency—this voice interaction is the future of consumer AI. Incredible work, @sundarpichai. Truly groundbreaking. Try it immediately: apps.apple.com/us/app/google…”
Mudit Verma retweeted
Massive News from Chatbot Arena🔥
@GoogleDeepMind's latest Gemini (Exp 1114), tested with 6K+ community votes over the past week, now ranks joint #1 overall with an impressive 40+ score leap — matching 4o-latest in and surpassing o1-preview! It also claims #1 on Vision leaderboard.
Gemini-Exp-1114 excels across technical and creative domains:
- Overall #3 -> #1
- Math: #3 -> #1
- Hard Prompts: #4 -> #1
- Creative Writing #2 -> #1
- Vision: #2 -> #1
- Coding: #5 -> #3
- Overall (StyleCtrl): #4 -> #4
Huge congrats to @GoogleDeepMind on this remarkable milestone!
Come try the new Gemini and share your feedback!


gemini-exp-1114…. available in Google AI Studio right now, enjoy : )
aistudio.google.com

Mudit Verma retweeted
AlphaFold 3 model code and weights are now both available for academic use on GitHub.
The golden age of computational science is about to begin!
github.com/google-deepmind/a…

Mudit Verma retweeted

Is your RLHF training too slow? 🦥 Does inefficient LLM generation get you down?
We propose a new paradigm: Asynchronous RLHF! It's faster, more efficient, and achieves the same perf as SOTA methods only improving with scale!
arxiv.org/abs/2410.18252 and we release code too

Mudit Verma retweeted

Transformers can be trained to solve a 132-years old open problem: discovering global Lyapunov functions. New paper on Arxiv (accepted in NeurIPS 2024), with @albe_alfa and @Amaury_Hayat
arxiv.org/abs/2410.08304 1/8
