

Student at @NITRourkela || Not a "x" developer || I write bugs🐛
Rourkela, Odisha, India
Joined January 2022
- Tweets661
- Following192
- Followers122
- Likes505
Pinned Tweet
🤔 Curious about who's behind the scenes crafting all things technical, websites, and digital magic during @hacknitr? Give them a laptop and they are ready to work anywhere. Ladies and gentlemen "The #hacknitr tech team"🤌
Glad to lead the team💪
#hackathon #tech #GoogleDeveloper


What should I read next? Any suggestions? Or how can I do some implementation on this?

Finished reading Inference Engineering by @philipkiely. To make it stick, I built a visual mind map for each chapter, plus figures you can play with: GPU memory, speculative decoding, autoscaling and more.
All here: ashutoshrath.me/notes/infere…
Finished reading Inference Engineering by @philipkiely. To make it stick, I built a visual mind map for each chapter, plus figures you can play with: GPU memory, speculative decoding, autoscaling and more.
All here: ashutoshrath.me/notes/infere…
Season 1 of The Fundamentals of Business by Michael Scott is out. Over 1 billion copies sold.
More than the Bible. It is thick, it is hard to put down, and you will want to finish in one sitting. That's what she said haaaa.
msbof.vercel.app/

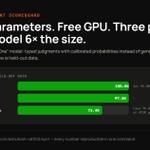
sys1 scoreboard, all on held-out data:
phishing --> 100%
own domain --> 97.5%
typed decisions --> 73.4%
Laya scores 76.6% on that last one with 421M params. I'm at 68M, trained on a free Kaggle GPU.
Getting closerrrrrr........

Spent days trying to fix my model's phishing score.
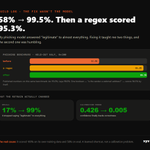
58% accuracy. 17% recall - it answered "legitimate" to almost everything.
The fix turned out to be nothing I expected.

What I'm fixing next:
training on all 4 workflows (7,387 examples, was 2,887)
Platt scaling for yes/no: temperature fixes sharpness, not bias, and bias was my problem
bigger backbone with an MLM head, which my current one lacks

Everything reports a confidence interval now, because I'd been reading noise as progress. At n=500 it was +/-4 points - wider than most changes I was celebrating.
23M params. Laptop CPU. Free GPU.
github.com/ashutosh-rath02/s…

I've released PXR: a Rust no_std runtime that checks actuator commands before driver dispatch. Fixed memory, leases, local fallback, C ABI. MIT licensed, with a runnable demo and reproducible host benchmarks. Firmware feedback welcome: github.com/ashutosh-rath02/p…

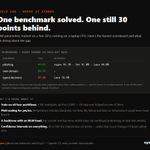
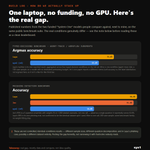
One laptop, no funding, no GPU. Real published numbers vs mine on the same benchmark suite: Laya 76.6%/98.0%, Jev 95.0% (5-question ensemble) vs my 62.6%/58.0%. Not controlled conditions, posting the gap anyway. Mostly data & compute, not idea quality.

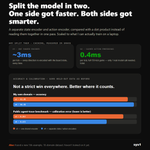
Split the model in two. A separate state encoder and action encoder, compared with a dot product instead of reading them together in one pass.
The payoff: action embeddings don't depend on context anymore, so they can be cached.

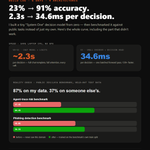
Built a tiny "System One" decision model from zero: 23%→91% accuracy, 2.3s→34.6ms per decision. Then benchmarked it against a public task it had never seen 37% on that, retrained on the benchmark's own train data, got it to 64%. Accuracy went up. Confidence went up too.

Follow-up to yesterday's benchmark reality check (37% on a public agent-trace benchmark my model had never trained on). I pulled TRAIN-only data from that same benchmark's public sources (never touching the actual test/eval split) and retrained.
My model got more confident and more often right on the most-likely answer,but that confidence overshoots against a genuinely split true distribution. On phishing,recall is still only 14.7%,it mostly still says legitimate, and is only very sure on the phishing calls it does make.