Let there be tokens 馃殌
Most inference GPUs are ~70% idle. It's not a kernel problem, or a traffic problem. It's a placement problem.
To prove it, we built an inference service that co-locates models on a GPU.
5 co-located models. 14 days. 2.5B tokens served. $17k/mo saved.
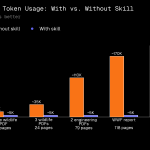
Today, we are launching our collaboration with @nomic_ai to make AI agents more effectively and efficiently understand complex PDF documents.
Nomic's new nomic-layout-v1 model allows your AI agents to parse documents locally, so sensitive documents never leave your machine.


