

The retrieval layer for production AI. Sub-10ms search for voice agents, copilots, and real-time AI.
San Francisco, CA
Joined February 2025
- Tweets132
- Following6
- Followers597
- Likes100





80% of Moss customers use @livekit. 👀
LiveKit handles real-time voice. Moss handles the retrieval.
Together, your agent gets the context it needs on every turn, automatically.
No tool call. No extra roundtrip. No dead air.
Sub-10ms retrieval for voice AI.
→ moss.dev/integrations/liveki…

Your website is still waiting for someone to answer.
It doesn't have to.
Meet the new Founding Agent.
A Voice AI agent that answers questions, talks to visitors, and books meetings.
New portal. More customization. Much easier to manage.
Try it live: moss.dev/foundingagent
What if retrieval didn't need to be another network request?
Load the index into your application.
Query it locally.
Get your context back in milliseconds.
That's Moss.
Your AI shouldn't have to call another server to remember something.
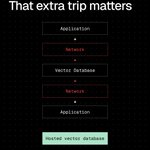
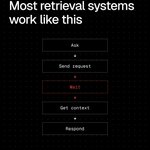
Most RAG setups send retrieval requests over a network.
When you're building something that needs to respond in real time, that extra trip matters.
Here's how Moss handles it ↓

No database network hop.
Sub-10ms retrieval.
Useful for voice agents, copilots and any AI application where response time matters.

AI shouldn't have to wait for its own context.
Read the blog: moss.dev/blog/remove-the-net…

What does AI memory look like at scale?
80,000+ devices.
113M documents every month.
24.8B tokens embedded on device.
Aside uses Moss for local embedding, indexing, and retrieval inside its AI browser.
Here's how they're building it: moss.dev/blog/aside-persiste…

New Moss.
Closer to the application.
Closer to the context.
Faster to the answer.
moss.dev
Moss (YC F25) retweeted

Moss, @usemoss, just crossed 500K+ package installs.
Five months ago I posted about hitting 100K. I remember refreshing the PyPI stats page like it was election night. Every install felt like someone saying "I'll give this a shot."
At 500K, I don't refresh the stats page anymore. Not because I care less. Because the pattern proved itself.
We still haven't run ads. Still no DevRel team. Still no Product Hunt launch. The growth loop hasn't changed since install number one: a developer tries Moss, it works, they tell another developer.
What changed is who's installing.
At 100K, it was individual developers experimenting. Trying Moss in a sandbox. Seeing if the latency claims were real. At 500K, it's teams. A developer brings it in for one project, their team adopts it, and six months later it's in every pipeline they run.
That's the difference between curiosity and trust.
The hardest part of building developer infrastructure isn't getting someone to try your product. It's getting them to keep using it after the demo is over. Every install after the first one from the same team is a vote that it works in production, not just in a notebook.
500K installs. Zero paid acquisition. Same growth loop since day one.
We're just getting started.

Moss (YC F25) retweeted
In December we shipped a feature that zero customers use today.
BYOE. Bring Your Own Embeddings.
At @usemoss, we offer three things:
→ Very fast 𝗿𝗲𝘁𝗿𝗶𝗲𝘃𝗮𝗹
→ High quality 𝗲𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴 𝗺𝗼𝗱𝗲𝗹𝘀
→ A 𝘀𝘆𝗻𝗰 𝗲𝗻𝗴𝗶𝗻𝗲 that keeps your data fresh
But when we entered the market, there was a real adoption friction. Teams had already built pipelines around OpenAI or other known embedding models. Switching meant downstream dependency risks. Custom plumbing could break. Nobody wanted to rip that out just to try a new retrieval layer.
So we built BYOE. Plug in whatever embedding model you're already using. Use Moss purely for retrieval. No migration risk. No friction.
It was the right call. It got developers through the door.
But here's what happened next.
Developers started testing Moss with their own models. Then they tried our default embeddings just to compare. They saw the quality. They saw the retrieval accuracy. They saw what the full stack could do when everything was optimized end to end.
And they never switched back.
Fast forward 8 months. Zero customers are plumbing their own embedding models into our pipeline. Not one. We haven't even heard anyone mention bringing their own models in months.
We built BYOE to remove a barrier. It worked. But the barrier it removed wasn't technical. It was psychological. Developers needed the freedom to keep their existing models to feel safe trying Moss. Once they tried it, the product spoke for itself.
Sometimes the most important feature you ship is the one nobody ends up using.

Glad you had a good time @liviuchircu


How do you actually ship Voice AI in production?
Join us live with Naman Shukla, Founder of Casuro, as we go behind the scenes of Vocal, their AI powered voice interviewer.
We'll cover why they built it, why they chose Moss, lessons from shipping AI in production, plus a live demo and Q&A.
luma.com/aivoiceinterviews

Your model isn't your bottleneck.
Your stack is.
The difference between an AI demo and a production AI system comes down to retrieval, memory, orchestration, infrastructure, and latency.
We broke down the 7 layers of the modern production AI stack ↓
moss.dev/blog/the-production…

Excited to sponsor the YC x Medplum Hackathon organized by @Medplum1
Please join us on Saturday, Aug 1 @ YC

August 1 is for hacking! Join the Agentic Healthcare Hackathon from @Medplum1 x @ycombinator in San Francisco. Signup here: events.ycombinator.com/medpl…

Moss (YC F25) retweeted
10,000,000 production conversation session minutes on @usemoss
Last week we posted about hitting 5M. The week before that, 2M. The week before that, 1M.
1M took months. 1M to 10M took three weeks.

We hosted the Conversational AI Hackathon at @ycombinator last month. 450+ builders applied. Here's what 24 hours of building looked like.
youtu.be/59W5eq02iRU

Moss (YC F25) retweeted
5,000,000 production voice minutes on @usemoss
Not sandbox traffic. Not internal QA. Real production minutes from teams running voice agents with paying customers on the line.
Three weeks ago we were at 1M. Last week, 2M. Today, 5M.
Here's what 5M minutes actually looks like under the hood:
→ Millions of retrieval calls resolved in under 10ms
→ Customers jumping from 300K minutes/month to 100K minutes/day overnight
→ Identical latency at 1x, 10x, and 50x load
→ Zero retrieval failures across every traffic spike
The teams building on Moss are powering voice agents for global enterprises across 100+ countries. When their customers' customers are on the line, a slow retrieval or a missed lookup isn't a bug. It's a broken experience.
We built Moss to be the kind of infrastructure you stop thinking about. It just works. Every scale. Every spike. Every time.
We're just getting started.
