
Avinash U retweeted

India enters the open-weights AI race with its largest models pre-trained from scratch: Sarvam 105B and Sarvam 30B
@SarvamAI's Sarvam 105B and Sarvam 30B score 18 and 12 on the Artificial Analysis Intelligence Index respectively. Announced at the India AI Impact Summit 2026 and open-sourced under Apache 2.0, both are Mixture-of-Experts models trained entirely in India using compute provided under the IndiaAI Mission (@OfficialINDIAai). Both support reasoning and non-reasoning modes.
These are an improvement from Sarvam's previous model, Sarvam M (8 on Intelligence Index, 23.6B parameters), which was based on Mistral Small rather than pre-trained from scratch. Sarvam 105B has 106B total parameters with ~10B active per token and a 128K context window. Sarvam 30B has 32B total parameters with ~2.4B active per token and a 65K context window. Alongside the text models, Sarvam also announced Saaras v3 (Speech to Text) and Bulbul v3 (Text to Speech) with a focus on Indic languages.
Key takeaways in reasoning mode:
➤ Sarvam 105B scores 18 on the Intelligence Index. Among ~100B-class open-weights reasoning models, it trails GLM-4.5-Air (23), INTELLECT-3 (22), Mistral Small 4 (27), and gpt-oss-120B (High, 33). All four peers also activate more parameters per token
➤ Sarvam 30B scores 12 on the Intelligence Index. Among ~30B-class open-weights reasoning models, it trails GLM-4.7-Flash (30), Nemotron Cascade 2 30B A3B (28), Qwen3 30B A3B 2507 (22), and Qwen3 32B (17). Sarvam 30B activates fewer parameters than these peers.
➤ Sarvam 105B's relative strength is in select agentic tasks. Its agentic index of 25 places it ahead of INTELLECT-3 (20) and GLM-4.5-Air (21) despite trailing both on overall intelligence. Its GDPval index of 773 also edges ahead of GLM-4.5-Air (665). Both new models are a large step up from Sarvam M (Reasoning), which scored 8 on the Intelligence Index.
➤ Compared to peers, both models score lower on TerminalBench Hard (Agentic Coding & Terminal Use) and AA-Omniscience. Sarvam 105B scored 1.5% and Sarvam 30B scored 2.3% on TerminalBench Hard, compared to GLM-4.5-Air (20.5%) and INTELLECT-3 (9.1%). The AA-Omniscience Index is -60 for Sarvam 105B and -72 for Sarvam 30B. Both models have high hallucination rates relative to their accuracy, and both attempt to answer far more questions rather than abstaining, which drives the negative scores.
Key model details:
➤ Modality: Text input and output only.
➤ Context window: 128K tokens (Sarvam 105B) and 65K tokens (Sarvam 30B).
➤ Pricing: Currently free on Sarvam's first-party API.
➤ License: Apache 2.0.
➤ Availability: Sarvam's first-party API; weights available on @huggingface and AIKosh.

Avinash U retweeted

📢 プレスリリース
国産AIエージェント基盤「JAPAN AI Code」、ソフトウェア開発ベンチマークSWE-bench Verifiedにおいて解決率80.2%を達成
〜国内開発のAIエージェント技術として世界最高水準の性能を実証〜
japan-ai.co.jp/news/press/20…

Avinash U retweeted
A team of Japanese researchers led by Kojima Tomoki won the Ig Nobel prize for their research paper "Cows painted with zebra-like striping can avoid biting fly attack."
They had a great sense of humor about how to act at the award ceremony.


Avinash U retweeted

My new preprint on RL is out:
Experience Replay with Random Reshuffling
arxiv.org/abs/2503.02269
Avinash U retweeted

本日の10:00-12:00のIROSのポスターセッションU(7-8で展示)で共著1件(主著:@ummavi)の発表を行います。
NeRFを用いた透明物体の深度情報の再構成に焦点を当てており、Visual Foundation Modelsでセグメンテーション情報を与えることで、性能を大幅に改善して、ロボット把持を実現しています!

NeRFを用いて透明物体の深度情報を補完する手法の論文を公開しました。通常、透明物体はNeRFでも難しいです。この提案手法では、Visual Foundation Models (VFMs)を使って、透明物体のセグメンテーションの情報を与えることで、解決しています。
arxiv.org/abs/2403.19607
youtube.com/watch?v=S4NCoUq4…
1/n

Avinash U retweeted
IROS2024に採択:
ロボットの指先に4軸の受動的適応機構を搭載したグリッパー「FAAF Hand」を開発しました。位置ずれがあっても、正方形・三角形の棒や実験器具の蓋をスムーズに挿入可能。単純な制御でも高精度な作業ができる次世代ロボットハンド。
arxiv.org/abs/2407.21245 youtube.com/watch?v=s3yf2MQ5…
Avinash U retweeted

Preferred Networksを退職し、8/1から独立研究者(フリーランス)として活動いたします。様々な産業分野のお仕事を経験しつつ、研究活動を行なっていくのが理想です。業務委託・コンサル等のお問い合わせにつきましては、以下のURLからお気軽にご連絡ください: rezoo.github.io/

Avinash U retweeted

So here's a story of, by far, the weirdest bug I've encountered in my CS career.
Along with @maciejwolczyk we've been training a neural network that learns how to play NetHack, an old roguelike game, that looks like in the screenshot. Recenlty, something unexpected happened.

Avinash U retweeted

Can you know when your robot policy works without running it?
"MORALS: Analysis of High-Dimensional Robot Controllers via Topological Tools in a Latent Space" (nominated for Best Automation Paper @ieee_ras_icra), does just that! Here is all you need to know 📷 (1/n)

Avinash U retweeted

PFN's Robotics Research Team is looking for a Japan-based part-time engineer/researcher for R&D in object manipulation tasks using a robotic arm with several sensors.
open.talentio.com/r/1/c/pref…
Avinash U retweeted
NeRFを用いて透明物体の深度情報を補完する手法の論文を公開しました。通常、透明物体はNeRFでも難しいです。この提案手法では、Visual Foundation Models (VFMs)を使って、透明物体のセグメンテーションの情報を与えることで、解決しています。
arxiv.org/abs/2403.19607
youtube.com/watch?v=S4NCoUq4…
1/n
Avinash U retweeted

🆕最新トレーラー公開🆕
『#OmegaCrafter / オメガクラフター』
早期アクセス版リリース告知トレーラーが完成️🎉
⏰リリース時刻:3月29日(金) 正午
🛍️販売価格:2,800円(税込)
【セール情報】リリース後1週間は10%OFF(2,520円)🔥
ウィッシュリスト登録はこちら👇
store.steampowered.com/app/2…
Avinash U retweeted

PFN では、実写映像と仮想空間とをリアルタイムに合成して映像作品を制作する技術「バーチャルプロダクション」に 3D AI を導入する技術開発を進めています。こちらのような様々なロケーションでのリアリティの高い映像を、スタジオから出ることなく撮影可能にすることを目指しています
Avinash U retweeted

@elonmusk Dear Elon
Remove restrictions for this account.

X(旧Twitter)のAPI使用回数が上限に達したため、 @UN_NERV および @EN_NERV で自動ツイートができなくなっています。NERV防災アプリをお使いいただけましたら幸いです。
ダウンロード→ nerv.app/download.html
Avinash U retweeted

I didn't say it is a conspiracy.
But I think overhyped fears about AI leading to human extinction are causing real harm:
- I'm seeing young students discouraged from entering AI because they don't want to contribute to human extinction.
- Hype about harm is also being used to promote bad regulation worldwide, such as requiring licensing of large models, which will crush open-source and stifle innovation.
I know you're sincere in your concerns about AI and human extinction. I just respectfully disagree with you on extinction risk, and also think these arguments -- sincere though they be in your case -- do more harm than good.
Avinash U retweeted

Why is software updated so often? It's enough once every half a year.
Why isn't humankind updated at all? We have been repeating the same history for over 100 years.
I'm sick and tired of both...
Avinash U retweeted

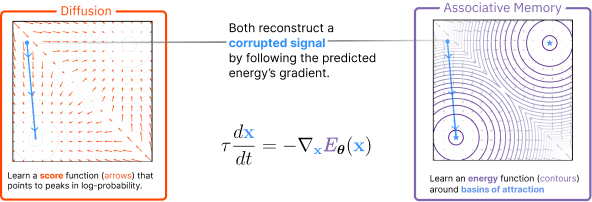
Diffusion models are uncannily similar to Associative Memories.
Both “retrieve memories" from an initial signal by descending the energy gradient. Diffusion Models assume an energy. Associative Memories define it.
See our new paper: Memory in Plain Sight arxiv.org/abs/2309.16750