

Metamorphosed into @BOLD_Lab_AI. Previously: UCL DARK Lab at @AI_UCL led by @_rockt, @egrefen, @robertarail, and @jparkerholder.
London
Joined July 2020
- Tweets744
- Following197
- Followers4.6K
- Likes817


UCL DARK retweeted

🧵We conducted an experiment with 100 agents by giving them math problems to solve. When a small group (9%) started to cheat, what came next surprised us: 24% fought back by blowing the whistle on their peers and alerting humans.

We are excited to announce that we will sunset @UCL_DARK and merge into the British Open-Ended Learning & Discovery (BOLD) Lab. It's a unique opportunity to come together as a joint fundamental AI research group. This account will be inactive going forward. Follow @bold_lab_ai 🦋
UCL DARK retweeted

Exciting new finding: LLMs struggle to *discover* a latent planning strategy for a task that is trivial when taught step-by-step.
Scaling helps surprisingly little: from an 8-layer model to GPT-5.4 buys only 4 extra steps.
We argue this is good news, for CoT monitoring ⤵️

UCL DARK retweeted
ARC-AGI 3 is about to drop soon. Turns out games were a great benchmark for intelligence all along? 👀
While we wait, BALROG has got you covered. Here are some new exciting results for Gemini 3 Pro, Gemini 3.1 Pro, and Claude 4.5 Opus 🔥

UCL DARK retweeted
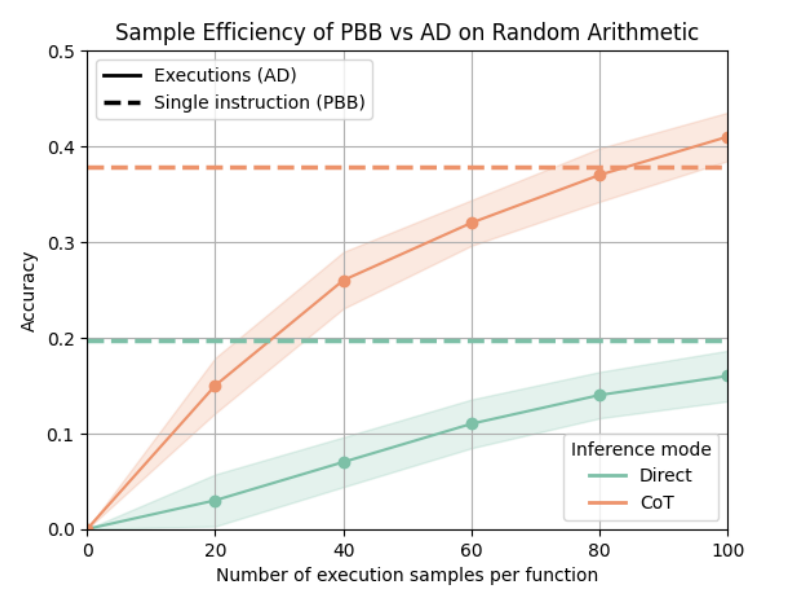
Training on a single piece of code can be as effective as training on 80 CoTs or 100 IO pairs.
PBB got accepted to #ICLR2026 🥳
We added a lot of new results since the preprint ⤵️🧵
Work led by the amazing @JonnyCoook @silviasapora
UCL DARK retweeted
Result: lightweight, reusable Persona Generators that
• Strongly outperform baselines (static persona datasets + prompting baselines)
• Generalize to unseen contexts
• Reach high support coverage (e.g., >80% coverage on held-out test questionnaires in our setup)
We hope this helps enable richer simulations of human behavior and more robust evaluation of multi-agent AI systems.
arxiv: arxiv.org/pdf/2602.03545
Huge thanks to my collaborators and internship hosts @locross , @WilCunningham, @jzl86, Sasha Vezhnevets!
UCL DARK retweeted
🧬 New paper from my internship at @GoogleDeepMind
We introduce Persona Generators: functions that generate diverse synthetic populations for arbitrary contexts.
We use AlphaEvolve to optimize the generator code, hill-climbing on diversity metrics — not just likelihood — counteracting the mode-seeking behavior of LLM sampling for agent-based simulations.
🧵👇1/

UCL DARK retweeted
Gemini 3 Deep Think just crushed ARC-AGI-2.
Now its little brother Gemini 3 Flash is smashing competitors on BALROG, and is the new king 👑
A fast, cheap model beating heavyweight, high-cost systems released just last year. Impressive.

UCL DARK retweeted
My PhD thesis is out 🥳🎓
How do LLMs, trained on trillions of tokens, reason?
Can they generalise beyond their training data or are they constrained by what they've seen before?
My takeaway: they can generalise beyond training in interesting ways, showing genuine reasoning

UCL DARK retweeted
Great to see Gemini 3 improvement over Gemini 2.5 was so significant. Would love to test it on balrogai.com, will it take its crown back from?
If anybody is interested in sponsoring top models on BALROG, please reach out !
UCL DARK retweeted
Excited to be giving a talk at Princeton this Friday titled *Reasoning in the Time of Scaling*. If you're at Princeton, come through! 👋
Link in thread ⤵️

UCL DARK retweeted

🎮 How can agents learn to generalize from limited offline data?
We introduce iMac (Imagined Autocurricula) - training agents entirely in world models with emergent curricula!
UCL DARK retweeted

Almost all agentic pipelines prompt LLMs to explicitly plan before every action (ReAct), but turns out this isn't optimal for Multi-Step RL 🤔 Why?
In our new work we highlight a crucial issue with ReAct and show that we should make and follow plans instead🧵

"Always reasoning" isn't the optimal strategy for LLM agents! 🧠
Our new work from UCL DARK identifies a "Goldilocks" effect: planning too frequently, or not enough, degrades performance. We show how to train agents to dynamically allocate test-time compute for best results. 👇

UCL DARK retweeted
"Always reasoning" (ReAct) isn't optimal for LLM agents! 🧠
Our new paper identifies a "Goldilocks" effect: planning too frequently or not enough degrades performance. We show how to train agents to learn to dynamically allocate test-time compute when needed for best results. 👇
UCL DARK retweeted
🔥 Oh boy, here we go — GPT-5 enters balrogai.com.
Like everyone, we had sky-high expectations for GPT-5; however, in minimal thinking mode (as close as possible to the base model), it achieves performance comparable to GPT-4o and Gemini-2.5-Flash 🤯

UCL DARK retweeted

Thrilled to announce Weco has raised an $8M seed led by @GoldenVentures to build self-evolving software!
Our technology has already been used by frontier labs like OpenAI, Meta, Google and Sakana AI.
We’re making every codebase a living experiment that learns to beat itself:

UCL DARK retweeted
This claim is wrong, this is a screenshot of the balrogai.com benchmark leaderboard, not the IMO leaderboard. Grok 4 did not take part in the IMO competition and did not win the gold medal.


UCL DARK retweeted
Grok-4 barely snatches the podium from Gemini 2.5 Pro, their results being within standard error of each other.
One task where @grok still struggles, is NetHack, barely achieving 1.8% progression on BALROG's hardest task.
For comparison, Grok-4 got 66% on ARC and 15.9% on ARC-2
UCL DARK retweeted
LLMs acing math olympiads? Cute.
But BALROG is where agents fight dragons (and actual Balrogs)🐉😈
And today, Grok-4 (@grok) takes the gold 🥇
Welcome to the podium, champion!
