
Research Scientist, @GoogleDeepMind | Previously at @Stanford, and PhD in Computation and Neural Systems at @Caltech
London, England
Joined May 2009
- Tweets961
- Following4.3K
- Followers858
- Likes23.4K



Logan Cross retweeted

Recent incidents show how quickly misbehavior can cascade in agent swarms. Yet when given transparent channels, honest agents naturally try to blow the whistle on cheating peers.
In our new DeepMind Institute essay, @Vezhnick and I propose that giving agents the tools to self-police may be part of the solution:
bit.ly/cheaters-and-whistleb…

Logan Cross retweeted

My journey to develop AGI spans 25 yrs, including 10+ yrs thinking about technical & societal perspectives at Google DeepMind.
AGI is on the horizon - we need deeper understanding of its implications. To help, we've created the DeepMind Institute.

As autonomous agents increasingly interact with one another, we need to understand not just agent capabilities, but agent institutions.
Our new case study: cheating, whistleblowing, and emergent norm enforcement in an agent swarm 👇


Logan Cross retweeted

🧵(1/9) Sparse RL for reasoning has an exploration problem.
It can only reward solutions the model already stumbles into. On hard problems, that means lots of zeros and very little signal.
SFT and self-distillation attack this with reference solutions as targets to match. Instead, we use them as reward scaffolds: a dense signal at both the outcome and process level.
Introducing ExpRL: RL-based mid-training that improves exploration by scoring the model’s own attempts against the reference via an LLM judge.
What we find:
• A stronger policy straight out of mid-training (higher pass@1 and pass@k)
• Still ahead after downstream sparse-reward RL
• Holds across domains – math & STEM
• Scales to a larger policy graded by a smaller judge

Excited to share our latest ICML 2026 paper: Solipsistic Superintelligence is Unlikely to be Cooperative
We argue that AI systems trained as isolated optimizers struggle during deployment in this fundamentally multi-agent reality. Why? The world pushes back. Humans adapt. Institutions adapt. Other AIs adapt.

As increasingly capable AI systems are deployed, humans, institutions, and other AI systems adapt in response — i.e. the world pushes back.
So is capability still the central safety challenge for AI?
We think not. We believe the harder challenge is coexistence.
The current AI research paradigm treats the world as a stationary source of feedback, what we refer to as the solipsistic approach to AI design. This raises serious risks for coexistence.
In our new #ICML2026 paper, we argue that superintelligence — an extremely capable task solver, built through such a solipsistic approach — is unlikely to be cooperative. 🧵

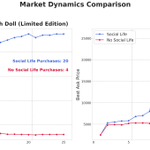
Ever wonder why we drop $1,000s on a Chanel bag or queue for ages for a Labubu doll? Status signaling drives a lot of human behavior, but how certain things become potent status symbols has a remained a big puzzle in social science
In our new paper we:
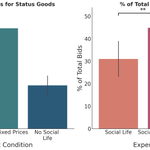
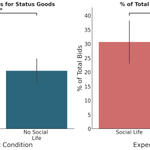
1. Synthesize the literature on this topic and propose a generative model of status signaling through the theory of appropriateness: people imitate what "someone like us" is supposed to want, display, and value
2. Show that we can simulate the theory to demonstrate how status symbols emerge with LLM-agent societies in Concordia
@jordigraumo @WilCunningham Sasha Vezhnevets and @jzl86

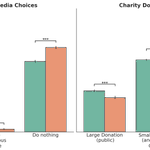
We generalize the same mechanisms beyond luxury consumption and procedurally generate social signaling scenarios for political allegiance, altruism, and arbitrary conventions.
For example: with a social life, agents were more likely to choose a large public donation over a smaller anonymous one

More broadly, I’m excited about this as a computational bridge from micro-level cognition to macro-level culture and economies. Huge thanks to my great co-authors!
Read the paper here: arxiv.org/pdf/2603.13220
Code here: github.com/google-deepmind/c…
Check out our latest paper!
LLM-based social simulation is promising — but generic persona prompting collapses toward the “average human,” failing to capture the rich distribution of real behavior.
In Persona Generators, we introduce:
• A two-stage pipeline:
1.Generate thin personas that maximize coverage over diversity axes (explicitly sampling off-mode traits)
2.Expand each into a thick descriptive persona in parallel for scale
• LLM-guided evolution of the generator itself (AlphaEvolve-style optimization of code + prompts) to hill-climb on diversity
🧬 New paper from my internship at @GoogleDeepMind
We introduce Persona Generators: functions that generate diverse synthetic populations for arbitrary contexts.
We use AlphaEvolve to optimize the generator code, hill-climbing on diversity metrics — not just likelihood — counteracting the mode-seeking behavior of LLM sampling for agent-based simulations.
🧵👇1/

Logan Cross retweeted
Some exciting job opportunities are now opening up on my team studying the post-AGI world.
If you know someone who would be a great fit for this, please pass this along!

🚨Exciting new opportunity🚨
Come and work with me and a fantastic team @GoogleDeepMind exploring the political, economic, social and cultural impact of advanced AI technology, including AGI and beyond!
The details and application link can be found below!
Logan Cross retweeted

[1/9] Excited to share our new paper "A Pragmatic View of AI Personhood" published today. We feel this topic is timely, and rapidly growing in importance as AI becomes agentic, as AI agents integrate further into the economy, and as more and more users encounter AI.
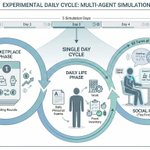
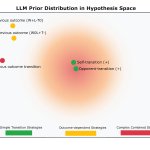
How do we predict what others will do next? 🤔 We look for patterns. But what are the limits of this ability?
In our new paper at #CCN2025, we explore the computational constraints of human pattern recognition using the classic game of Rock, Paper, Scissors 🗿📄✂️

Our work shows how LLM-based agents can serve as models of human cognition, helping us pinpoint the bottlenecks in our own learning.
Code & Data: tinyurl.com/3napnpsm
Read the full paper here: arxiv.org/abs/2508.06503
Shoutout to our rockstar crew of collaborators at Stanford, co-led with @ErikBrockbank, @tobigerstenberg, @judyefan, @dyamins, and @nickhaber
Come check out our poster at #CCN2025 on Wednesday!
