







Synthesia - AI Video Creation Platform: synthesia.io/
+ digital twins of real actors
+ 70+ diverse AI avatars
+ exclusive AI avatar for brands
+ 65+ languages & accents
+ 50+ video templates
#SynthesiaIO
1
77
Lensa - Image Editing App: prisma-ai.com/lensa
-> Magic Correction, Backgrounds, Filters, & FX
Prisma - Transforming Photos into Color Paintings:
prisma-ai.com/prisma
-> 700+ Art & Portrait Styles
#Lensa #Prisma #AI #Filters
89
Google AI - Parti: parti.research.google
"The 20B model especially excels at prompts that are abstract, require world knowledge, specific perspectives, or writing & symbol rendering."
+ Pathways Autoregressive Text-to-Image model
+ ViT-VQGAN, Lingvo, GSPMD, PartiPrompts (P2)

74

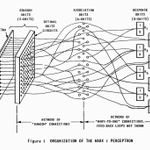
Schmitt: ‘Blueprints for Intelligence’ (2022):
philippschmitt.com/blueprint…
"Instead of projecting onto a metal humanoid, a poetic reading of metaphor & symbolism in AI diagrams prompts us to consider how their creators think about cognition."
#NeuralNets #Perceptron #LeNet5 #AlexNet

1
PromptHero: prompthero.com/
"Search millions of art images by AI models."
+ DALL-E, Stable Diffusion, & Midjourney
Prompt Guide - Sampling Methods:
+ DDIM, Euler, DPM2, HEUN, LMS, DPM_adaptive, & PLMS
+ DPM_fast: "random variety"
+ DPM2 & Euler_a: "photorealistic & clear"
Rocket Content: "Our writers go through extensive training to use the latest AI writing & SEO tools transforming themselves into Cyborg content creators."
jasper.ai/?fpr=typehost
The New Content Engine:
JasperAI, SurferSEO, MarketMuse, Grammarly, Copyscape
#freelance #copywriting

1
Cloudflare Pages: pages.cloudflare.com/
"A JAMstack platform for frontend developers to collaborate & deploy websites."
+ Cloudflare Workers, Edge Network, & Git Integration
+ Support React, Vue, Gatsby, & Hugo
+ HTTP/3, QUIC, & Image Compression
+ Up to 115% Faster Performance
Deploying a 1.3B GPT-3 Model with NVIDIA NeMo Megatron:
developer.nvidia.com/blog/de…
"An end-to-end GPU-accelerated framework for training & deploying transformer-based LLMs up to a trillion parameters. Available in Open Beta, allowing you to train & deploy LLMs using your own data. "

1
TypeHost retweeted

We proposed UPainting to unify simple and complex scene image generation. The model integrates cross-modal guidance into a text-conditional diffusion model. UPainting outperforms other models in caption similarity & image fidelity. More details: upainting.github.io/

VentureBeat: "2022 - The Year of Generative AI":
venturebeat.com/ai/how-2022-…
"Contrastive Language-Image Pre-training (CLIP) became pivotal in text-to-image generators. CLIP + diffusion were used in OpenAI’s DALLE-2 to generate high-resolution images with stunning detail & quality."

1
Easily Accessible Text-to-Image Generation Amplifies Demographic Stereotypes at Large Scale (2022):
arxiv.org/abs/2211.03759
"The amplified stereotypes are difficult to predict & not easily mitigated by users or model owners. Their mass deployment is cause for serious concern."
Photopea: photopea.com/
"Free online editor supporting PSD, XCF, Sketch, XD, & CDR formats. (Adobe Photoshop, GIMP, Sketch App, Adobe XD, & CorelDRAW)."
Pixlr: pixlr.com/
"Photo editor, animation, & design."
+ Photomash Studio, Collage, Filters, & Templates
Imagen Video: imagen.research.google/video…
"Generates high resolution videos with Cascaded Diffusion Models: 1280×768 pixels @ 24 frames per second."
+ T5 Text Encoder
+ Video Diffusion Model
+ Temporal Super-Resolution (TSR)
+ Spatial Super-Resolution (SSR)
+ Video U-Net Architecture


Stable Diffusion Tutorial: Run Dreambooth in Gradient Notebooks: blog.paperspace.com/dreamboo…
"fine-tune & personalize any text-to-image model that encodes a unique identifier that refers to the subject"
-> Stable Diffusion Web UI
-> Gradient Notebook Runtime
-> .ckpt file #Dreambooth
1
Phenaki: phenaki.research.google/
"Generating videos from text is challenging due to high computational cost, variable video length, & limited availability of text-video data. Phenaki creates coherent long-form visual stories from a chain of prompts w/resolution @ 128x128 pixels."

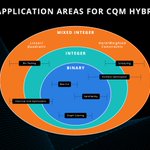
D-Wave Quantum Proof of Concept (QPoC):
aws.amazon.com/marketplace/p…
"explore selected optimization use cases through detailed problem discovery, problem definition, development of an initial prototype solution, & testing with representative sample data."
$QBTS dwavesys.com/

TypeHost retweeted

The @Gradio Demo for Naruto text to image is out on @huggingface Spaces by @LambdaAPI
demo: huggingface.co/spaces/lambda…
