

Founder, @DaywardAI. I help companies position and explain their AI, and I build things with it. 22 years at Apple. Not investment advice.
San Jose, California
Joined December 2006
- Tweets5.6K
- Following488
- Followers21.5K
- Likes7.5K




Todd Dailey retweeted

Just spent the last 7 days on the front lines of the vulnpocalypse fending off an active cyber attack on one of our products.
Some thoughts:
- Software factories are going to be required equipment for everyone. There’s just no way to keep up with the pace of highly automated adversaries without one.
- We were lucky because we had spent the last few months getting our software factory running well. It is nice to have for product development but proved to be absolutely essential this week.
- At the minimum you need to have a coding server in the cloud pre-provisioned with read only access to all your logs and all the services you depend on for observability. With that in place you are a prompt away from reasonably good situational awareness, ongoing monitoring with loops, and ability for coding agents to validate fixes against your actual, observed attack patterns.
- Shared coding server also unlocks multiplayer incident response where everyone can see every session and jump in as needed. Sharing session links that can be forked is much higher bandwidth than re-explaining things.
- You don’t need to be Ramp/Stripe/Uber scale to have a working software factory in the cloud. We are a team of 3. Ours is built with an @opencode server (thanks @thdxr!), a forked version of compound engineering optimized for automated workflows (thanks @kieranklaassen!) and a multiplayer agent in slack that handles crons (we have our own harness but pick your favorite here).
- To get our software factory up and running well, we had to stop all new product development for ~6 weeks and just focus on getting the validation systems working that enabled us to reliably shipping PR without human code review. This felt very painful in the moment but was totally worth the eventual speedup in velocity.
- KYC for @AnthropicAI & @OpenAI cyber programs is now easy and quick (at least for defensive access), but a day felt like a lifetime this week. Submit your app now before you really need it.
- Getting Mythos access unlocked a deeper level of analysis that helped us shift from reactive mitigation to proactive patching. Wish we had done this a few weeks earlier. Get started now!
Todd Dailey retweeted

This is my final setup (probably) for the next few months. (I already posted this once, but an agent deleted it by accident)
A 15U 10-inch rack with:
4 Sparks (NVIDIA GB10), 128 GB each
2x ASUS Ascent GX10
1x Gigabyte AI TOP ATOM
1x Lenovo ThinkStation PGX
Mac Studio M5 Ultra, 256 GB, my new workstation
Next to it:
System A: RTX 5090 32 GB, Ryzen 9 9950X, 96 GB RAM
System B: 2x RTX 5060 Ti 16 GB, i7-12700K, 32 GB RAM
MacBook Air 13-inch M4, 16 GB
I run local AI on this rack at home and post the real outputs and numbers here on X.
Until now my only workstation was the 16 GB MacBook Air. I kept switching between the standing desk (right in the last photo) and the main desk (left).


Todd Dailey retweeted

Wherever you are, what ever you do, please realize how blessed we all are to be alive today!
Todd Dailey retweeted

Linux on the M6 Mac Mini, Day 6 - GPU is up!
Many of you noticed in yesterday's screenshot it used software rendering. I'm excited to share Omarchy on the M6 now utilizes the GPU.
Almost all the drivers are done, and I'll be starting on the Apple Neural Engine bring-up soon.


Todd Dailey retweeted
I could not run to this fast enough

Introducing free People Data for ChatGPT & Claude.
Give your AI agents access to 270M+ company & people records in Alexandria.
Get 1,000 free credits a month to build prospect lists, find work emails, & research job history with the Firecrawl plugin.
firecrawl.dev/alexandria/cat…
Todd Dailey retweeted

🚀 AiOS SF is coming up this Tuesday! Here's what we've got lined up:
@twid (ex-Apple): Behind-the-scenes stories from Apple Intelligence and the future of on-device AI.
@jacobx (SwiftUI co-creator): Managing the App Store with AI in @bitrig .
@ronaldmannak (founder of @PicoGPT): Running one massive LLM across multiple Macs using Thunderbolt 5 and Swift.
@francedot (founder of @trycua): Infinite Desktops Without Renting a Cloud — giving AI agents their own isolated desktops, with a live demo of Cua Spaces.
Expect real demos, technical deep dives, and great conversations with fellow Apple and AI enthusiasts.
AiOS is sponsored by @convex
See you Tuesday! 🚀
luma.com/bz3gmi63

Todd Dailey retweeted

making home devices and datacenter servers, across different architectures and environments, connect directly to each other across the Internet, to run parts of a single frontier-level model with almost a trillion parameters, and to still be able to operate as a single giant mind at the same time, while respecting all the machines and their resource optimization - is the most challenging software and UX problem I have ever come across, despite spending years on it from many different perspectives 👨💻
ps: consider previously we built:
- both centralized and fully peer-to-peer "single model on a single machine" inference network (first + largest)
- gossiping agent swarm learning collaboratively on such a network (first + largest)
- distributed training on consumer machines of a basic model (largest such run, but for a 0.5B model)
- and also decentralized consensus amongst machines/distributed timestamp server/blockchains (3rd largest set of unique full nodes at one point in testnet amongst such networks)
... and that's not to mention distributed database, compute workloads, and N number of other such tasks
it's led to the @HyperspaceAI CLI being the most advanced distributed AI system of it's kind on the planet already.
still we are in early days. but the hope is, cracking these puzzles now inspires for the future..
@grok validate the claims mentioned here
pool.hyper.space

Todd Dailey retweeted

There’s a “Why do we need this?” question here and Apple’s video doesn’t answer it. You need to think you want it if you’re going to buy it. And even if you already had a HomeView set up, I’m not sure how often you’d use it instead of your phone, or just talking to it like a screenless HomePod.
daringfireball.net/2026/10/h…

Todd Dailey retweeted

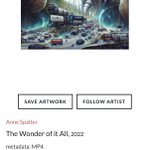
🖥️ @annespalter ’s digital work carries a painter’s eye into technological landscapes. Places that feel both familiar and slightly impossible. She once described working with digital video as feeling more like painting than working with oils, with composition and colour remaining central.
From her digital work in the early 1990s to later experiments with AI, her fascination with the modern landscape has remained a connecting thread. Across her practice, highways and technological structures sit alongside science fiction imagery, surreal desert forms, and mythic animals: worlds where nature and technology seem to merge.
It’s digital art that still thinks in the language of landscape painting, just with more portals.

Todd Dailey retweeted

In case like me you’re wondering how you can fit a trillion parameters (usually $500k of datacenter compute, 4xB300) on $40k of consumer hardware
- Model: 816B params, 42B active
- Quant: nvfp4 (493 GB)
- Mac studio: 512 GB unified RAM, unreleased model, top consumer model is 64 GB right now
- Parallelism: TP=2, weight/attn sharding over both machines, Thunderbolt rdma
- Concurrency: 1 request, memory bandwidth bound (so flops don’t matter), ~1.2 TB/s/GPU versus the 8 TB/s/GPU on Blackwell
so it’s not really a practical or cost-effective solution at unit prices (low batch size), but it does run at all, which is pretty neat

Muse Spark Open -- weights releasing today -- runs great on new Mac Studios thanks to work with @johnternus and Apple.

Todd Dailey retweeted
Tried @typesafeai’s jev 1.14 preview on my doorbell cam’s alert-to-Discord pipeline. My old setup: Gemma 4 26B describes the frame, then DeepSeek V4.1 Flash writes the caption. It caught only 14 of 23 people in recent motion events and missed the mail carrier. Asking jev “is a person in this frame?” across 4 frames of each event got all 23 in a test, with zero false alarms, in about 200 ms. (!)
The new jev Box API then crops to the person, so Gemma can describe them far more reliably (21/23, up from 16).
Concept to live in less than an hour. This replaces a LOT of AI calls and bounding box tools. The jev call costs about $0.00008 per event. (!)
Things are changing so fast. 🚀🚀🚀

ALT an illustration of the jev model catching a face. it says 23 of 23, a tiny fast judge catches every visitor at the door and boxes them in, and show a mail person handing mail to a robot.

Todd Dailey retweeted
I spent 48 hours in SF hanging out with billionaires, data labs and AI founders and execs running $1B to $100B companies.
My observations:
1. Sooo MANY stories of data brokers making like $2M a WEEK selling company data to labs. I can't tell if it's the beginning or a bubble, and I kept wondering which niches are left. Digging into it actively.
2. At dinner, someone asked the table, "If a new model drops next month, does your company get better or worse?" HALF the table went quiet! I think that's the best question to ask about any AI startup right now.
3. The bar people talk about now is hitting $1B in revenue in 12 months (I guess that's the new unicorn?). What I didn't hear much about is retention. AI revenue can come in fast and leave fast, and I think we're going to see a lot of stories of AI companies with huge revenue and terrible retention.
4. It's pretty clear we're living through the reinvention of the computer. The model is the CPU, the harness is the operating system, and skills and plugins are the apps. Thinking about it that way makes it easier to see where the whitespace is.
5. We're maybe 12 months from an agent that can watch you work for a week and then do your job without any instructions. The screen recording plus agent memory plus local model combination makes this possible right now.
6. Agent harnesses feel like the new GPT wrappers, in a good way, especially vertical ones. The best teams I talked to treat the model as swappable. One founder walked me through routing different models to different jobs: one for taste and visuals, a cheaper one for the everyday stuff, another for text.
They use prompts they can move across models over fine-tuning, and A/B test the output on what users actually do with it: do they edit it, export it, share it? A vertical harness is basically four things: the connectors for that industry's data, evals written by people who know the work, rules for what the agent can and can't touch, and a clean screen for a human to review. The model is maybe 20% of it.
7. There's a lot of reverse engineering going on/cloning going on more than I've ever seen. People are decompiling software and rebuilding it with agents, and someone showed a suite of like 10 apps that are worth $5B+ each all that he cloned open source. Me and everyone are still thinking through what it means when software gets this easy to copy.
8. My guess is the value moves to data. If the software can be rebuilt quickly, what's worth paying for in a legacy SaaS company is the years of customer data and workflows inside it. Some SaaS companies are secretly data companies.
Gets me thinking about how do you truly value data for this saas companies? Like if we were buying these dying saas companies at 2x ARR before (as example), maybe there is a better metric. Idk, just thinking out loud here.
9. It feels like a good chunk of legacy software won't make it to the agentic era, especially anything built around people clicking through a lot of screens.
10. Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP. Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!
11. A lot of founders are building the basic building blocks for agents: APIs, data layers and tools. Some of the companies I saw barely have a UI because the main user is an agent. I really believe the startups that build primitives to this agentic era will do extremely well. Building blocks is the best way to think about it.
12. Labs can get plenty of training data, but it's harder to get real examples of agents failing inside companies. Whoever has those logs has something valuable.
13. Someone running a big consumer company told me the next fight is over memory. The model that remembers the most about you wins, and the smartest model matters less than people think.
14. Physical AI came up a lot. Astra I think was the first model that got people into AI can actually do CAD, and I think a lot of people are thinking what does vibe manufacturing really look like. The line I keep thinking about came from a robotics founder: the hardest problems in AI are deployment problems now, not research problems. Their robots work on their own, call a human when they get stuck, and every one of those calls becomes training data.
15. Cybersecurity companies are having a moment and are actually cool companies to build now, especially the ones that clean up after a breach. Every agent with access to your systems is a new door into your company, and a lot of those doors were left open.
16. Some startups are worth more dead than alive now. A shutdown company with 5 years of Slack, email and code can get paid for licensing all of it. I wouldn't be surprised if founders start factoring that into when they shut down.
17. People are starting to talk about monetizing the agent web. It feels really early, but when the most popular user of the internet is an agent, what startups should you be building?
18. I think agent insurance is coming. Once an agent makes an expensive mistake, insurers will want audits before they cover anyone.
19. Several people said the hire they want most is someone with taste who can write evals. The models are getting good at generating ideas, so the hard part is judging which ones are good.
20. New trend I observed: startup raises VC, uses venture dollars to become a creator, startup fails, founder falls back on being a full-time creator and incubates other products bootstrapped.
21. Getting SIGNIFICANT distribution is HARD right now. Founders are sponsoring buses, buying billboards like crazy and throwing parties with famous DJs to get noticed. Kinda feels dotcom era in that sense.
Attention is what's scarce! The growth guy going viral sharing his UGC strategy from Wispr Flow is a good example. It's the sauce everyone wants, and I truly believe there are probably only 50 people on the planet who know how to scale these types of businesses efficiently in this era.
Always good to get that dose of SF. I felt sooo lucky to have such an incredible trip during such an incredible time in building businesses. Surreal in so many ways.
Happy to be home and locked in.
Until next time!


Todd Dailey retweeted

so the duo is a small ipad the ipad is a big iphone and this thing is a giant apple watch? I see the strategy


Todd Dailey retweeted

Apple ships a lot for developers, and it's easy to lose track.
So I made Cupertino Tech to see it all in one place: cool icons, platforms, code samples, WWDC sessions and a timeline back to 2001.
Spot something missing? Tell me and I'll add it.
cupertino.tech


Todd Dailey retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
