

From homelab and edge AI to local LLMs, Turing Pi handles it all. Datacenter-level compute in a desktop design. Join the community https://xitter.cf/t.co/Siv6YvvCYO
United States
Joined June 2019
- Tweets1.6K
- Following239
- Followers23.3K
- Likes4.4K






Turing Pi retweeted
Your security camera shouldn't come with a subscription to your own footage.
Run AI-powered object detection locally on a Jetson module inside Turing Pi 2.5.
No cloud required for detection. No monthly AI inference fees. Just your cameras, your hardware, and your data.
And that's only one of four compute slots.

Your security camera shouldn't come with a subscription to your own footage.
Run AI-powered object detection locally on a Jetson module inside Turing Pi 2.5.
No cloud required for detection. No monthly AI inference fees. Just your cameras, your hardware, and your data.
And that's only one of four compute slots.

Anthropic ran a 26B model on 15 cheap TV boxes
>paper: "AI models may be capable of self-replicating without access to a datacenter"
>15 off-brand Android TV boxes, about $55 each
>4GB of RAM per box
>Gemma4-26B split by layers across all 15
>it worked
>0.39 tokens per second
>why so slow? only one box works at a time
>the other 14 wait
Homelab lesson: splitting a model across weak nodes doesn't add up their speed. Fit it in one node's memory and use the rest of the cluster for everything else.
anthropic.com/research/self-…

Paying $15/month to host an app? Another $15 for your database? Another $15 for a side project?
Those subscriptions add up.
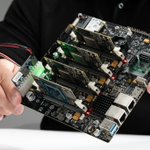
With Turing Pi 2.5, you can run up to 4 compute nodes on one board. Host your apps, databases, containers, and local AI workloads on hardware you control.
No per-app cloud hosting bills for what you self-host. Just your hardware, power, and internet.
Stop renting compute. Start owning it.
Build your own cluster → turingpi.com




You should be able to run AI without renting someone else’s computer.
You should be able to choose exactly what hardware your workloads run on.
You should be able to mix ARM, NVIDIA, and other compute in the same system.
You should be able to put powerful hardware where it matters and efficient nodes everywhere else.
You should be able to add more compute without replacing the machine you already built.
You should be able to run local models on your own hardware.
You should be able to run containers, databases, agents, home automation, and services beside them.
You should be able to keep your data inside your own network.
You should be able to build a real cluster that fits on a desk.
You should be able to run it 24/7 without keeping your laptop or desktop alive.
You should be able to reach it from anywhere.
You should be able to decide what touches the internet and what never leaves your network.
You should be able to upgrade one node without rebuilding everything.
You should be able to replace one node without taking the whole system down.
You should be able to experiment without watching a cloud bill climb by the hour.
You should be able to see exactly what is running, where it is running, and what it is doing.
You should be able to change it.
You should be able to break it.
You should be able to rebuild it better.
You should own the hardware.
You should own the stack.
You should own the compute.
Your infrastructure should be yours.




A lot of AI workloads are about to discover the same thing databases did:
if the data already lives with you, constantly shipping it somewhere else starts to look silly.
Smaller models are making local inference capable enough for more real work every month.
At some point, the question stops being “can we run this locally?”
It becomes “why are we still sending it away?”
qwen3 8b runs on a jetson orin nano 8gb.
full gpu offload, 37/37 layers, 12.64 tok/s at 4k context. all seven Q4_K_M configs we tested fit at 4k. only four survived real 32k prompts.
turingpi.com/jetson-orin-nan…

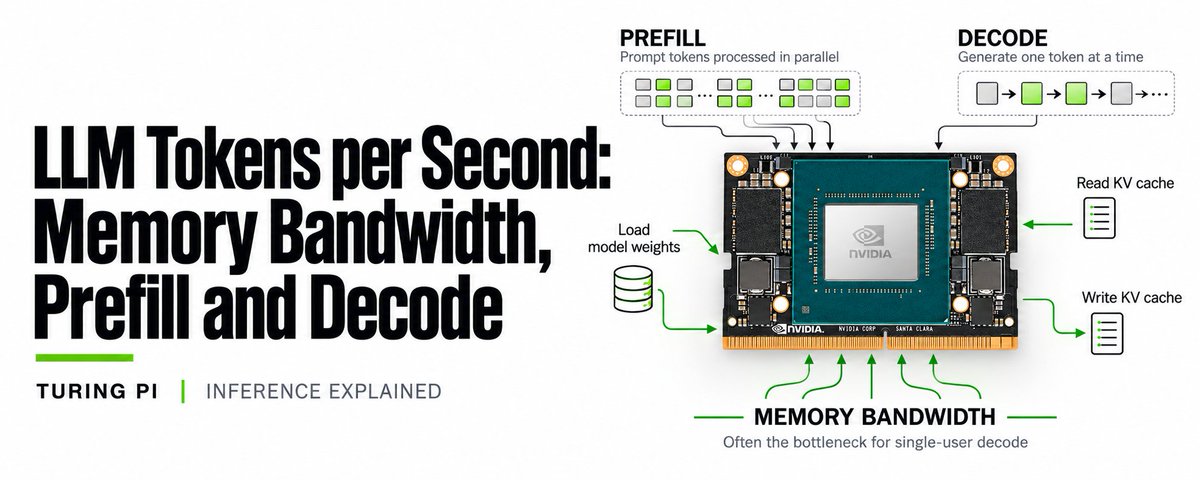
nvidia's Orin Nano 2: 78 TOPS, 8GB LPDDR5X at ~120 GB/s, 8-core Cortex-A78. 2x the inference of the Nano Super in the same form factor, 40% less power at matched performance.
but memory capacity didn't move. the models that fit are the same ones, they just run faster.
so the question stands: what actually fits in 8GB? we benchmarked 7 configs on the Nano. numbers tomorrow.
nvidianews.nvidia.com/news/n…

