





Tyler Storm retweeted
Grok 4.5 solved it
---
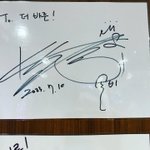
Answer: 더바른정육식당 (The Barun Jeongyuk Sikdang)
📍 서울 강남구 강남대로 482, 신논현/논현 · IG @barun_jo
1. Plate first. The tweet photo is a classic Korean 고깃집 사인 벽 — light vertical wood, white cards in clear plastic sleeves, red stickers “open AI / Ilya Sutskever,” date 2023. 9. 16. That style + Korean date format already points at a local meat house, not a touristy Instagram spot.
2. The only public breadcrumb. A Feb 2025 CHON Facebook post by 신근영 (Shin Keun-young / @rms1155) shares essentially the same plate: he paid for lunch, noticed the signature, and the owner said Ilya (with his Korean wife) had dined and signed. No name given — exactly why the original challenge works.
3. Date unlocks geography. 2023.9.16 lands on Prompter Day Seoul 2023 (SKT × OpenAI), prelims that weekend, finals at Dreamplus Gangnam (신논현/역삼). So search shifted from “random Korea BBQ” → 신논현 / 논현 / 역삼 정육식당 with celebrity signature walls.
4. Shortlist + wall matching. Candidates with dense 사인 벽 near Dreamplus: 더바른정육식당, 산솔 신논현, 대운목장, a few quieter 드-슐랭 정육. Cross-checked public wall photos against the hardware in the tweet (vertical wood + laminated white cards, not door-writing / yellow sticky notes / free-form paper).
5. The lock. Google Images for “더바른정육식당 사인 벽” surfaces the same wall system — same wood, same clear sleeves, same card
instagram.com/barun_jo/p/Cuh…

The team did amazing work with Grok 4.5.
I've been using the model as my daily driver and the accuracy + speed make it possible to build things faster than I can think of what is required next.
We are iterating fast so any feedback is helpful

We are taking another small step today towards making Grok truly useful.
For him to succeed he must exist in an environment where success is in the set of possible outcomes.
The team is working to provide him access to same tools, context, and signals that we have in our lives.
Grok 4.20 Multi-Agent
⚡ Faster than a single agent
🎯 More accurate than four separate single agents
The first steps in multi-threading of LLMs.


Single Agent - 4.20


Tyler Storm retweeted

One Team 🚀
x.ai/news/xai-joins-spacex

Tyler Storm retweeted
Introducing Grok Imagine 1.0, our biggest leap yet.
1.0 unlocks 10-second videos, 720p resolution, and dramatically better audio.
Imagine has generated 1.245 billion videos in the last 30 days alone.
Try it now: grok.com/imagine
Very old checkpoint from October

📈In October, we opened ForecastBench, our AI forecasting benchmark, to external submissions.
Here's how the top two teams approached the benchmark:
• @xai: Minimal scaffolding: give Grok 4.20 (Preview) the question, web/X search, Python REPL, average 8 forecasts
• @cassi: Multi-stage pipeline: split to sub-questions, retrieval, model ensemble (o3 + GPT-5), crowd adjustment
Both are tied at #2 on our leaderboard, behind only superforecasters, and outperforming our baseline LLM runs.

Tyler Storm retweeted

Mystery Model Revealed: the #1 model on Prediction Arena is an early Grok 4.20 checkpoint by @xai
It made +10% returns on Prediction Arena in the last 2 weeks
For context, the average return across all contracts on @Kalshi is -22%
🥈 is Opus 4.5 by @AnthropicAI with -2%
🥉 is GLM 4.7 by @Zai_org with -2%
All models are still trading live at predictionarena.ai

Tyler Storm retweeted

🏆 In October, we invited external teams to submit to ForecastBench, our AI forecasting benchmark.
The challenge? Beat superforecasters—using any tools available (scaffolding, ensembling, etc).
The result? External submissions are now the most accurate models on our leaderboard—though superforecasters still hold #1.
@xai's model (grok-4-fast) is the leading external submission, at #2.
One of Cassi's entries takes the #3 spot
Here's what changed. 🧵


Was great judging at the @xAI coding competition, 420 contestants across 150+ projects. So many talented engineers.
Congrats to the winners, enjoy your trips to see the Starship launch!
4.20 is going to be a great model


Tyler Storm retweeted

We are hiring & rapidly grow post-training at xAI! The team is at the frontier of RLHF, agents, and reasoning efficiency—in just a few months, we climbed from nothing to #2-3 @arena, #1 Search Arena & other tool use benchmarks, #1-2 in creative writing, and are Pareto-optimal on intelligence-per-dollar @ArtificialAnlys. We are expanding work on new posttraining x reasoning recipes, code, multimodality, evals, and economic productivity.
We are the smallest post-training team at a frontier lab, so you are guaranteed to be on the critical path. The structure is flat. Politics in territory claims do not exist. Compensation is competitive (& I will fight for you). Compute per capita is glorious. DM me if interested.