Pango (@trypango) header
Pango (@trypango) profile picture

Computer use trajectories for better models.

Joined June 2025
Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)Photo by Pango (@trypango)
Today, we're excited to announce GLADOS-1, the first computer-use (CUA) model post-trained using collective, crowd-sourced trajectories. Post-trained on UI-TARS-7B-SFT, we improved performance of the base model on OSWorld.
23
40
3
186
21,358
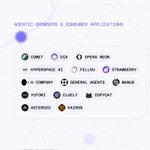
Last week, we published a blog surveying the computer use agent landscape. Today, we're excited to share our interactive, live market map of the major players in the space.
This quoted post is unavailable.
9
20
1
84
15,341
Consequently, we're seeing an explosion of companies building critical infrastructure - datasets, environments, developer automation - to help improve the SOTA.
1
5
831
The Pango Interactive Actions Previewer is live!
7
19
70
7,112
The Solution To combat these poor ergonomics, we built the Pango Interactive Actions Previewer, which quickly allows research to view each frame, action, and screenshot combination from (2) for quality.
2
2
4
765
To get started, all sessions in our HuggingFace datasets now contain links to the action previewer. better ergonomics = better models = better computer use agents. huggingface.co/datasets/chak…
3
613
feel the agi (with longitudinal, organic, compensated, system-2 reasoned user sessions)
watching chatgpt agent use a computer to do complex tasks has been a real "feel the agi" moment for me; something about seeing the computer think, plan, and execute hits different.
4
3
19
2,204
This dataset is perfect for: - Post-training computer use agents on authentic patterns - Research on temporal reasoning & error recovery - Improving existing models with System 2 reasoning behavior
1
2
8
1,029
The Pango dataset is now live on HuggingFace! This presents the first large-scale dataset of real users performing authentic work tasks in business productivity software.
35
101
1
122
19,590
What makes it unique: - Real longitudinal work sessions, not scripted demos - Full interaction traces (clicks, keystrokes, screenshots, video) - Error recovery patterns that most datasets miss - Synthetically generated thought metadata for training reasoning models
1
6
633
can't believe we got GTA1 before GTA6 new state of the art computer-use-agent just dropped
2
1
14
846
Mind2Web (2,350 tasks across 137 real websites spanning 31 domains) and other open‑source HCI datasets like OSWorld & WebArena are fantastic for prototyping and fine‑tuning. But at ~2k–4k tasks (estimated ~40 hours) they’re tiny compared to what you’d need to truly post‑train an LLM.
26
29
1
91
9,847
Result? A feedback loop that scales data like no open dataset can - building LLMs that actually understand how people use software, not just mimic a handful of scripted tasks.
1
10
771
Existing open datasets are great starting points, but for breakthroughs in LLM usability and software understanding, we need next‑level scale with incentivization. We need consumer activation. And that’s what Pango delivers.
8
692