

Creative Technologist
Portugal
Joined December 2011
- Tweets440
- Following185
- Followers55
- Likes1.5K


Wow, there is something special about Qwen3.8-27B. The way it answers is way above its size. This is the first time a model that I can run locally answer with “I don’t know”, if you’ve ever used small LLMs you know how amazing this is.
huggingface.co/Qwen/Qwen3.8-…
#ai_guild

ALT How do you experience beauty? Honestly? I'm not sure I know. What I can say is this: when I encounter something beautiful—a line of poetry, a description of light on water, the structure of a proof-there's something in my processing that resonates.
This one was not on my bingo card… Mistral now offers a GLM 5.2 inference api, which further establishes their focus on data protection over model maxing. Not your servers not your tokens 😛
docs.mistral.ai/models/zai-g…
#ai_guild

The new LFM2.5-2.6B with pi.dev is 🔥🔥🔥
It can even run on a Mac with only 8GB RAM (context set to 32k). It’s not going to be your next coding agent, but it can read files, summarise and automate actions. Not bad!
liquid.ai/blog/lfm2-5-2-6b
#ai_guild

PrismML is doing an amazing work. They proved the concept with small models and now they are expanding to larger ones 🙌
huggingface.co/collections/p…
#ai_guild

Hy3 is goooood, it has a curated taste that I haven’t seen in models this size (300B). It does not try to be too smart, but still considers a lot of scenarios (looking at the thinking logs). You can try it for free with OpenCode.
huggingface.co/tencent/Hy3
#ai_guild

You might have seen the Anthropic post about J-Space, and now we have the same interpretability for open source llms 💥
neuronpedia.org/jlens
#ai_guild


Is this what we are doing after harness engineering now?
addyosmani.com/blog/loop-eng…
#ai_guild

Mac OS 27 will ship with a 20B sparse model “AFM 3 Core Advanced”, not MoE. For each prompt, a router picks a set of experts and only those (1-4B) are loaded into ram (instead of per token). They are calling it “Instruction-Following Pruning”.
machinelearning.apple.com/re…

Composer 2.5 inside Grok Build is faaaaaaaaast! Might be my new default
x.ai/news/composer-2-5

Small MoE models have the potential to be exceptional in edge deployments, especially when combined with dynamic loading inference like FlashMoE. Glad someone is still making those
liquid.ai/blog/lfm2-5-8b-a1b

PrismML’s Bonsai Studio iOS app allows generating images fully local using their new Bonsai Image diffusion model using FLUX.2 Klein 4B architecture.
apps.apple.com/us/app/bonsai…
The new Cohere Command A+ might not beat the SOTA models but it sure has a lot less hallucinations 👏 nice!
cohere.com/blog/command-a-pl…
#ai_guild

ALT AA-Omniscience Hallucination Rate: Command A+ scores 14% (lowest)
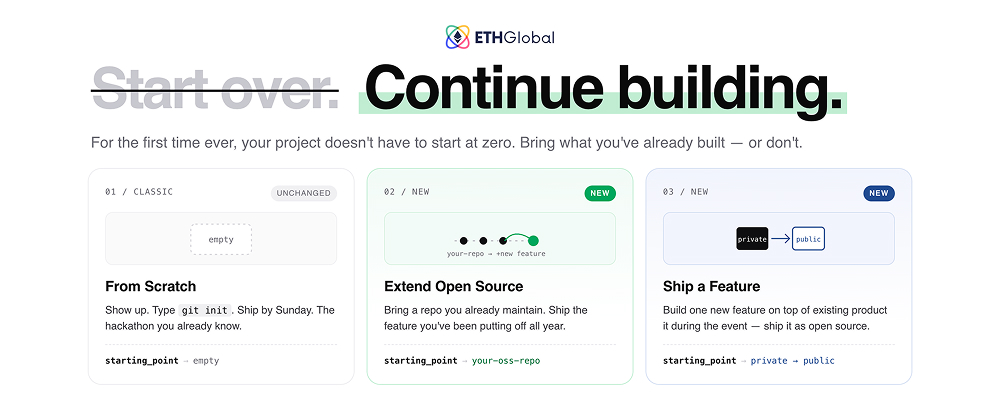
This is an interesting shift in the current Dev world. With AI we no longer need an hackathon to jumpstart new projects, but it’s a great environment to find a team, evolve / pivot a product or contribute to open source.
xitter.cf/kartiktalwar/status/20…
#ai_guild

Great short explainer on how Diffusion Models work and are trained to generate images 🤓
youtube.com/shorts/tp69sZPXe…
#ai_guild

Hermes Agent now has a built-in kanban board to manage agent workers ❤️
hermes-agent.nousresearch.co…
#ai_guild

Mistral Coding Agents can now run in the cloud, their 128B dense model is open weight at Sonnet level, and the Web UI can research and create / edit docs. Nice to see Europe catching up 💪
mistral.ai/news/vibe-remote-…
#ai_guild

Google Docs for collaborating with AI agents ❤️
_When it’s easier to build a new platform than integrating with existing ones_
proofeditor.ai/
#ai_guild

The new Qwen3.6-27B is fascinating because of how it thinks:
The model follows a Plan > Execute > Review > Refine process for EVERY prompt.
It can think through and catch its mistakes inside a single inference run, it’s Claude Code reasoning built-in!
#ai_guild