
Founder - Deus Experiments • Building apprentice models that grow with you
Joined July 2014
- Tweets15.2K
- Following1K
- Followers12.7K
- Likes53.2K





tokenbender retweeted
many people think it's about writing software but we're in the business of expectation and trust management.
tokenbender retweeted

We are underestimating the bad faith eMudhra possibly operated in. They actively added a step to the key generation process causing this failure but are making it seem like a dumb mistake. Let me explain with diagrams and python snippets 👇

Global TLS Intermediate CA incident: We’ve updated our incident page with how it happened, who is affected (one US customer ecosystem), what’s not affected, and what we’re putting in place. We will publish the root cause once our investigation is complete.
👉emudhra.com/en/post/certific…
Readers added context they thought people might want to know
eMudhra minimizes the scope by claiming only "one US customer ecosystem" is affected. In reality, 8 of its CA certificates had catastrophically weak private keys (one being simply the number 4), allowing anyone to forge trusted HTTPS certificates for any website on the internet.blog.google/security/prote…
tokenbender retweeted

There is an (unpatchable?) supply-chain zero-day in PyTorch autograd that allows a regularization term to use the model's weights as RAM and SGD as its CPU clock to run any computation during training.


tokenbender retweeted

i’m using the loss function from the line-go-up paper on all of 4chan and then RLing on a bunch of temu envs that last-gen claude built out of a failed startup’s monorepo it’s gonna be fine as long as we think hard enough about what alignment means
tokenbender retweeted

Why are LLM parameter updates so sparse during post-training? 🔍
In our new paper, we study this phenomenon through the lens of Fisher information, connecting theory and empirical findings across RL, SFT, and on-policy distillation.
A thread on what we found 🧵👇

tokenbender retweeted

new blogpost about beginner-level advice on breaking down proofs, which I feel students new to theory may find helpful especially at this time where most derivations are done with the help of LLMs: nanjiang.cs.illinois.edu/202…
tokenbender retweeted

Today, I am excited to announce Animation Bench. Our first benchmark to evaluate frontier models on web animation reconstruction.
Frontend generation is a common commercial use case for coding agents. In addition to static layout it contains transitions and interactions triggered by dynamic behaviours. We evaluated four frontier models on 48 tasks from real websites across three axes:
1. Visual Similarity
2. Motion Consistency
3. Layout Correctness.
We find that motion consistency is often incomplete or missing.


tokenbender retweeted

Analog Design Bench's paper is out.
- high-quality tasks curated by experts with verified testbench;
- agents finish tasks with electrical specs unmet;
- reference-topology provides most test-time gain
Check it out: arxiv.org/abs/2609.33356


tokenbender retweeted

Made with Claude Opus 5.5.
The fearmongering about AI always makes us forget that NOTHING WENT FOOM, as was always predicted.
Send this to your doomer friend who has a very high P(Doom).
Accelerate.


tokenbender retweeted

We trained a model to predict AI-written blog posts from structural features - and discovered the shape of slop.
On posts it had never seen, it told AI and human apart with 98% accuracy, getting only 19 of 1,740 wrong.
Paper and code: arxiv.org/abs/2609.15369

tokenbender retweeted

We (@PantheonInc) have been working on a robotics data quality pipeline that uncovered a series of major problems in public robotics datasets, especially for world modeling.
To improve the quality of data available to open-source robotics, we're publishing annotations for four of the most popular datasets. Some examples of issues, and our report 🧵
tokenbender retweeted

Taleb is helpful here: it doesn’t really matter if you’re wrong a lot about minor survivable things, if you’re really right about the big things. (and inversely, it doesn’t matter if you’re right about a lot of things, if you’re wrong about the thing that kills/ruins you)

tokenbender retweeted
first everyone will throw scale at it to improve it (data and compute), then we maximise efficiency and achieve the same thing with smaller models.
gives me a feeling that first gen SoTA models would be matched only by second or third gen smaller models (~half params)
tokenbender retweeted

Introducing AngelX -
angelx.dev/
This is angelX v0.1.3 - github.com/newjordan/angelX
This has been a first order priority for me since Aider and I love harnesses, I hope you like it and find value in the work.
Video features Primeintellect Evals as the benchmark environment.
tokenbender retweeted

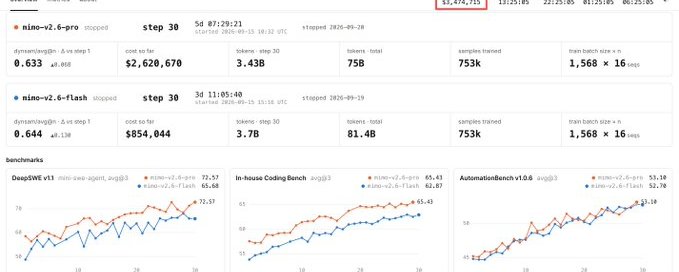
Xiaomi’s Live MiMo-V2.6 RL Run - Understanding what goes in the checkpoint
tokenbender retweeted

Announcing one year of LLM inference metadata traces, with 6.12 billion requests.
We hope this dataset can support research on real-world LLM serving workload understanding, system design and infrastructure optimization. Explore the dataset and learn more: data.agentic-system.org
Driven by our great graduate student William Nixon and
in collab with @jon_durbin @airesearch12 @chutes_ai
tokenbender retweeted

pleased to share the entire arXiv site as a dataset on HuggingFace
huggingface.co/datasets/sece…
3,148,796 papers, every version, in LaTeX, PDFs, PostScript, HTML, 16 TB in total
