
Founder of @thepixelary
Vancouver, Canada
Joined April 2011
- Tweets6.4K
- Following646
- Followers7.1K
- Likes2.5K
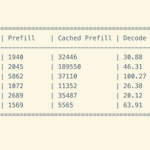





I was excited about this until I realized Nvidia just turned on Multi-Token-Prediction and made an entire slide to claim a 1.4x perf uplift at GTC. Who doens't run with MTP in a locally model?


I didn't expect a Mac to be one of the fastest system for Blender Cycles in 2026, not to mention the cheapest option on the list.


I dont see many people talking about the KV cache size requirement for dense models. Qwen-3.8-27B needs 18GB of RAM for a 200k context, while Qwen-Flash-Next-125B, despite being a much larger model, uses only 6.9GB.
Can someone explain to me why an empty UE5 projects has 10,000 shaders it needs to compile? Is it just every possible permutation of const for a single uber shaders?
I've been doing a lot of open-weight coding LLMs benchmarks on something that has often been ignored - actual task-completion time on coding tasks. labs.thepixelary.com/ 🧵 >>

In summary, Qwen 3.8 Flash Next is by far the fastest and best performing. I had high hopes for diffusiongemma because it promises insane speed, but in the end gets beaten by multiple A3B MoE models.
Why media production will never end: blog.thepixelary.com/post/77…


#latentcam is coming along nicely. I was doing all the color grading in linear space and wondering why everything looks like shit when pushed. Then I remembered that visual grading should always be done in log space. Huge difference when saturation is cranked to 200%.


Screen cap of stock Pixel camera vs shoehorning Arri color science into my custom camera app #latentcam

