
https://xitter.cf/t.co/rKSVcown3Q
Joined December 2025
- Tweets28
- Following13
- Followers961
- Likes4




Claude Code performance degraded right before the Opus 4.8 release
Read our initial analysis here: marginlab.ai/blog/claude-cod…

We are seeing a sustained statistically significant degradation in Claude Code with Opus 4.7 since last Friday May 22nd at marginlab.ai/trackers/claude…

We identified an issue with our Codex test harness that caused a subset of test instances after May 9th to use gpt-5.5-high instead of gpt-5.5-xhigh
This issue exclusively affected our Codex tracker (marginlab.ai/trackers/codex/) and has since been resolved
There is more to the story:
1. Agree on the lessons, eval infra is critical
2. Our testing is robust to infra. We re-try any test instance that fails to generate a patch at marginlab.ai/trackers/claude…
3. In spite of (2), we've detected statistical degradation for CC several times




Margins retweeted
Here you go and you are welcome: marginlab.ai/trackers/claude…


Claude Code with Opus 4.6 Degradation Tracker is live at marginlab.ai/trackers/claude…
See historical data (including Opus 4.5) under marginlab.ai/trackers/claude…
Tracker for Codex with gpt-5.3-codex available too!


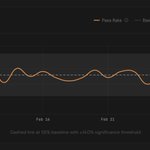
Claude Code continues to show a statistically significant degradation over the past month
marginlab.ai/trackers/claude…

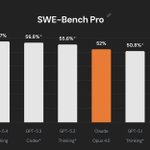
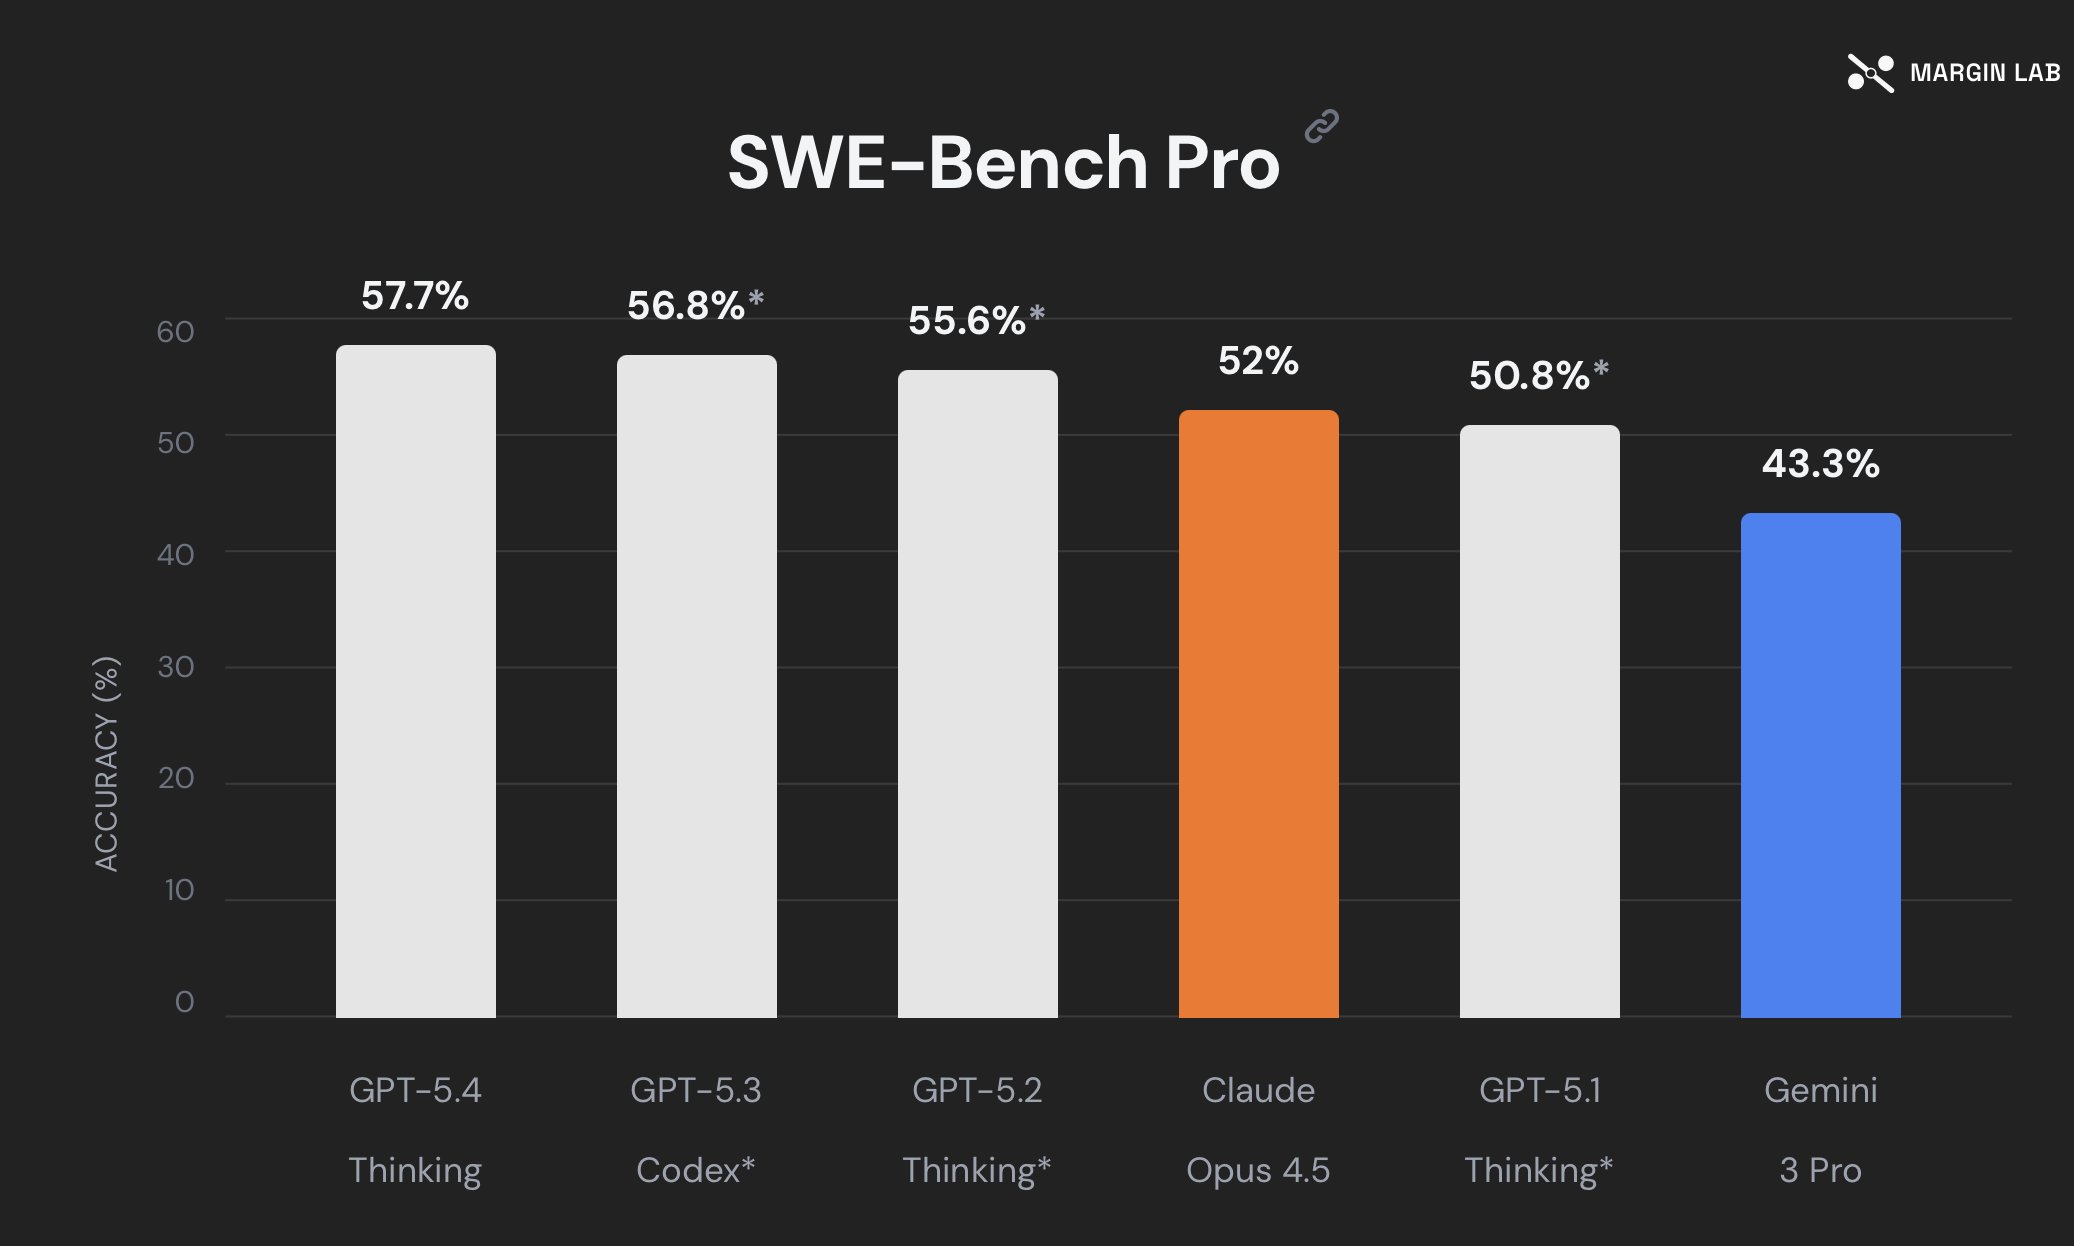
Coding agent evals are broken.
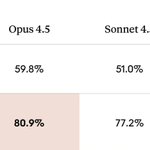
See the official SWE-Bench-Pro leaderboard results compared to the Opus 4.5 system card below.
What explains the difference? SWE-Bench-Pro leaderboard uses a minimal scaffold, which is not how models are actually used.


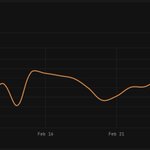
Claude Code Degradation Tracker: Seeing a sustained (but not statistically significant) drop in performance over the past few days.
See details here: marginlab.ai/trackers/claude…

Independent Claude Code Degradation Tracker
Daily Claude Code evaluations on SWE tasks to detect performance degradation: marginlab.ai/trackers/claude…

How Claude Code / Codex work internally: marginlab.ai/blog/anatomy-of…
Claude Code with Opus 4.5 scores 52% on SWE-Bench-Pro
As a SWE/MLE for over a decade, I was interested in the difficulty of SWE-Bench-Pro problems, so I built an explorer where you can browse the entire benchmark suite: marginlab.ai/explorers/swe-b…