

Idiocracy prompts sarcasm - Game/Sound Design/AI Tools - https://xitter.cf/t.co/SkTZECUY3u - Ex EA,PWE/Runic/Cryptic,5PG - These are like, my opinions, man.
Sol System, Multirealmic
Joined February 2009
- Tweets19K
- Following3.2K
- Followers809
- Likes28.5K




Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Street Fighter #1 in theaters check me out • gunitbrands.com

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Never said that.
The question asked at the London comic con was, how do we feel about it being over.
My answer was it's not over until they recast our characters.
Which has not been done.
So "it" is not over until then.
No matter if we do another project or not.
Thats what was said.
Please do not misquote me for hits on your platform.
Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Just doing some light dev work today as it's a Saturday. Adding improved wheel spin physics, better collisions, rev limiter, more sound effects and stuff like that. 🏁
#SuperPolygonGrandPrix
Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Run a 763B-parameter model locally. DeepSeek-V4.1-Flash-1017 on a 12GB GPU.
Frontier quality with GSQ-RCO quants, directly supported in the Strata inference engine.
Further info below. Much more to come. Follow for updates.

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Join the limited-time Judge Dredd™ event in Pinball FX!🏆
Finish in the top 90% to earn a unique trophy for your PinHall.
🗓️ Competition ends November 5, 1 AM PT.


Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

It's #screenshotsaturday!
Show me your indie games!


Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Miyomoto's response to why AI is good is so eloquent I am honestly impressed.


Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Big announcement happening tomorrow at 8pm CEST - BE THERE!
discord.gg/dh3Fjw3cq?event=1…
🎮 opencnc3d.com
💬 discord.gg/HmwY4KVbpy
#CommandAndConquer #CNC3D

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted
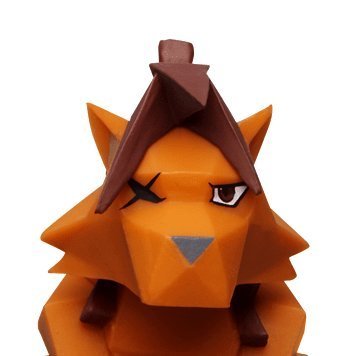
Zelda series Producer Eiji Aonuma received the “Knight of the Order of Arts and Letters” honor from the Minister of Culture in France!


Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

卧槽,3090要可能要涨价了!!
因为老黄的刀法被人破解了
有人给3090解了个锁,同样限制在 360W,PyTorch 测试从 75 TFLOPS 跑到了 135 TFLOPS,提升约 80%!
你以为是超频,把功耗往上拉?
但他改的是显卡里控制运算速度的寄存器,这些寄存器平时有权限保护,正常改不了
他利用 GPU 启动固件的漏洞,赶在 NVIDIA 驱动加载之前拿到写入权限,把相关运算改成全速,再交给原版驱动使用
解开的主要是 FP16/BF16 输入、FP32 累加这类 AI 运算的速度限制 但测试算力多了 80%!!
4090 也有分支项目做到了:同类运算的指令吞吐,从约 165 TFLOPS 提升到 331 TFLOPS,接近翻倍
项目地址,附上👇
github.com/Zagitta/gpu-unloc…

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted
3090 prices is going to be brrrrr
github.com/Zagitta/gpu-unloc…

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Working on a sci-fi game? 🚀👽
Check out how we created all the sound effects for a moon base using DSP Sci-Fi! 🌕🔊
tsugi-studio.com/blog/2023/1…
#scifigame #scifi #sciencefiction #gamedev #indiedev #indiegamedev #moon
Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

What people don't realize is that this happened to almost every large Western game company, and most of them will be unable to recover (since recovering requires pulling an Elon@Twitter, and almost nobody has the will to do that.) Yet also, most of them have not yet gone out of business. So therefore ... ... ...
Technomantics™ - °A Shrewd Skew° heading to Steam retweeted
Create all the sci-fi sound effects your game needs with DSP Sci-Fi! 🚀
From spaceships and weapons to alien lifeforms and futuristic mechanisms, bring your sci-fi world to life!
tsugi-studio.com/web/en/prod…
#scifi #soundeffects #gamedev #indiedev #indiegamedev #godotengine #unity3d


Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

We got a new model from @NVIDIAAI Nemotron 3.5 Bolt E4B 4GB
And @UnslothAI quant's are already here !
Since it's based on Gemma4-E4B, and post trained to be better in all way, you can replace existing Gemma4-E4B with new Nemotron-3.5-Bolt-E4B.
Size of each one is attached in screenshot. Get the quant's here,
huggingface.co/unsloth/NVIDI…


NVIDIA releases Nemotron-3.5-Bolt-E4B, a new model that runs locally on 6GB RAM. 💚
Bolt-E4B can run on edge devices like phones and delivers top-tier performance for its size. Trained on Gemma 4, it supports vision.
GGUF: huggingface.co/unsloth/NVIDI…
Guide: unsloth.ai/docs/models/nemot…

Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

Dear @nvidia, a friendly ask from a guy running 4 of your 3090s and 1 of 3080 Ti.
The 30 series is 6 years old. You dont make these cards anymore. Maybe its time to hand them over to the community completely.
My post about unlocking the 3090 got 270K views in a day, and the replies are the real story. People asking about the 4090, 3080, 3060 and 2080 Ti. People asking how to do it on Windows. Others listing what the community already patches on these cards: the NVENC session limit, P2P between GPUs.
Thousands of people are digging through your old cards with kernel modules, 1 setting at a time, because they love this hardware and want everything it can give.
Publish what is limited on consumer Ampere and Turing. Ship an official driver switch for older generations. Or just open it up.
I understand the business side. Some people might keep their old cards longer instead of buying new ones. But it would be a huge gesture. You talk about local AI on stage, you ship open models, you sell DGX Spark for home. This would show the care goes all the way down to a used 3090 under someone’s desk.
Give them to us. We will do the rest: benchmarks, guides, models tuned for these cards.
@NVIDIAAI

NVIDIA sold millions of 3090s with 50% of the tensor speed switched off. Not missing. Switched off.
1 kernel module flips it to full, and my BF16 tensor pipe went from 82 to 155 TFLOPS. Nothing else changed on the cards, and the outputs match the stock run byte for byte.
All so the gaming card wouldnt eat into workstation sales. Every 3090 owner ran at 50% for 6 years, so a pro card could look worth the price. Fine, its their business model.
And LLMs are the least interesting place for this. Decode waits on memory, and my engine runs its experts in int8. Still +10% on prefill.
The models that live on BF16 tensor math are everything else. Qwen Image 2.1 and FLUX 3 Klein, where every diffusion step is big matmuls. MiniMax H3, which takes 4 to 7 minutes on my cards. Music and speech models. And training, every LoRA anyone ever trained on a 3090 went through exactly the path that was cut.
Thats what I measure next. This is only the start.
Technomantics™ - °A Shrewd Skew° heading to Steam retweeted

If used Clairvoyance, you wouldn't even need Tailscale. You just install it on the clustered machine and access it from other Clairvoyance clients (or via the web). Totally seamless and designed around your use case.
The issue for me is the amount of RAM needed. That's going to be an expensive setup.