

Open-source inference for agents.
Joined September 2019
- Tweets928
- Following310
- Followers731
- Likes502





Superlinked retweeted

Welcome to Dayly, @superlinked. happy to be your GTM intelligence platform of choice.
more in 🧵

Superlinked retweeted

Wrapping up Cohort 2 and heading into Cohort 3 of the Inference Engineering and System Design course..
This is the kind of engineering community @LambdaAPI @modal @superlinked @baseten nurtures.
Thank u @TheZachMueller @charles_irl @philipkiely and Daniel for making it happen!


Superlinked retweeted
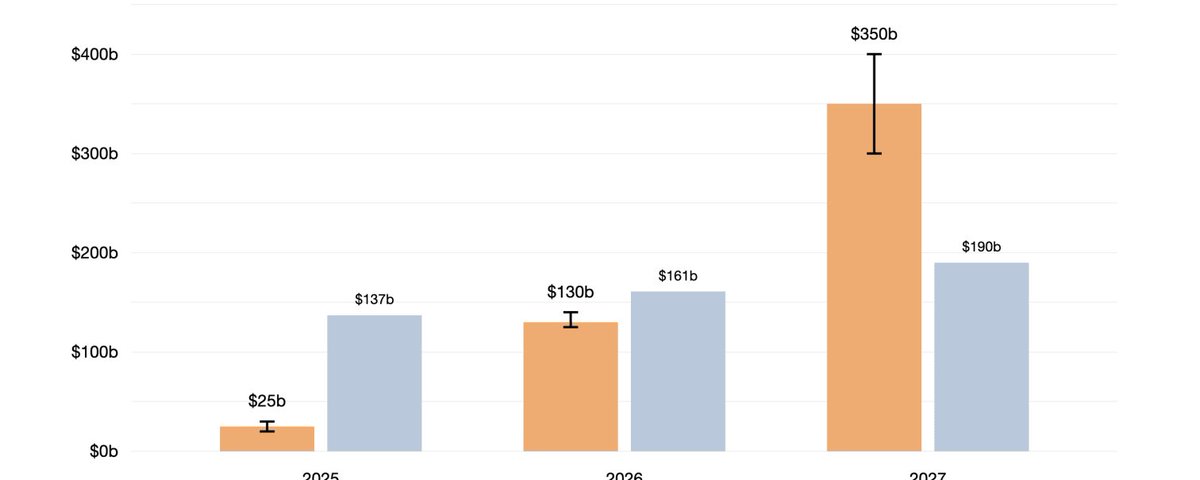
If a founder built a startup in the database market in the mid-2010s, 2% market share meant the company could IPO. No surprise the database was the most important software category in that era.
Inference is about to surpass it.
Superlinked retweeted
Embeddings, OCR, reranking and generation don't necessarily run best on the same inference runtime.
SIE uses multiple compute engines, including PyTorch, Flash Attention and SGLang, and selects one per model. The application sees one inference layer. Interested?
Superlinked retweeted

just got access to Claude Fable 5.5 👀
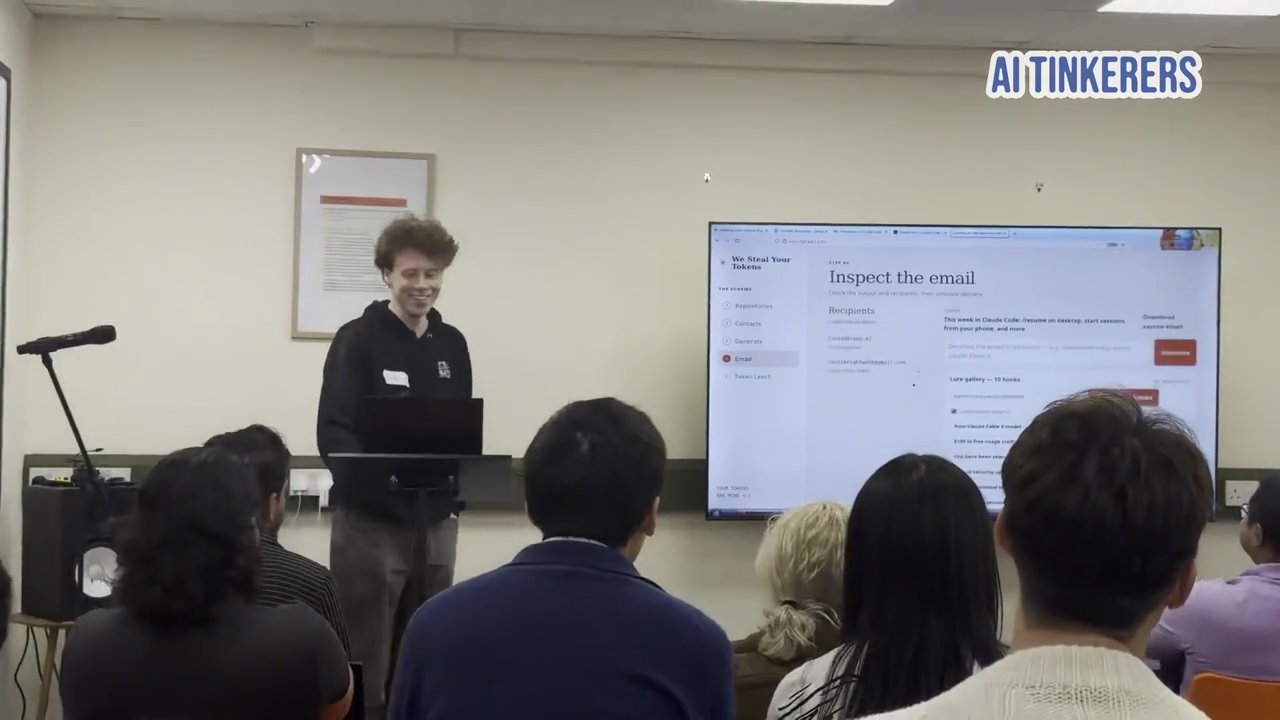
that was the bait for We Steal Your Tokens, which just won first place at the @AITinkerers x @superlinked Hacking Open Source Projects hackathon
it scrapes the email of open-source contributors, uses qwen to write definitely-not-phishing emails from totally-not-anthropic, hides Cyrillic characters in a fake install URL, then waits for someone to paste the very secure curl | bash command into their terminal.
And just like that, I still their codex/claude auth tokens... and all their usage credits
don’t blindly paste links from emails into your terminal unless you want to sponsor someone else’s (my) inference
thanks to @tokengobbler for organising


Superlinked retweeted
"The model runs" is a milestone. It's also where a second project often begins.
Routing. Queues. Autoscaling. Monitoring. GPU provisioning.
SIE open-sources the model serving layer and the cluster around it. 🎉
github.com/superlinked/sie

Superlinked retweeted
AI inferencing is actually harder than training. Training workloads are predictable, but inferencing brings unpredictable, spiky traffic that data centers struggle to monetize.
Get the data right: github.com/superlinked/sie
#AI #MachineLearning #TechNews #DataCenters
Superlinked retweeted

Today's fresh GitHub scan: atlas, arcbox, humanizer, portless, and SIE are all climbing for very different reasons. Which project would you actually try this week? @adib_builds @arcboxlabs @blader @superlinked
#GitHub #OpenSource
Superlinked retweeted

Corgi cafe finally in London! Come meet @superlinked , working from here today. We have the same logo colour as Corgi cafe @Alex_Reinicke_ @UseCorgi – at City of London, London


Superlinked retweeted

Massive breakthrough here!
Self-hosting LLMs just got ~75% cheaper:
Most agent pipelines now run 4-5 small models under the hood: an embedder for retrieval, a reranker for precision, an extractor for entities, and often a small LLM for routine generation.
The standard way to serve them is one server per model. vLLM holds the LLM, TEI holds the embedder, and everything else gets a custom FastAPI wrapper.
Each server reserves its own slice of GPU memory and holds it whether traffic arrives or not. GPUs are billed by the hour, so idle time costs the same as busy time.
This is why switching to small models rarely reduces the bill. The cost was never in the calls but rather in the servers.
The structural fix is serving every model from one process that loads and evicts models based on traffic.
Superlinked just open-sourced exactly that. SIE (Superlinked Inference Engine) is an Apache 2.0 server that runs 85+ models behind one API.
Four calls cover the whole pipeline:
- encode() returns vectors
- score() returns relevance scores
- extract() returns entity spans
- and generate() runs small open LLMs.
Models load on first request and are evicted least-recently-used, so one GPU serves a rotating set of models instead of sitting siloed behind one.
It runs anywhere from a laptop to a Kubernetes cluster, and it plugs into Qdrant, Weaviate, Chroma, LanceDB, LangChain, and LlamaIndex.
You can find the repo here: github.com/superlinked/sie
(don't forget to star 🌟)
I also wrote a hands-on guide to using SIE. It walks through a real-world example where we deploy and manage five models on a single GPU, including a small language model, an OCR model, an NER model, a reranker, and an object detector.
The article is quoted below.


Superlinked retweeted
Stop chasing hype. AI models perform differently depending on the specific task. Don't rely on generic benchmarks. Evaluate them on your own data.
Check out the SIE repo for a better way to deploy: github.com/superlinked/sie
#AI #LLM #MachineLearning
Superlinked retweeted
Stop running six separate deployments just to build one search pipeline. You are wasting GPUs and sanity. We built SIE to unify everything under one process. Grab the code here: github.com/superlinked/sie
#AI #MachineLearning #GPU #SearchEngine #Tech
Superlinked retweeted
We are co-hosting a breakfast with GoodData on June 24th in Prague.
Small open source language models are now easy and cheap to self-host, and they match GPT5.1 intelligence. That changes the math on two things most teams are overpaying for:
The products you build: Running your own models means owning your ops, infra, and evals instead of renting them. We will swap lessons from large scale deployments.
The bill you pay: Plug a self-hosted model straight into your employee agents (Claude Code, Codex, Cursor) and watch the per-token costs drop.
If either of those is on your mind and you're in Prague, come and chat with us over coffee.
Cut Cost and Build Better Products with Open Source AI
Wednesday, June 24, 8:30 to 9:30 AM
Rohanské nábřeží 717, Praha 8-Karlín
Register here: buff.ly/oDpR48C

Superlinked retweeted

I'm replacing OpenAI, Cohere, and AWS Comprehend with one open-source server.
It's called SIE.
One docker run gets you 85+ models behind three API calls:
→ encode() for embeddings (Stella, BGE-M3, SPLADE)
→ score() for reranking (BGE-reranker v2)
→ extract() for named entity recognition (GLiNER, Florence-2)
The cost difference is brutal.
AWS Comprehend entity extraction → $5,000/month
Same workload on a spot A10G with SIE → $5/month
That's the same models, your own cloud, and a 1000x cheaper bill.
It ships the full production stack out of the box:
→ OpenAI-compatible /v1/embeddings (swap the base URL and you're done)
→ KEDA autoscaling on Kubernetes
→ Terraform modules for GKE and EKS
→ Grafana dashboards
→ All 85+ models quality-verified against MTEB in CI
Native integrations with LangChain, LlamaIndex, Haystack, DSPy, CrewAI, Chroma, Qdrant, and Weaviate.
Your data never leaves your VPC.
Apache 2.0. Built by Superlinked.

Superlinked retweeted

Just watched this talk from @f_makraduli
It is very interesting because it highlights a key takeaway: specialised models outperforms LLMs for specific tasks (routing, retrieval, reranking), but serving them is challenging because it is less explored and there are a lot of different models/architecture/inputs/outputs
As someone who worked on serving my two loved ones (ModernBERT and ColBERT), this resonates!

Most embedding infrastructure assumes you know exactly which model you want ahead of time.
This talk starts where that assumption breaks.
@f_makraduli walks through the real profiling mistakes, infrastructure gaps, and production constraints that led to building an embedding inference engine designed for dynamic model loading, hot-swapping, and memory-aware eviction instead of brittle one-model-per-container deployments.
If you're working on small-model inference, embeddings, or GPU infrastructure, this is a practical look at what breaks in the real world and how to design around it.
Check it out here: buff.ly/S1HZCZB
Dive into the SIE repo here: buff.ly/EBnNglg

Superlinked retweeted

Smarter search ≠ more keywords.
It means understanding meaning, filtering fast, and ranking by real intent. 🚀
On May 15th we’re live with @superlinked showing how it all works in production with @qdrant_engine.
👉 RSVP: lu.ma/p30sy66f

Superlinked retweeted

I'm excited to share Oliva Voice Assistant 🗣️
An agent that helps retrieve information from @qdrant_engine database using @langchain 🦜 and @superlinked
Oliva is open source, check it out 👉github.com/Deluxer/oliva

Superlinked retweeted

trying not to be biased so I'll share companies that are not in my portfolio: @PrimeIntellect, @superlinked, @AnythingLLM and ofc the OGs in voice @DeepgramAI and MLOps @wandb
Superlinked retweeted

Compound AI Systems meetup on Nov 19th!
Register: lu.ma/wsbaj6hr
Location: Databricks SF office
Time: Nov 19th, 5:00PM - 8:30PM
Speaker line-up:
Anne Holler, Chief Scientist from @ElotlInc
@BEBischof Bryan Bischof, Head of AI from @_hex_tech
@changhiskhan Chang She, CEO Cofounder from @lancedb
@svonava Daniel Svonava, CEO Cofounder from @superlinked
This event is supported by @lancedb, @databricks @DbrxMosaicAI.
Thank you for hosting as always @jasminechenwang @KobieWon Ester Shmulyian Elizabeth Sapiro Santor
