
Pinned Tweet
Excited to announce that I'll be presenting Training the Untrainable at #NeurIPS2025 ! Come say hello :) or DM/email if you want to chat.
untrainable-networks.github.…
Also keep on the look out for some really exciting new work in the pipeline coming very soon... 👀👀

Vighnesh Subramaniam retweeted

What dimensions organize how humans see social interactions?
We learn them using the first large-scale dimensional account of over 53,000 odd-one-out similarity judgments of naturalistic social scenes. The learned dimensions explain over twice the variance of theory-driven, pre-labeled annotations and better predict visual cortex and regions like the superior temporal sulcus.
New preprint w/ Leyla Isik 🧵
osf.io/preprints/psyarxiv/8c…


Vighnesh Subramaniam retweeted

DINOv2 has never seen a caption, and Qwen3 has never seen an image. We still aligned their embedding spaces without a single image-caption pair.
It even works when the images and the captions come from different datasets.
Project page: dominik-schnaus.github.io/un…
⬇️
Vighnesh Subramaniam retweeted

Can “chicken” make a base model reason? 🐔
Yes!
Why? With the right first tokens, base models can match RL in reasoning. We trace this to learned training data associations and use a simple data edit to make “chicken” elicit reasoning too.
blog: sophielwang.com/cues
Vighnesh Subramaniam retweeted

There is a new kind of robotics called "Vibe Robotics"
It's when you ask agents for fully functioning embodied agents (both hardware and software) that must solve a given task in physically grounded environments.
We build an evaluation to test how good agents (frontier models) are at "Vibe Robotics".
Website: artifactarena.ai/
Vighnesh Subramaniam retweeted

The submission deadline is only a few days away: October 4, AoE!🔵🔴
🔴Read the call for papers: unireps.org/2026/call-for-pa…
🔵Submit your paper here: openreview.net/group?id=UniR…

Vighnesh Subramaniam retweeted

Students sometimes ask me if it still makes sense, in this accelerating age, to pursue a PhD in AI.
Perhaps counterintuitively, I think it's a great time to do so.
I wrote up some thoughts on this here: web.mit.edu/phillipi/www/wri…
Vighnesh Subramaniam retweeted
📣 Call for Papers: UniReps Workshop in Paris!
We invite work exploring why, when, and how distinct learning processes yield similar representations across AI, neuroscience & cognitive science.
📅 Deadline: Oct 4 (AoE)
🔗 unireps.org/2026/call-for-pa…
Vighnesh Subramaniam retweeted

🔥 New paper alert!! Reinforcement Learning with Metacognitive Feedback Elicits Faithful Uncertainty Expression in LLMs 🔥
Can a model that learns to 𝘫𝘶𝘥𝘨𝘦 𝘪𝘵𝘴𝘦𝘭𝘧 get even better at tasks—and learn to be honest about what it doesn't know? Turns out: yes🤯
Details🧵👇

Vighnesh Subramaniam retweeted
Impromptu NeurIPS meetup: "representational convergence by the beach." We will meet at ballroom 20c (near lunch) 2pm Fri and walk over to Marina. Will chat about platonic reps, fractured reps, or anything else about where all these models are heading.
Anyone is welcome to join!
Vighnesh Subramaniam retweeted
Excited to share that I’m at #NeurIPS2025 this year! 🧠
I’ll be presenting at the UniReps Workshop on my work on Social Tokens with @su1001v and @thisismyhat, where we explore how to inject socially relevant visual features into language models to improve social reasoning and alignment.
Super excited to connect with folks working at the intersection of multimodal models and human cognition.
If you’re around, come say hi! And feel free to DM me for a coffee chat ☕️
Vighnesh Subramaniam retweeted

Want to scale models on brain datasets recorded with variable sensor layouts?
Population Transformer at #ICLR2025 may be your answer!
🗺️ Fri, Apr 25 | 10am - 12:30pm (poster @ Hall 3 + Hall 2B #58)
🗣️ Fri, Apr 25 | 4:06 pm - 4:18 pm (oral @ Garnet 216-218)
More ⬇️
Check out our new #ICLR2025 oral paper! Congrats to the team and in particular, to the first authors, @czlwang and @GeelingC!

🎉Excited to share: My first ML conference paper, Population Transformer 🧠, is an Oral at #ICLR2025! This work has truly evolved since its first appearance as a workshop paper last year. So thankful to have worked with the best advisors + collaborators! 🤗 More soon!
1
7
298
Check out our new work for self-improvement of LLMs!
This work uses a multi-agent set up that not only improves performance but preserves diversity over iterations of finetuning.
Website: llm-multiagent-ft.github.io
Paper: arxiv.org/abs/2501.05707

Introducing multi-agent self-improvement with LLMs!
llm-multiagent-ft.github.io/
Instead of self improving a single LLM, we self-improve a population of LLMs initialized from a base model.
This enables consistent self-improvement over multiple rounds.

9
476
Vighnesh Subramaniam retweeted

Interested in large-scale neuroscience of language and multimodal representations? We have the dataset for you, the Brain Treebank! Come to our oral at NeurIPS. Today at 3:50pm PST, East Meeting room braintreebank.dev/ Now with extra foundation models arxiv.org/abs/2302.14367
New paper💡!
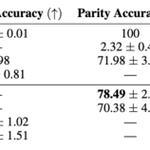
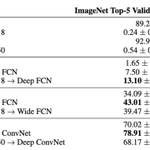
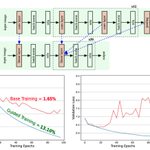
Certain networks can't perform certain tasks due to lacking the right prior 😢. Can we make these untrainable networks trainable 🤔? We can, by introducing the prior through representational alignment with a trainable network! This approach is called guidance. (1/8)

We cover tons of other experiments and settings in the paper such as stopping guidance early and analyzing error consistency of guided networks in the paper.
We hope guidance can be a general tool for improving and understanding neural network design😀! (7/8)
1
75
Work done with amazing collaborators @DavidMa53462349, Colin Conwell, Tommy Poggio, Boris Katz, @thisismyhat, and @_abarbu_.
Paper: arxiv.org/pdf/2410.20035
Website: untrainable-networks.github.…
Code: github.com/vsubramaniam851/u… (8/8)
78