
Playing the infinite game of AI, products, and startups. Building, exploring, and occasionally shipping something useful. 🎮
Joined November 2021
- Tweets1.4K
- Following80
- Followers248
- Likes1.4K


true

Orca has
127K GitHub stars
T3 Code has
63K
both sit
in the same
category
they line up
Claude Code,
Codex,
and other agents,
one worktree
per task
one or two
windows
is fine
the pain starts
at five or six
sessions don't
talk to
each other,
so you become
the copy-paste
layer
and the work
stops when
you leave
the machine
Mirasim is
closed source
it forwards
requests as-is,
without stuffing
extra prompts
you can switch
among about
ten tools,
including
Claude Code,
Codex,
Kimi Code,
and Qwen Code
if a subscription
hits a rate limit,
you can jump
to platform quota
and keep going
you can @
another running
session
from the
input box
a channel @
can hand work
to the right
session
and report back
it also has
a docs editor
the bigger gap
is mobile
and remote
desktop
local direct
links were
measured around
20 milliseconds
an Orca issue
said leftover
terminal processes
held 300 to 400 MB
and did not
release it
a fix PR
mentioned
an unmanaged shell
sitting at
85% CPU
for seven days
Orca still has
an open iOS
slowness issue
T3 Code still has
an open one
about slow
phone sync
open source
can climb
the star chart
fast
the boring work
is a longer
grind
is the polish
the product
now?
22


最近切 Antigravity 的朋友确实多,不过原版 IDE 偏重,纯跑终端 agy 看改文件和调页面又费劲。
如果想给反重力配一套更丝滑的原生 GUI 工作台,可以直接拿 Mirasim 跑本机的 agy:
- 左边改代码,右边宽屏看真页面:不用拉起整套重型 IDE,原生流式界面直接展开思考链、文件改动和单测输出,右侧内嵌桌面级宽屏浏览器实时热更新预览;回合还在跑的时候补一句需求,会自动并入当前回合。
- 把 Antigravity 编成专属 Bot,交给 Mira Bot 自动派活:可以把 Antigravity、Claude Code、Codex、Kimi Code 按职责配成不同的助手 Bot(底层就是完整智能体,零能力阉割)。嫌切窗口麻烦就直接跟总管 Mira Bot 说一句话,它自动把前端动效派给 Antigravity、后端并发派给 CC,每件事独立开会话跑并实时回传任务卡;接上飞书、Telegram、Discord 等 IM 频道,离开电脑在群里 @ 一下也能接着指挥。
- 不用从 CC / Codex 二选一:同一个窗口支持多列并排分屏,也支持聊到一半切给另一个智能体接着干,上下文直接带过去;空间里的消息、会话、事项和文件对所有 Bot 完全透明共享。
- 双组额度 + 全局 MCP / Skills 装一次共用:面板直接把 Antigravity 的 Gemini(5h / 7d)和 Claude / GPT(5h / 7d)两组额度拆开列清楚;CC Switch 配好的供应商一键读取导入,Skills、MCP 连接器和内置浏览器控制(Computer Use)开一次所有智能体和 Bot 直接共用。
免费下载:mirasim.ai


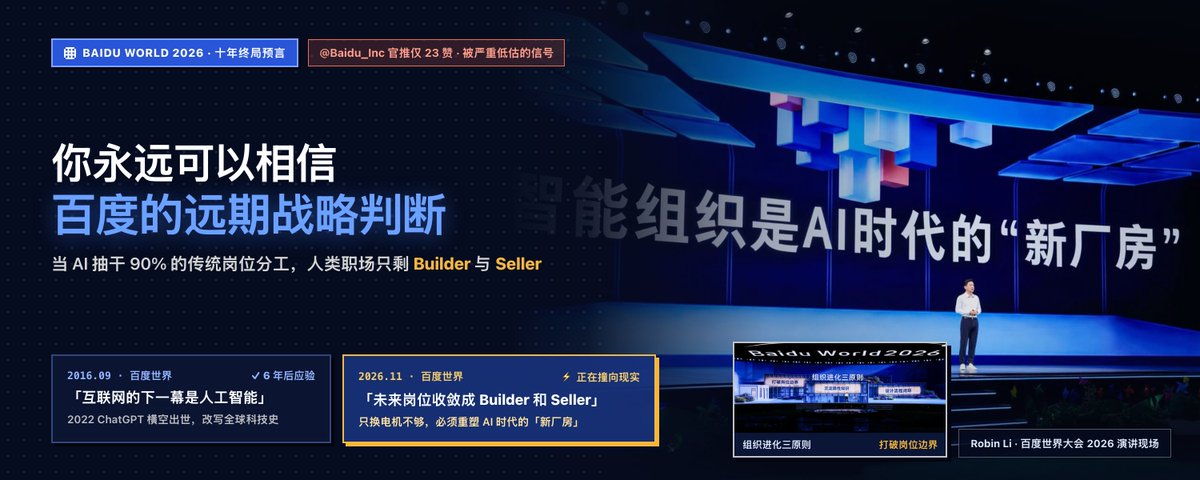
你永远可以相信百度的远期战略判断。
十年前 @Baidu_Inc 的 Robin Li 断言「互联网的下一幕是人工智能」,六年后全世界迎来了 ChatGPT。
前两天他在百度世界 2026 又抛出了一个同等级别的终局预言:未来所有岗位终将收敛成 Builder 和 Seller。
可惜官号那条只有 23 赞的英文推,完全没把这件事真正震撼的地方讲出来。我写了一篇长文,替 @robin 把这个即将成真的未来拆开讲透👇

@Baidu_Inc 的官推完全没讲出李彦宏「未来只剩 Builder 和 Seller」真正厉害的地方,我替 Robin 把这个即将成真的未来拆透了👇
1
3
309

Easily the best health tool I've used. I bought an Apple Watch specifically for Theta, and the latest thing it did was warn me I might be in danger if I keep sleeping 4 hours a day 😂

Sometimes I forget how much we've actually built into Theta 😂
Medical records, wearables, AI, health memory, daily logging, weekly reports... all in one app.
We finally made a longer video showing how everything comes together.
Pretty proud of what the team has built so far.
Still just getting started 🚀
1
2
145

在 AI 工程里,Evals(评测)依然是最被低估的基本功。
【1. 先做错误分析,别先定指标】
拉取 100+ 条线上真实 trace。给每条失败案例写一段自由文本备注(开放式编码,open coding),再把它们归类成不同的失败类别(主轴编码,axial coding)。统计每类出现的频次。排名前 3 的类别,就是你的第一批指标。
【2. 建一个带版本管理的 golden dataset(黄金数据集)】
把输入、预期输出或评分标准(rubric),以及元数据(意图、难度、用户分层)存进带版本的数据集里。做好分层抽样,别让罕见但致命的案例被大量简单样本淹没。把数据集和 prompt 一起做版本管理,保证每次跑出来的分数都可复现。
【3. 按明确维度生成合成数据】
别只让 LLM 笼统地生成“测试问题”。先定义好维度(角色 × 意图 × 复杂度 × 边界情况),组合成元组(tuple),再把每个元组转成自然的输入。这样拿到的是真实覆盖度,免得生出 200 条大同小异的样本。
【4. 优先用确定性断言】
JSON schema 校验、正则检查、必填字段、长度限制、代码执行、在测试库上实际跑通的 SQL。便宜、快、零方差。把基于模型的打分留给代码确实没法检查的地方。
【5. 把检索和生成分开评测】
做 RAG 时,对照标注好的相关切片,用 recall@k、MRR 或 nDCG 测检索质量。用忠实度(faithfulness)测生成质量:每一句结论是不是都有检索出来的上下文支撑?如果只给最终回答打分,根本分不清坏掉的是哪一半。
【6. 给 Agent 做轨迹评测(Trajectory evals)】
记下每一步:工具名、参数、返回结果、token 数。对照参考路径,给工具调用的精确率和召回率、参数准确度、步数以及错误恢复能力打分。明明 3 次调用就能拿到正确答案,Agent 却调了 14 次,这就是成本和延迟 bug。
【7. pass@k 与 pass^k】
pass@k = 跑 k 次至少成功一次。pass^k = 跑 k 次全部成功。单次成功率 80% 时,pass^5 会掉到约 33%。线上可靠性看的是 pass^k,所以要用真实的 temperature 把每条用例多跑几遍。
【8. 用模拟用户测多轮对话】
给 LLM 设定角色、隐藏目标和约束条件,让它跟你的系统对话,直到达成目标或触发轮数上限。重点给目标完成度、解决所需轮数和违规情况打分。单轮评测会漏掉绝大多数状态和记忆 bug。
【9. 像训练分类器一样校准 LLM 裁判(LLM judge)】
手工标注 100+ 条通过或失败的样本。切分成 train/dev/test。在 dev 集上迭代裁判 prompt,再在 test 集上报告 TPR 和 TNR。配合书面评分标准输出二分类结果,要求先写简短评语再给结论,并锁死裁判模型的版本号。
【10. 在成对比较中控制裁判偏见】
LLM 裁判有位置偏见,而且往往偏爱更长的回答。每组 A/B 对比调换顺序跑两遍,只采纳两次结论一致的结果。如果啰嗦的回答拉偏了分数,就对长度做归一化或设上限。
【11. 尊重统计学】
100 条样本、80% 准确率时,95% 置信区间大约是 ±8 个百分点。从 80% 涨到 83% 大概率只是噪声。宣布优化有效之前,先用自助法(bootstrap)算置信区间,或者在同一批样本上做配对检验。
【12. 在 CI 里做发布门禁】
只要 PR 动了 prompt、模型、工具或检索配置,就跑一遍评测集。按类别设阈值,别只看单一总分,免得某一块的大幅提升掩盖了另一块的退化。一旦出现退化就直接挂掉构建。
【13. 在生产环境跑在线评测】
对线上真实流量抽样,异步运行裁判模型,按失败类别监控指标漂移并告警。用影子部署(shadow deployment)在真实流量上测试新 prompt 或新模型,用户完全不会看到测试输出。
【14. 把成本和延迟当成一等指标】
把单次请求 token 数、单个成功任务的成本(注意不是单次调用成本)以及 p50/p95 延迟,跟质量指标放在一起追踪。如果一次改动在保持质量不变的前提下把成本砍掉 40%,这就是实打实的收益,完全值得上线。
【15. 把反馈回路接上】
每一次线上失败,都沉淀成一条新的带标注测试用例。每次有新模型发布,先在全量评测集上跑完,再讨论要不要切换。时间一长,评测集就会变成代码库里最值钱的资产。
Prompt 是消耗品。模型每隔几个月就会换一茬。
真正能产生复利的,是你的评测基建。
Cursor 11 月 10 日上了多人版 Projects,摆在一起刚好是多人 AI 协作的两条路:AI 是向每个人单独汇报、后台同步,还是直接进团队群当同事?
Cursor 选了前者,Mirasim 选了后者:围着同一份需求文档,人和各家 Bot 在同一个话题里,Bot 直接改文档留版本,要拍板时 @ 负责人发选择卡。 xitter.cf/peppashen/status/21204…


1/4
@cursor_ai made Projects multiplayer yesterday: teammates share one Project with a unified context layer and a task board, while their coordinator agents sync across the team.
As a PM at @Mirasim_ADE, I mapped one everyday spec workflow across their post and our setup.
3
132

We have a name for this internally: Team Cores.
Like CPU cores, but for a team: how many tasks you can run in parallel without losing track.
Same frontier model, different core count:
Claude Code / Codex: 10
OpenCode / T3 Code: ~24
Orca: 36
Mirasim: 64

We built Mirasim because we kept losing track of our own coding agents.
Past three or four terminal tabs of Claude Code and Codex, nobody on our team knew which one was done, which one was waiting on a question, and which two were editing the same file.
So now we just tell Mira Bot what needs doing, in a chat. What it fixes for us:
1. One message instead of five tabs. Say "fix the checkout timeout, and add a CSV export", and Mira Bot hands each task to an agent and starts it. Claude Code, Codex and 8 other agent CLIs work.
2. You can see who is doing what. Every task shows its current step in the chat, and the result lands in the same place when it's done.
3. Nothing is hidden. Open a task and it's a normal Claude Code or Codex session underneath. You can keep talking to that agent directly.
4. No second bill. It runs on the Claude or ChatGPT subscription you're already signed into.
It's a desktop app for Mac, Windows and Linux, free with your own accounts. It's still alpha and it isn't open source.
15 seconds of it below (demo workspace, made-up data). If you run more than one agent at a time, what breaks first for you?
mirasim.ai
113
Day one of Fable 5.2, wired straight into a super-agent harness as a team chat bot.
Mention fable-x in the room and it runs commands and ships code from a live workspace while the whole team watches.

grok bot with the brain of fable 5.2
let's see what it's capable of 👀
sign up now 👇 to get $5 in free credits and take it for a spin

65
it's time to "refactor my entire codebase, make no mistakes."

Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
70
Mirasim 的文档功能,已经几乎赶上飞书了,Agent 写文档从没有这么丝滑过

我说实话了,现在不少出海人开发都是Claude Code、Codex几个工具换着用,管理起来确实有点麻烦
有个大佬给我看了个叫Mirasim的工具,感觉挺有意思奥!它不是新的Agent,而是把Claude Code、Codex等多个编程Agent整合到一个工作台里
比如Claude额度蹬完了,可以直接在同一个项目工作区里用Codex,想让两个Agent分别处理不同任务,也可以开多个会话并行跑。项目文件、终端、Git 和代码修改记录都能在工作台里统一查看
我实测了下,这个新手引导真的做的对于我这种开发小白很友好,一键cli直连,页面UI也简洁,新人上手理解成本还蛮低的
另外还支持独立 Git Worktree,多个 Agent 可以在不同分支上干活,减少相互影响。甚至出门在外,也能用手机跟进电脑上正在运行的Agent,跨设备管理更方便了


4
164