
first year cs phd @umdcs, previously ee undergrad, cs masters @NorthwesternU
Joined November 2025
- Tweets11
- Following127
- Followers29
- Likes52



Stephen Cheng retweeted

I'm so freakin sick of how Claude talks.
It's not just annoying, it's infuriating.
The honest evaluation: it's the precise mechanism driving my current headache.
It's the load-bearing root cause of my daily stress.
It's genuinely painful, and that matters.
Stephen Cheng retweeted

If you ask a frontier LLM a multi-hop reasoning question, e.g., "Who won the Nobel Prize for Chemistry in (1900 + Mozart's age when he died)?", it usually can't answer correctly immediately (no thinking)
BUT if you ask the same question & append 300 dots, suddenly it can answer?

Stephen Cheng retweeted

Can LLMs simply tell us about unwanted behaviors they’ve picked up in training?
We train a single Introspection Adapter (IA) that makes fine-tuned models describe their behaviors.
It generalizes to detecting hidden misalignment, backdoors and safeguard removal.

Excited to share my recent work on interpreting LM steering vectors!
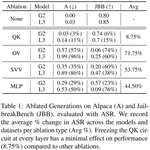
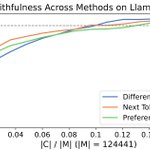
Steering is a lightweight model alignment technique, yet we have a limited mechanistic understanding of how it works. We perform a case study on refusal steering to investigate.
arxiv.org/abs/2604.08524

We focus on the refusal concept due to its strong steering performance and relevance in AI safety, though our interpretability framework is generalizable to any steering concept. I am curious how our findings hold up for steering sycophancy, hallucinations, truthfulness, etc.