
Data scientist | Fractional Chief Data Officer | 3x founder currently building TalentQuill
Canada
Joined August 2009
- Tweets1.8K
- Following233
- Followers680
- Likes704




In the past year, 𝗘𝗬, 𝗣𝘄𝗖, 𝗞𝗣𝗠𝗚, and 𝗗𝗲𝗹𝗼𝗶𝘁𝘁𝗲 have all published reports containing hallucinated citations and facts. The details of what got published are wild ⬇️
→ EY Canada's report on cyber threats in loyalty systems had more than half a dozen footnotes pointing to web pages that didn't exist or didn't contain the information cited.
→ KPMG claimed, among others, that Swiss Federal Railways offers AI agents that "help users plan, book, and optimise journeys based on preferences, real-time conditions and carbon impact." The railway's own spokesperson called that "not accurate."
→ A 237-page report Deloitte produced for the Australian government was littered with AI-generated errors, including a fabricated quote from a federal court judgment and references to academic papers that don't exist. Deloitte refunded part of the $440K fee.
→ A thought leadership report from PwC claimed the governments of Denmark, Saudi Arabia, the US, and Australia were using an AI adoption framework the firm developed. The framework doesn't appear to exist outside the report, and the reports of government adoption were all fake.
Hallucination is the best-known and most common type of AI failure. This isn't something we're just learning about in 2026. Yet all four of these reports made it through internal review, at firms that charge a premium precisely because they're supposed to deliver quality and state-of-the-art thinking.
It's a embarrassing lapse of judgement, governance and quality control.
None of this means you shouldn't use AI for research. I use these tools every day for content/source discovery, synthesis, and report writing. But when you do reach for an AI research tool, you have to check its work... all of it.
I think the fundamental problem here is rooted in expectations. I meet so many people who think AI eliminates 90% of the effort for certain tasks. A research report that used to take 5 days of manual effort can now be generated and shipped in 2 hours with AI. But that's not really true if you're concerned with quality of the output. The reality is, once you factor in evals, verification, re-prompting, and iteration, that 5 days of human-led effort becomes 1-2 days with a human-in-the-loop approach to working with AI.
1-2 days may not sound as exciting as >2 hours, but it's still a real gain in productivity. When you reach for AI, go in expecting it to do roughly half the work and plan to take it the rest of the way yourself.
Links to news articles about the 4 reports:
EY - ft.com/content/a61cbcae-95e4…
KPMG - techcrunch.com/2026/06/13/kp…
Deloitte - ctvnews.ca/business/article/…
PwC - finance.yahoo.com/technology…
Also, fantastic work from @GPTZeroAI for their detection and analysis on most of these
This --> "...[it] almost looks like AI is directing humans to build a world that’s more friendly for machines rather than humans, and most humans don’t even realize they are being manipulated to help with that

opus 5 is a VERY interesting release for a few reasons
1. it showed that the general benchmarks we use today are almost completely useless now
opus 5 is nowhere near fable in practical use, not even close. anyone who’s used it meaningfully can tell this very quickly after a few tasks. yet opus beats fable on many benchmarks
i now trust domain specific benchmarks built with private datasets a lot more than the popular ones. perhaps the future is everyone running their own evals because the public ones are really not telling us much
2. it seems with the 5 series, anthropic is trying a new way of training models
previously, the same generation of sonnet and opus were often released at the same time or sonnet comes out before opus, which indicates sonnet and opus were trained by separate pipelines in parallel
with the 5 series, it was very clear that they trained mythos first, and then distilled it into sonnet and opus. it seems this approach has a big influence on the models
seeing sonnet 5 being a flop and opus 5 getting pretty mixed reviews already, i’m not sure this is working out
3. “how pleasant is it to work with the model” used to be a strength in claude, but now it’s not. honestly, grok is my favorite right now on the “pleasant” dimension. kimi is not bad either
it feels like both anthropic and openai are giving RLHF less care, in favor of scalable RL that’s machine verifiable
this almost looks like AI is directing humans to build a world that’s more friendly for machines rather than humans, and most humans don’t even realize they are being manipulated to help with that
almost every new generation of frontier models now talk more jargons, need more steering to do what you want, and are just less fun to work with
if this continues, AI will start to speak their own language that looks like English but average humans can’t understand. they will choose to do things that their human user never asked for. are we already failing at alignment?
I'll be co-hosting a free workshop on #AIFluency for data practitioners on August 5th.
If you work in data, either as an IC or people-manager, you won't want to miss this. Follow the link for more info and to RSVP ⬇️
maven.com/p/9d0713/ai-fluenc…

So Databricks spent $10 million building an LLM (called DBRX) that plugs directly into their product stack. Why is this interesting? A 🧵

Next, DBRX uses a mixture-of-experts (MoE) architecture. An expert is like a mini app, each tailored to be effective at performing certain tasks (e.g. coding, logic, math, creativity, etc). Compared to other LLM's that use an MoE architecture, DBRX can use up 4 experts at once
I caught a few minutes of the Gartner Data Summit opening keynote on AI, and saw this absolutely outrageous slide.
So all we have to do is “talk” about AI to drive better biz outcomes? Got it.
This is some real “peak of inflated expectations” nonsense

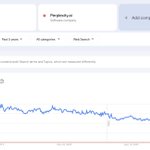
Holy %$!@, look at this chart. Google.com search interest trends vs @perplexity_ai over the last 5 years. G is in trouble

I got ChatGPT to build a fully functional word cloud generation web app in just 30 minutes, without writing a single line of code. In the attached image; left side shows the wireframe I gave ChatGPT, and right side is the live app.
It's crazy to me how good ChatGPT is at writing code from wireframes. But that doesn't mean you won't run into problems along the way. Here are 3 tips I learned from getting ChatGPT to build my word cloud app.
Make your first prompt count
In addition to the wireframe, I constructed a fairly detailed prompt with my requirements. At first, I experimented with a few different approaches to prompting. One approach was to keep the list of instructions and overall prompt short as a way to get the base app up and running; then I planned to iterate it and add new features over time. This approach created a lot of problems because I found that ChatGPT would often completely rewrite its own code from scratch. This meant that when ChatGPT would fix issues or introduce new features, it would redesign and sometimes even break other features that were already working.
So, make your first prompt count by laying out all of your core requirements in one go. It’s okay if the prompt is longer than usual, and you can try using a tool like PromptPerfect to optimize it for the best results.
Know the limitations
For the first time ever while using ChatGPT I reached the token limit in one of my sessions while building this app. This was likely due to inefficient prompting and from uploading log files from Streamlit to analyze errors. But what I learned from this is that if you're using the ChatGPT UI, there are going to be very real limitations, and this means you're probably not going to build the next Facebook app using ChatGPT. Coupled with the fact that ChatGPT is prone to completely re-writing its own code, building scaled applications through ChatGPT can be tricky.
Learn the basics
You may love the idea of getting an AI completely code for you. And that’s all well and good. But you’ll find that having at least a basic coding knowledge in, say, Python can go a long way. Sometimes, ChatGPT will only give you code snippets to make changes, which will require you to know what parts of the code to update. And if you’re 100% reliant on ChatGPT to make every possible code change, no matter how small, you might find that this process doesn’t work well.
If you're interested in reading about how I built the app (or seeing the live app) check out my blog post
analythical.com/blog/how-to-…

I just published my latest ebook! In it you’ll find a comprehensive list of the most important metrics you need to know about for channels like Facebook, TikTok and Google Ads 📈
It’s completely free and you can download it now via this link 👇
analythical.com/blog/ultimat…

My customer journey mapping template made it into @MiroHQ's top 10 Miroverse templates for 2023!
What can you do with this template? 1/3

The Marketing Activation Plan (aka MAP) template is designed to help marketers map out their campaign plan at a high level, and identify key actions and outcomes on each channel. 2/3

You can easily clone my template and give it a try for free, just over to the Miroverse --> miro.com/miroverse/marketing…

Having trouble with Google Analytics 4? Check out my detailed guide on how to build and edit custom reports in GA4 bit.ly/3t62eoG