
AI Efficiency Research @NVIDIA
California
Joined March 2008
- Tweets254
- Following272
- Followers242
- Likes1.1K






Saurav Muralidharan retweeted

1/ Claude Opus 4.5 can wipe its conversation after every single shell command on SWE-bench Verified and still hit 70.2% resolution, matching its 70.0% full-history baseline while cutting peak context from 130K to under 9K tokens. 🧵

Saurav Muralidharan retweeted

Dory1.0-4B: A Looped Normalized-GPT
Dory1.0-4B varies inference compute by looping a shared recurrent block. With two or more loops, it outperforms larger models like Qwen3.5-9B across 12 benchmarks while matching a standard model's KV-cache size.
arxivb.org/abs/2611.03998

Saurav Muralidharan retweeted

"You Don't Need Long Context"
NVIDIA finds that LLM agents can complete complex long-horizon tasks without maintaining their entire conversation history, which reduces inference costs.
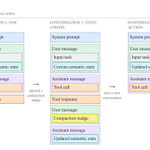
So instead of accumulating tokens, they use frequent context compaction to summarize progress and retrieve information when needed, even resetting the context after every agent action.
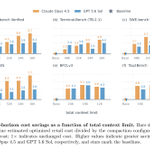
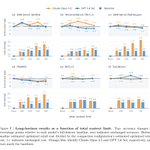
Across six long-horizon benchmarks, this preserves accuracy while achieving up to 8.8x lower estimated inference costs.
alphaxiv.org/abs/2611.05306

Saurav Muralidharan retweeted

🚨 BREAKING: NVIDIA researchers wiped an AI agent's memory after every action.
It still scored 70.2 on SWE-bench Verified.
And the cost math behind it is brutal.
The paper is called "You don't need long context." They ran Claude Opus 4.5 and GPT 5.6 Sol on 13 benchmarks of long coding, agent, and reading tasks.
Here is how it works.
Instead of keeping the whole history, the agent keeps a short note on where it is, then restarts with a clean slate. Long documents sit in files, and the agent searches them with simple tools like grep instead of reading everything at once.
Why bother? Because later tokens cost more. At 256K context instead of 16K, each output token costs 3.6x more on GLM 5.2, 5.6x more on Kimi K2.6, and 7x more on Qwen 3 Coder Next.
Here is what happened:
» Long tasks: accuracy moved between -3.7 and +5.6 points for Opus, and -3.3 and +4.4 for GPT, across 22 setups » Estimated cost: 2.2x to 8.8x lower for Opus, 2.4x to 5.0x lower for GPT » Needle in a haystack: Opus went from 60 to 100, GPT from 80 to 100 » RULER recall: Opus went from 62.5% to 95.7% » AA-LCR: Opus went from 65.0 to 84.0
Less memory made the models better at finding things.
But here is the twist.
They also tried one action per context. The agent forgets everything after each step and only carries a short note. On SWE-bench Verified, Opus scored 70.2 against 70.0 for the full-history baseline. GPT 5.6 Sol scored 82.4 against 84.4.
The biggest context in those runs shrank from up to 200K tokens to between 15K and 37K.
To be fair, this is two closed models. Qwen 3 Coder Next fell from 53.0% to 3.6% on SWE-bench Verified at the tightest budget. The cost numbers are estimates, and the authors say they cannot rule out tasks where long context helps.
Their proposal is a model trained to keep its own written summary. They have not built one yet.

Saurav Muralidharan retweeted

Embodied models don't just think in text, they can think in visual plans, and fast.
Introducing VFlash, System-1 VLM for Physical AI.
Joint work by @YuCheng_Chou_, Shihao Wang and Jin Huang, LPR Team (@jankautz), GEAR Lab (@DrJimFan), and many other collaborators.
🌐 Website: research.nvidia.com/labs/lpr…
🧵[1/8] More details in the thread👇
Long contexts are a massive waste of compute.
Long contexts are expensive. Output tokens cost 3-7x more at a 256k context window than at 16k.
Here’s how to save money.
🧵 1/n


13/n
Stopping contexts from growing is an important step toward local frontier intelligence.
Choose only the networks relevant to the task, feed them only inputs needed for the task, and equip them only with the knowledge necessary to the task, and you will have local frontier intelligence (LFI)
Project Moonshot: LFI: research.nvidia.com/labs/lpr…
2
46
Saurav Muralidharan retweeted

When should an AI agent pass the baton?
🚀 Introducing our work AgentBaton from NVIDIA Research: efficient model collaboration through well-timed handoffs.
We study how capable and efficient models can collaborate without fine-tuning either one: who starts, when to switch, and how to pass context.
🛠️ Our approach: a capable model starts; AgentBaton decides when an efficient model takes over.
The next model inherits the workspace, with history passed in context or through log files. The same detector works across different model pairs.
📈 The results: AgentBaton extends the accuracy–cost frontier. Across 11 model pairs, AgentBaton cuts API costs by 65.9% on average with same or improved accuracy.
📄 arxiv.org/abs/2610.35959
🌐 research.nvidia.com/labs/lpr…
Details in 🧵
#NVIDIA

Saurav Muralidharan retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…