
Computer and low level enthusiast. Learning Artificial Intelligence internals and sharing my learnings. AI Software Engineer at @platzi. Opinions are my own.
Joined February 2012
- Tweets2.7K
- Following859
- Followers2.2K
- Likes8.1K





At @platzi we did the same in 40 minutes.
Watch the classes on Platzi, just create an account: platzi.com/cursos/openai-mat…


Computer created explainer videos for all 722 preprints in OpenAI's mathematical manuscript release, totaling 93 hours of video.
Watch the videos on YouTube: 722.video
Here's how Computer tackled this task:

En unas horas veremos el release de GPT-Sol[Terra,Luna,Sol]

Claude Opus 5.5 takes the top spot on the Artificial Analysis Intelligence Index, along with a 20% price cut and larger cache hit discount
Claude Opus 5.5 brings Anthropic to parity with GPT-6 Astra on evaluations like Terminal-Bench 4.0 and AutomationBench-AA, while extending Anthropic’s lead in agentic knowledge work.
At max effort it scores 58 on the Artificial Analysis Intelligence Index, the highest score we have measured by several points. Anthropic has cut Opus pricing to $4/$20 per 1M input/output tokens (Opus 5: $5/$25) and cache reads from $0.50 to $0.20.
Key takeaways:
➤ Consistent strong performance, with leading scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam 61.4% (previous best 59.1%, Claude Fable 5.1), SciCode 66.9% (63.1%, Fable 5.1), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA. On Terminal-Bench 4.0 it scores 59.6%, level with the leader GPT-6 Astra (xhigh) and +11 points over Opus 5. It remains slightly behind on CritPt, AA-LCR, and GDP.pdf
➤ Leads in agentic knowledge work: On AA-Briefcase, our private frontier knowledge work evaluation, it reaches an Elo of 1822. This is +143 over Fable 5.1, ahead on both analytical quality and presentation, and is the first time Anthropic has reached presentation quality surpassing GPT-5.6 Sol. This evaluation tests whether models can produce accurate and well-presented professional outputs using our open source reference agent harness, Stirrup
➤ Level with Opus 5 on cost per task despite 1.6x the output tokens: Opus 5.5 (max) uses ~119k output tokens per Intelligence Index task, against ~73k for Opus 5 (max), ~78k for Fable 5.1 (max) and ~27k for GPT-6 Astra (max)
➤ Four of five effort levels sit on the Intelligence vs Cost per Task frontier: Opus 5.5 max, xhigh, high, and medium all sit on the Pareto frontier, costing less or outperforming other models scoring 50+ (GPT-6 Astra, Claude Fable 5.1, and Claude Opus 5)
Other model details:
➤ Context window: 1 million token context with image and text input support, unchanged from Opus 5
➤ Pricing: $4/$20 per 1M input/output tokens, down 20% from $5/$25 for Opus 5. Cache writes $5 per 1M tokens for the 5 minute TTL, down from $6.25. Cache reads have been further discounted to $0.20 per 1M tokens, down 60% from Opus 5’s $0.50. This is a 95% discount compared to uncached input pricing, up from 90% on previous Opus models
➤ Effort settings: Five effort settings (low, medium, high, xhigh, and max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled


Jhenner Tigreros retweeted

Little things are comming...
~7 years of intermittent work before the AI solves the problem.


Jhenner Tigreros retweeted

¡El conocimiento se comparte y se transforma! 📣✨
Si te apasiona el procesamiento de lenguaje natural, la neurociencia computacional o el futuro de la IA en nuestra región, este #MiércolesTECH es para ti.
Hablaremos con el equipo del SIMG - UNAL sobre cómo consolidar a Latinoamérica como un referente en el desarrollo de inteligencia artificial generativa a partir del trabajo colaborativo.
📆 Miércoles 16 de septiembre
⏳ 4:00 p. m. a 6:00 p. m.
📍 Centro de Innovación Bogotá
🔗 Inscripciones abiertas aquí: luma.com/cno5gqfx
#CienciaParaLaGente #LAB101 #MiércolesTECH #IAGenerativa #UNAL #SIMG #EducaciónAbierta #TecnologíaLatam

Jhenner Tigreros retweeted

Our group discovered that reasoning models produce fractals when asked to solve hard problems. We can use nonlinear dynamics to probe the thinking processes of recurrent depth models on Sudoku, mathematics, and even ARC-AGI (1/N)
arxiv.org/abs/2609.04963
Jhenner Tigreros retweeted

friends are regularly surprised when i say i don’t think math is (yet) “solved,” so in the wake of the ns result i figured i’d explain this take a bit more widely.
first, this is massively impressive and clearly an example of AI being, in some respects, far more powerful than the human mind. the team deserves huge praise for attempting and succeeding at this. i’d love to read a technical report on the project (one can always hope :)
but second, here again we ended up with a counterexample rather than a full proof: option C won the NS problem by proving the conjecture false (which was one valid way to solve the problem for sure)
notice a pattern in many of the recent frontier results in ai for math? a striking number involve counterexamples or finding a needle in a haystack.
now don’t get me wrong: this is extraordinarily hard and commendable. but it is only one aspect of mathematicians’ work.
Math is also about:
- finding deep, general mathematical understanding and explanations within proofs
- revisiting proven results to find more « elegant » proofs
- proposing new conjectures and hypotheses that might open « fruitful » directions
- taking the leap of faith of proposing entirely new, « exciting » research programs that may take decades to bear fruit
you may say these are simply further increments on the same intelligence scale, and perhaps point 2 above is already within the reach of current models. possibly
but you could also see this string of results as an extraordinarily powerful, massively parallel extension of search: explore the haystack, find the needle i.e. the counterexample that breaks the conjecture.
that would already be remarkable. but it would still leave open whether models understand the words I emphasized above: « elegant », « fruitful », « exciting ».
as tristan put it in his brief report: “the first llm generated proof levent sent me was the most horrendous i have ever read.”
despite their formidable technical abilities, models still seem to lack something mathematicians rely on constantly: a type of mathematical taste. the ability to distinguish a beautiful argument from a merely valid one, a fertile idea from a sterile one.
i’d be very curious to ask gpt or claude what they think of the result they just proved. do they find it elegant? if they ignore all the human noise about it on the web and history of math, do they appreciate the result and the path to it more than other proofs?
my suspicion is that, outside of the human knowledge that this is an important millennium prize problem, it may not 100% register it as fundamentally different from thousands of other proofs.
or, more intriguingly, perhaps the beauty they find in mathematics is actually alien to our own sense of mathematical beauty, some « horrendous » proof to us might be deeply satisfying to them…
all this to say that we might have significant progress to make in ai for math before declaring the field “solved,” (as too many are posting).
in the meantime, ai will be an extraordinary collaborator for mathematicians. i just hope access to these tools be as widely shared as possible (so that you don’t need a Leven or Sebastien working in a big lab to help you), and that companies stop using mathematics primarily as a demonstration of prowess in their private race.

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

Leyendo Por el camino de Swann me encontré con la palabra aparceros (p. 203, 1 Edición, Alfaguara), buscando un poco en internet encontré que está puede ser uno de los orígenes de la palabra parcero junto con la palabra portuguesa parceiro, y que son primas hermanas de la palabra en latín partiārius (que significa “partícipe”) la cual sería su raíz.
Esto me llevo a preguntarme. ¿Existe alguna plataforma donde uno pueda ver la etimología de una palabra concreta, incluso si es un jergalismo? Últimamente me estoy interesando mucho en ese tema, pero no tengo idea de por dónde iniciar. Este interés surgió hace unos días cuando empecé a darle una ojeada a Guerra y Paz de Lev Tolstói (y en general autores rusos) y vi la cantidad de mezcla de Francés, Inglés y Alemán que tienen en sus obras —debido a su contexto histórico, gracias Figes— y quisiera poder leer un poco más informado, en algunas de mis ediciones me ha tocado hacer traducciones de esos idiomas y pues trato de hacerlas a punta de diccionario (no confío tanto en Google Translate para este fin). ¿Alguna recomendación? Sé que compartimos mucho con estos idiomas y el Español, pero no sé qué tanto.
Hoy terminé la lectura de El Ojo del Mundo, de Robert Jordan (La Rueda del Tiempo).
Siempre he amado a los autores que no tienen miedo de hacer descripciones extensas de las cosas más simples de su mundo: las ropas, su gente y hasta los pasajes en los que describen la orografía. Lo puedo describir como una combinación de Brandon Sanderson —quien finalmente terminó La Rueda—, con su worldbuilding, y Joe Abercrombie, con sus arcos de personajes.
Sabía en lo que me metía cuando decidí empezar esta saga, pero no esperaba que los últimos tres capítulos, en especial Sin Principio ni Final, me engancharan al punto de que no me importara nada más que continuar leyendo y quedar ad portas de un gran acontecimiento, con esa última sentencia de uno de los personajes que más intriga me ha generado en la fantasía épica (claro está, después de Dalinar).
He sido un ávido lector de fantasía y ciencia ficción desde que tuve acceso a internet y jamás había sentido tal nivel de involucramiento en una obra de este tipo —hablando de una saga completa; para mí, Juramentada, de Brandon Sanderson, fue un antes y un después en mi vida—. Esa extraña sensación de que algo se cierne; volver a ciertos capítulos con la vaga idea de haber leído algo que puede estar conectado y ver cómo el entramado se cierra a medida que el autor te da más y más migas de esa gran aventura.
Ahora, dejaré asentar la historia, los sentimientos y las cavilaciones que generarán teorías en mi cabeza, que luego veré si son ciertas a medida que avance hacia el final de esta gran aventura. Estoy seguro de que, en un par de años, cuando termine y vuelva a mis notas y a la relectura, tendré el mismo sentimiento que cuando leí por segunda vez El Archivo de las Tormentas y me di cuenta de cómo todo había sido dicho en frases y diálogos sueltos a los que mi yo del pasado les dio poca o ninguna importancia.
Viaje antes que destino
Hoy en platzi.com/live, a las 4:20 p. m. (hora de Colombia), estaré probando una nueva idea.
Analizaré en vivo papers relacionados con cómo se construyen los últimos modelos Open Source, la intuición detrás de las innovaciones en la arquitectura, la matemática que nos ayuda a representar esas ideas y cómo todo es un conjunto de pequeñas iteraciones que luego necesitan ser expresadas en infraestructura e ingeniería a unas escalas que ni imaginamos.
Hoy: Kimi K3: Open Frontier Intelligence (alphaxiv.org/abs/2607.24653)
Parte 1: Arquitectura del Modelo.
Lo haré cada 8 días, en el live y en el mismo horario, hasta que acabemos el reporte en su totalidad.

Jhenner Tigreros retweeted

We're open-sourcing Mixture-of-Kittens (MoK), our MoE training megakernel for NVL72s.
It fuses all Mixture-of-Experts communication and computation into a single, fully deterministic kernel, and runs up to 2.37x faster than the strongest public baselines.

ALT Bar chart: Mixture-of-Kittens reaches up to 2.37× higher MXFP8 forward throughput than the fastest public baseline on GB300 NVL72s, across Kimi K2.7, GLM 5.2, Qwen 3.5-397B-A17B, and DeepSeek V4 Pro.
Jhenner Tigreros retweeted

Everyone should own their Model Routing calibrated using their own Evals
it should be fully transparent and tunable to your tasks not an average of everyone hitting some API!
universal per request model routing is a myth and doesn’t make sense to me. it’s a low context, nearly impossible text classification problem of “complexity”
you can’t apriori accurately determine task complexity from a text snippet
rapidly creating Evals & testing different Model Routing for your domain feels like the only legit way forward
the correct granularity for routing is at the Task/Sub-Task/Workflow level.
Ex: “fill out this browser form as part of my medical onboarding to a new practice”
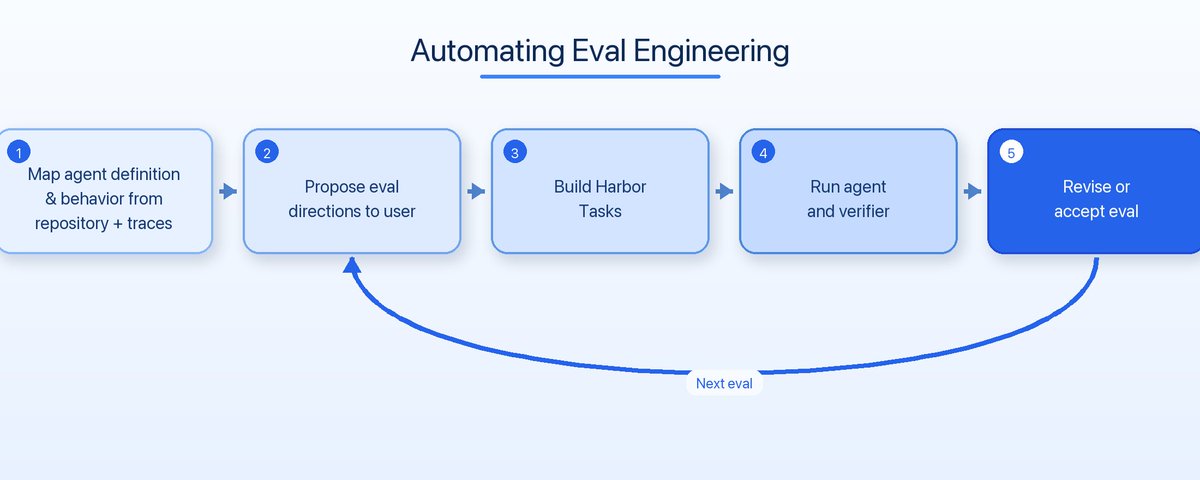
the best way to measure if a cheaper model can do your sub-task is to mine your Trace data & interview your builders to create Evals/Tasks that your agent will need to be good at
Our Skills are free and can help you own everything
then test a series of models to see if they can reliably pass those evals -> ideally cheaper models work but find out for yourself backed by your data
During execution orchestrator and verifier can choose to dispatch some work to cheaper models and escalate if needed via handoffs and subagents
calibrate and understand routing with respect to your Tasks and Evals, not behind some API with opaque blended costs and model choices
we want to help everyone own their modem routing and see that it’s a super data dependent exercise
you’re not the product of everyone’s routing requests, neither is your harness, your data is the key to owning to it and every team should feel empowered to use it to tune their routing, harness, and agent design


¿Quién será el asesor de TIC que le estará diciendo a Petro todo lo que anda publicando y qué seguramente se está ganando $50M COP al mes? No más por saber y preguntarle si de verdad cree todo lo que anda publicando o solo es por ganarse la papita.


Ahora voy a presentar los algoritmos que hacen vulnerable el software de los hermanos Bautista y que permiten que estados poderosos con capacidad computacional puedan reemplazar a colombianas y colombianos
Cómo no se dejó auditar el software no se descubrió está terrible vulnerabilidad y se prefirió una derrota posible derroya pírrica del progresismo a cambio de la soberania nacional. Píeeica porque elmprogresismo es ahora más grande que cuando el pueblo me eligió lo cual demuestra mucha gratitud y reconocimiento del pueblo de Colombia que no nos ha quitado poder de la palabra sino más poder.
Ahora invito formalmente al presidente Donald Trump, a hablar porque a la situación creada en Perú, Colombia y Venezuela creo que hay que meterle mucha sabiduría antes de propiciar una inestabilidad que tendría mucha sangre humana y un empoderamiento del narcotráfico como nunca.
Aquí para la historia.de Colombia dejo los algoritmos existente que permiten la vulnerabilidad externa del software.
Ya se sabe que los algoritmos que suspendieron de la metabase del E14 como
La estampilla de la historia y el candado Hash si permitieron cambiar formularios E14 ya puestos.
Ya sabemos que algunos jurados del exterior que no podían ser jurados residentes en Colombia sin anular lo hecho en las urnas eran residentes de Colombia
Ya sabemos que entraron millones de dólares del exterior invertidos en desprestigiar al gobierno, a mí al Pacto histórico y a Iván Cepeda, que le hicieron creer a millones de colombranos que Iván era guerrillero cuando nunca cogió un arma, y solo investigo el asesinato del su padre senador hasta saber el autor oficial y funcionario público y eso lo llevo como a mi, por ser parresiastas a averiguar los culpables del genocidio del pueblo humilde de Colombia.
Aquí pueden leer un poco difícil y para que quede en al historia de estos días, y aprenda el pueblo a unirse y defender sus intereces, los algoritmos vulnerables del software privado de los hermanos Bautista.

Vean, yo no le voy al ganador del preconteo, pero esto que hace Petro acá es simplemente seguir dañando la imagen de Cepeda.
Primero que todo, el primer archivo claramente dice "PAGINA NO DIGITALIZADA" y luego cuando lo vuelve a descargar ya tiene los datos de los votos, eso quiere decir que el contenido de los archivos cambio por ende el HASH va cambiar, ya que es derivado del contenido del ARCHIVO. Es tán facil como buscar la documentación de la utilidad de powershell que están usando (learn.microsoft.com/en-us/po…) y LEER para darse cuenta. Aunque también les digo, cualquier persona con conocimientos de Software simplemente viendo los archivos sabría que el HASH sera diferente.
Esto es lo que le hace daño a la democracia, a las instituciones y al pueblo. Ha sido muy triste ver el descenso a la locura de una persona que a mis ojos antes de ser presidente era tan respetable, elocuente y consecuente con sus ideales, lastima que el poder le nublara el juicio y se rodeara de tan detestables personas.

Le pedí al registrador, y al procurador la accion positiva a mi solicitud, que permitieran la auditoría técnica del software antes de primera vuelta y en segunda vuelta demandé que se recuperara inmediatamente el candado Hash y la estampilla del tiempo, para asegurar que no se cambiarán los formularios E14 después de subirlos, tal como se hizo en mi elección.
Pues me dijeron loco y antidemocrático, cómo si la transparencia electoral fuera cosa de violentos que quieren incendiar el país.
Lo que incendia es la falta de transparencia electoral.
Aquí se demuestra que muchos formularios E14 fueron cambiados después de subirlos y que efectivamente, contrario a lo que dijo el registrador, quitaron la estampilla del tiempo y el candado Hash de los algoritmos para cambiarlos premeditamente y desde las oficinas de los hermanos Bautista.
Esto es ya un asunto penal, un delito contra el voto.
Los testigos digitales, institución popular creada en estos días por ciudadanía y con alta experiencia informática.
Cómo dice el video que demuestra este delito, creyeron que somos brutos y olvidaron que con nosotros está la ciudadanía del siglo XXI y no la del siglo XIX, en la que aún está la registraduría haciendo trampas para amigos politicos por dinero, pero que no pensó que esa práctica iba a llegar a la pérdida total de la soberanía nacional.
Toca hacer el conteo digital de los 122.000 formularios E14 y testigos digitales debe fortalecerse con más expertos digitales.
El registrador causó una gran herida en lo profundo del corazón de Colombia y un daño que la historia no borrará.
El software de los hermanos Bautista tal como dijo la sentencia del consejo de estado del año 2018, desacatada, es vulnerable a acciones internas y externas contra el voto.
Más adelante mostraré con exactitud en que sistemas algorítmicos del software de los Bautista están las fallas que permiten que sea atacado desde afuera si el atacante tiene la capacidad computacional posible con un estado/ nación con dinero para ello.
Creyeron que se trataba la soberanía nacional de un juego de izquierdosos y esa es la base de una nación, pued cuyas élites burocráticas de hace 200 años no se sienten colombianas.
Un acuerdo nacional implica la reforma profunda del sistema electoral colombiano para garantizar la transparencia y la soberanía, lo demás es traicionar la idea inicial por la que se fundó la república.

Jhenner Tigreros retweeted

“Quien estará haciendo ruido a las 2 de la mañana”
Yo celebrando el cuarto gol de Japón: xitter.cf/futvideos_/status/2066…