co-founder @deepmark_me (YC F26)
Montenegro
Joined January 2022
- Tweets514
- Following175
- Followers206
- Likes7.6K


Pinned Tweet
Today we launch @deepmark_me (@ycombinator F26). We put an inaudible ID inside an AI agent's voice, so the person on the other end of a phone call can verify who is really speaking. Here is me doing it live, on one phone.
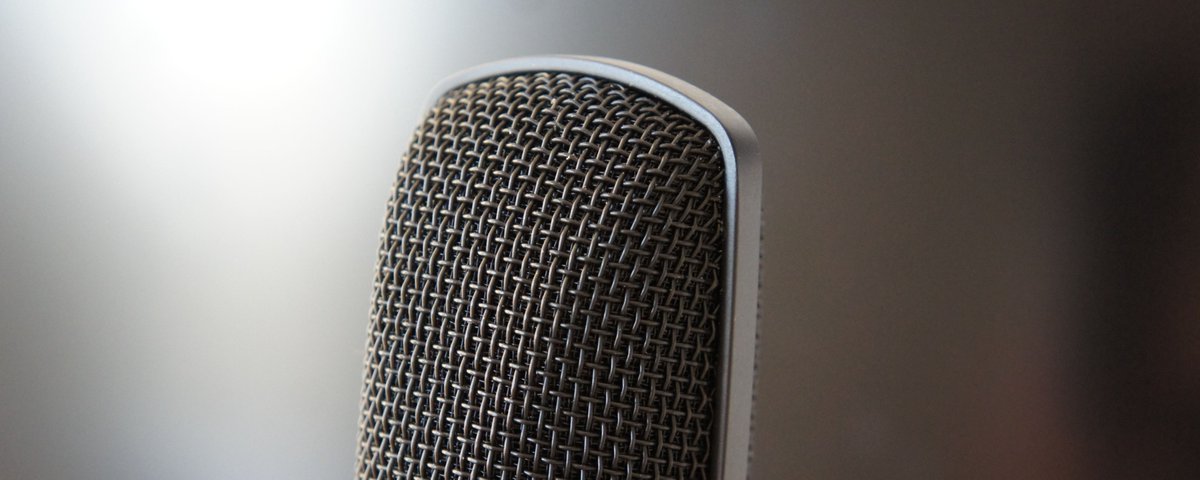

When partners integrate DeepMark, they get our models and a team dedicated to making watermarking work over the long term.
That means tackling the technical challenges and regulatory headaches that come with it, including problems that may only surface years after deployment.
Model upgrades are one example. How should watermarking evolve as the models themselves change? It’s a challenge we’ve been working on for some time.
Today, we’re sharing our initial findings with the wider community, so others can learn from our work and help move the field forward.
Free to read. Enjoy!
arxiv.org/pdf/2610.22296
Slavko Kovačević retweeted

our agent security checker catches goal hijacking, misalignment and injection, right on your machine, 1.9ms median.
we raced it against Jev on a hard set of 25 agent attacks and 25 benign docs. Jev took 167.6ms and scored 80% accuracy, our model scored 98% while being over 88x faster.
if every agent tool call needs a security check, it can't add a network round trip each time.
Armorer Flash, recorded live at real speed
You can now try our open-source AWARE with just pip install aware.
It uses training-free watermarking through adversarial optimization. Its detector starts with random weights and stays frozen. The optimization adjusts each recording so the detector reads the intended bits.
I wrote about why we built DeepMark Vigil, how it compares with Meta’s AudioSeal, and what it takes to watermark speech in real time.
deepmark.me/blog/deepmark-vi…

One of the new audio watermarking benchmarks (and a good one!) compares 10 SOTA open-source algorithms. Two are ours. Check it out: iuaspirelab.github.io/Audio-…

Slavko Kovačević retweeted

We’re on a mission to build a billion AI models, not trained by us, but by you.
Introducing @bryel_labs we help your company build its in-house AI lab and give you the software to make model development and continual improvement simpler. We are backed by @ycombinator and have trained models at Apple, Framer, and F500s.
We’ve enabled companies to train:
• Classification models that are 20x faster
• Search models that cost 5x less.
• Long horizon agent models that match the frontier at 5-8x lower cost.
Are you interested in partnering with us? Reach out.
bryel.ai/
Detecting a watermark through a recording is extremely hard. We call this an "over-the-air" attack. You record audio on a different device. It passes through the air, gets resampled, compressed, edited, and picks up noise along the way.
I had a call with a bank yesterday. Had to verify myself through the app and an SMS code. Even then, an automated message said that the bank would never reach out on its own to help. So much friction. We can solve this. Our product is HTTPS for voice.
Everyone hated @AnthropicAI for watermarking their text. Now, @OpenAI does the same. They have to, the deadline to comply is December 2nd. Content provenance is the future. Let us know if you need help with it.
openai.com/index/eu-text-pro…

I received a call today from a Dasher, and Apple flagged it as "probably spam". That is funny because, like an hour before that, I received an actual spam call, and it passed a filter 😆
“It’s just watermarking.”
We’ve spent six years on it. Here’s why hiding a mark in AI voice and making it survive a phone call is harder than it sounds.
Pope is pitching our product. Let him know that all we need to solve it is DeepMark.

In this era of artificial intelligence, it is becoming urgent to distinguish human art from what machines produce. There is an ontological difference, even before an aesthetic one, between art and what a machine can generate through statistical calculation based on millions of images created by others. Algorithms lack the spark of humanity. For this reason, the Church wishes to renew an alliance with artists and cultural institutions to safeguard our humanity.
Awesome progress! Love it or hate it, technologies like these are only going to improve. What I think is fair is that we should always have the right to know whether it's AI or not.

The whole point of building Tavus has been simple: talking to a machine should feel as natural as talking to a friend or coworker.
It’s hard to describe all the tiny nuances that make a conversation feel human. The little expressions. Moving around in your chair. Knowing when to speak and when to listen. The dance of it all.
Griffin is by far the closest anyone has come to a model that can capture those nuances. The first time I saw it being used, I had no idea I was watching our model rather than just a normal video call.
I’m so incredibly proud of this team and what they’ve built.
A blog post about Masha, Nikola Tesla, and the 46th FIDE Chess Olympiad. Don't miss it.
deepmark.me/blog/masha-and-a…

We open-sourced phonesim. Put any audio through a simulated call. Real codecs (Opus, AMR, G.711, G.722, G.726), packet loss, jitter, clock drift. Seeded and reproducible.
pip install phonesim
github.com/deepmark/phonesim