



/MachineLearning retweeted

guys you do know you can just disable thinking, and instead give it a "deep_think" tool, and it will call it with internal CoT reasoning format right?
gl fixing that


SSSI - Straight Shot to Super Intelligence

We are announcing a long-term strategic partnership with NVIDIA. NVIDIA is making a substantial investment in SSI that will let us 10x our compute in the next 12 months. We reached the point where our research is worth scaling and with this partnership we will be able to. We are honored by NVIDIA’s conviction.
/MachineLearning retweeted

hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final
((1+xy)^3 z + y^2 (1+xy) (4+3xy), y + 3 x (1+xy)^2 z + 3 x y^2 (4+3xy), 2 x - 3 x^2 y - x^3 z): \C^3\to \C^3, has jacobian determinant -2, and sends (0, 0, -1/4), (1, -3/2, 13/2), and (-1, 3/2, 13/2) to (-1/4, 0, 0)
Self-serving statement from OpenAI employee about open source: Open source won't concentrate enough power into a handful frontier labs to build out the next model.

Crazy that there are people in this world that think only Anthropic and OpenAI can produce state of the art models.

All of these debates ultimately boil down to one point.
If the money flowing into OpenAI and Anthropic dries up, this entire investment cycle will eventually grind to a halt.
If OpenAI and Anthropic can no longer produce frontier, state-of-the-art models, the Chinese open-source models that distill them will stagnate as well. Do you see, then, how naive it is to claim that hyperscalers can simply take Chinese open-source LLMs and resell access to them through APIs?
We have already boarded a train we cannot get off—one that leaves us no choice but to keep pouring money into OpenAI and Anthropic as it races forward.
Ultimately, someone has to buy vast numbers of GPUs and build AI the expensive, inefficient way—not the Chinese way.

/MachineLearning retweeted

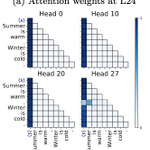
J-Space introduced by Anthropic is pretty cool. Our paper in ACL 2019 (aclanthology.org/P19-1144.pd…), however, showed that the hidden states of intermediate layers in language models contain the information of not only the next token, but the following sub-sequence based on semantic dependency.

/MachineLearning retweeted

Excited that our ICML position paper has been accepted as an Oral 🎉!
When a model looks like it "deceives" or "resists shutdown," how do we know it isn't role-play, instruction-following, or just task-completion pressure? Often the current evidence can't yet tell them apart, and those claims are starting to inform deployment and regulation.
We map where the evidence gets thin across four stages and propose a shared standard to strengthen it. Here's the map.
🧵
arxiv.org/abs/2606.07612

/MachineLearning retweeted

The new model and the cybersecurity 'product' are separate, and only the cybersecurity specialized model will have limited release, not the new model itself. So it looks like a general public release for Spud.


/MachineLearning retweeted

The TurboQuant paper (ICLR 2026) contains serious issues in how it describes RaBitQ, including incorrect technical claims and misleading theory/experiment comparisons.
We flagged these issues to the authors before submission. They acknowledged them, but chose not to fix them. The paper was later accepted and widely promoted by Google, reaching tens of millions of views.
We’re speaking up now because once a misleading narrative spreads, it becomes much harder to correct. We’ve written a public comment on openreview (openreview.net/forum?id=tO3A…).
We would greatly appreciate your attention and help in sharing it.

Introducing TurboQuant: Our new compression algorithm that reduces LLM key-value cache memory by at least 6x and delivers up to 8x speedup, all with zero accuracy loss, redefining AI efficiency. Read the blog to learn how it achieves these results: goo.gle/4bsq2qI
/MachineLearning retweeted

We scored 36.08% on ARC-AGI-3 in one day using the Agentica SDK.
Readers added context they thought people might want to know
The title is misleading, this score is for the public demonstration set - quoted as being "intentionally easier for both humans and AI, with a stronger emphasis on clarity and fun".
arcprize.org/media/ARC_AGI_…


/MachineLearning retweeted

The main goal of Bayesian ML research is to show that all methods which have previously been shown to work well in practice are somehow approximately Bayesian

Transformers are Bayesian Networks
arxiv.org/abs/2603.17063

/MachineLearning retweeted
Anthropic is resuming negotiations with the Pentagon for a deal on artificial intelligence, according to FT report.


